Types of AI Agents: Coding, Browser, Research, Video
Types of AI agents explained: how coding, browser, research and video generation agents work, what permissions they need, and where each one fails.
Contents9 sections
- What makes the types of AI agents different
- Coding agents: working in your repository and terminal
- Browser agents: seeing the screen, clicking and typing
- Research agents: search, read and write a cited report
- Video generation agents: from brief to assembled scenes
- Comparing access and risk across agent types
- How to choose the right agent for a task
- Frequently asked questions
- Sources and references
Key takeaways
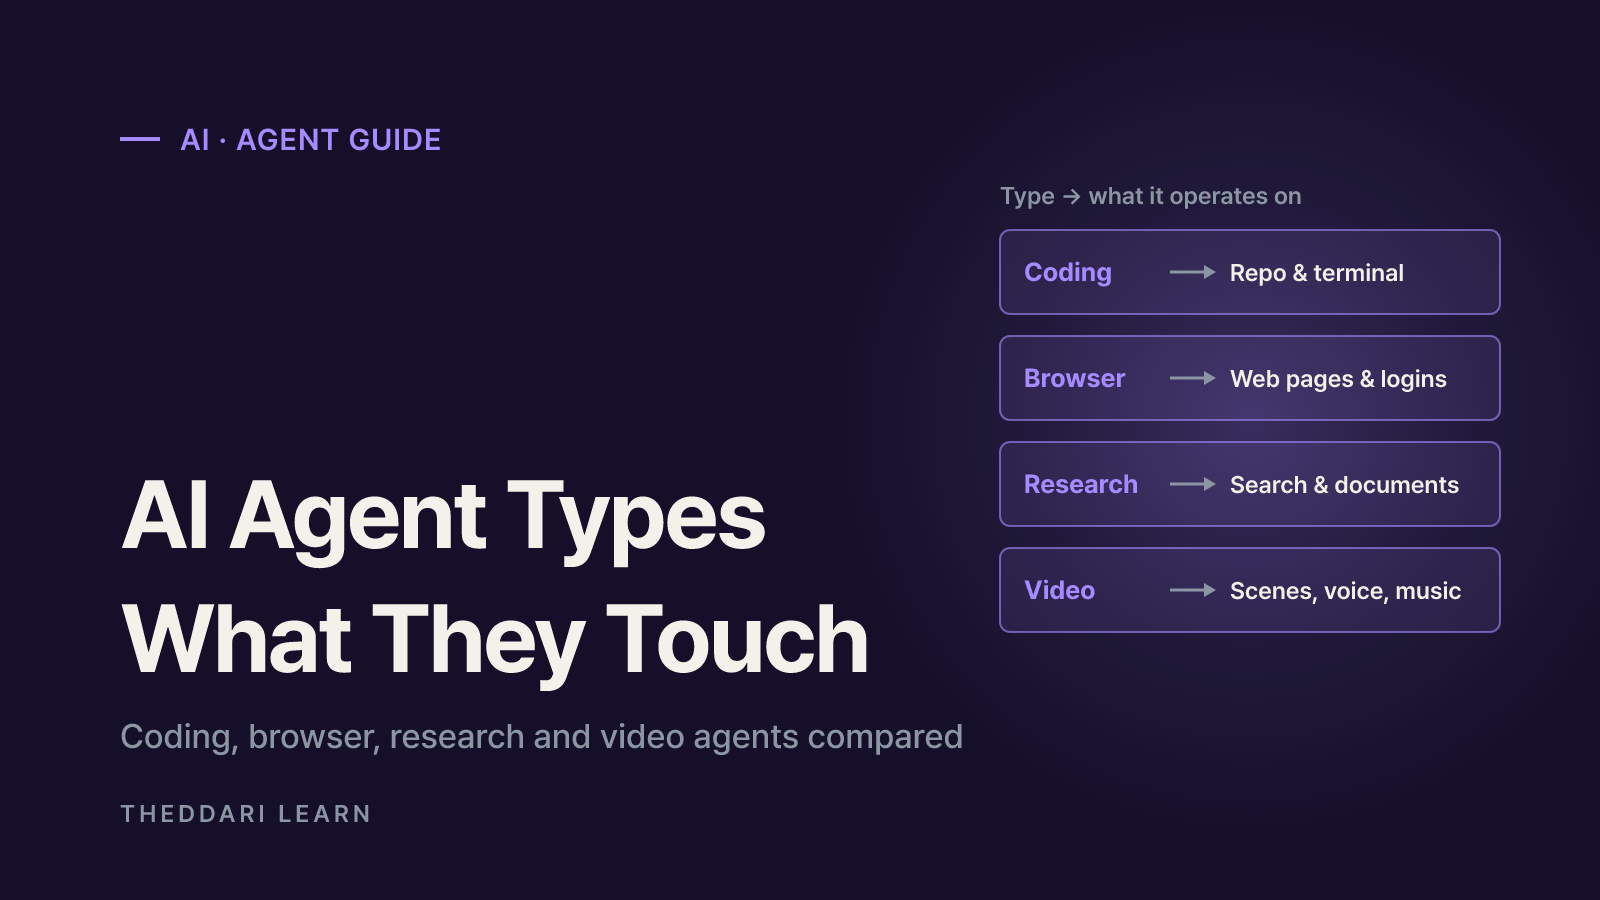
- An AI agent is a model that uses tools in a loop, reads the result and decides its next step. The practical way to tell agent types apart is by the environment they operate in.
- Coding agents work in a repository and terminal, browser agents in web pages and accounts, research agents in documents, and video agents in generated scenes, voice and music.
- Risk depends on access more than intelligence: read-only work, local file edits and irreversible actions such as payments or deployments need very different safeguards.
- Official documentation from Anthropic, OpenAI and Runway consistently points to human confirmation, narrow allow lists and checking real outcomes rather than trusting the final message.
The clearest way to sort the types of AI agents is not by brand but by what the agent is allowed to operate on. Coding agents work inside a code repository and terminal. Browser agents read and click through web pages, often in accounts you are signed in to. Research agents search, read and summarize documents. Video generation agents plan and assemble scenes, voice and music. Because each one touches something different, each needs different permissions and fails in different ways. This guide, checked against official documentation as of October 2026, compares the four categories by how they work, what access they need, typical uses and their limits. It is not a product ranking or a pricing comparison.
What makes the types of AI agents different
Start with a working definition. In Building effective agents, Anthropic separates workflows, where models and tools follow predefined code paths, from agents, where the model dynamically directs its own process and tool use. The same article describes agents as, in practice, models using tools based on feedback from their environment in a loop: edit a file and read the test output, click a button and look at the new screen, run a search and decide the next query from what came back.
That loop is shared by every category. What changes is the environment, which determines what the model sees, which actions you must allow and whether a mistake can be undone. Three questions are enough to place almost any agent product:
- What does it observe? Code and command output, rendered web pages, retrieved documents or generated media.
- What can it change? Files on your machine, a signed-in web account, nothing at all (read-only), or newly generated content.
- Can a mistake be reversed? A local file edit is usually easy to roll back; a payment, a booking, a deployment or a public post is not.
Products often blend categories. A coding agent may search the web, a research agent may open pages in a browser and a video agent may look up references. Treat the label on the box as a hint and check which tools are actually switched on.
Coding agents: working in your repository and terminal
A coding agent reads a codebase, edits several files and runs tests or builds to check its work. Claude Code's documentation describes the loop as three blended phases: gather context, take action and verify results. Asked to fix failing tests, it might run the suite, read the errors, search for the relevant source, edit it and run the tests again. Its built-in tools fall into file operations, search, command execution, web access and code intelligence.
The access is broad. According to the same page, Claude Code can reach files in the directory where it runs, any command you could run in your terminal and your git state. Permission modes therefore matter. Manual mode asks before edits and shell commands, accept-edits mode lets it change files and run common filesystem commands without asking, plan mode explores without editing source files, and auto mode uses a background classifier to block risky actions instead of prompting you.
Claude Code checkpoints can rewind file edits, but the documentation states that actions affecting remote systems such as databases, APIs and deployments cannot be checkpointed. Keep allowed commands narrow wherever production credentials are reachable.
Anthropic explains why coding suits agents well: solutions can be verified with automated tests, test results provide feedback for iteration and output quality can be measured fairly objectively. It also notes that passing tests is not the whole story, and human review is still needed to make sure changes fit the wider system.
Browser agents: seeing the screen, clicking and typing
A browser agent operates websites the way a person does: it reads pages, presses buttons and fills in forms. Its value is reaching sites that have no API or that only show information after sign-in. OpenAI's computer use guide describes the capability as letting a model operate a browser or desktop interface to fill out forms, test user flows or complete tasks in an application, either from screenshots with mouse and keyboard actions or by reading page text and controls. For public information that needs no interaction, it points developers to web search instead.
On the consumer side, the ChatGPT cloud browser help article shows how these agents are usually fenced in. ChatGPT Work gets its own browser on a separate cloud computer, can keep going after you close your laptop and pauses when it needs input, sign-in or confirmation. OpenAI lists it for paid plans in supported regions, excluding Free and Go. Example tasks include checking restaurant availability, comparing flights and comparing utility plans.
- Site access: by default it asks before visiting a new website; an always-allow setting exists but is marked as not recommended.
- Consequential actions: it is designed to ask in chat before steps that are hard to reverse or create financial, legal or account commitments, such as confirming a booking or making a payment.
- Sign-in: credentials typed into the secure sign-in form go to the remote browser and are not visible to the model.
- Limits: some websites block automated browsers, in which case you may need to take over and finish the task yourself.
The distinctive risk is that text on a web page can be read as if it were an instruction. OpenAI says it tests for prompt injection, phishing and unintended actions but that these safeguards do not remove every risk. Stop the task if the agent opens the wrong site or uses wrong details, and check the result and its sources before relying on it.
Research agents: search, read and write a cited report
A research agent takes one question, runs many searches, reads what it finds and synthesizes a report with citations. Unlike a quick search answer, it plans the work and changes direction based on what it reads. OpenAI Academy's deep research guide describes deep research in ChatGPT as a research agent that scans many sources and produces a structured report with citations.
Its access is mostly read-only. The guide says connected apps are used with read access, that you can restrict or prioritize specific domains, and that you can watch the running plan and interrupt to narrow the scope or add sources. Nothing gets deleted or purchased, so the blast radius is small. The risk is different in kind: a confident, well-cited summary can still be wrong, and it may end up driving a decision.
That is why the guide asks users to validate key claims before decisions or external publishing. Ask the agent up front to flag weak or conflicting evidence, then spot-check that quoted passages exist in the source and that dates match your question. Only connect internal sources you are authorized to use, and follow your organization's data-handling rules.
Video generation agents: from brief to assembled scenes
Stories of a single sentence turning into a short documentary have drawn attention to video agents. A plain text-to-video model usually turns one prompt into one clip; a video agent runs the production in stages. Runway's announcement of Runway Agent in May 2026 describes a flow where you explain what you need, the agent proposes a concept, story beats and visual direction, you refine it in conversation, and it then builds multiple scenes with voiceover, dialogue and music. You can upload reference images, choose aspect ratio and duration, set audio preferences and finish adjustments in a timeline editor.
This type does not change your files or accounts; its main power is producing a lot of new content. The checks are different as a result. Regenerating scenes adds usage quickly, so read the pricing or credit rules first. Using a real person's face or voice, logos or someone else's work as references can create legal problems once the video is published. Facts spoken in a documentary-style narration were written by a model and need independent checking. Platforms may also require you to label AI-generated media when you post it.
Comparing access and risk across agent types
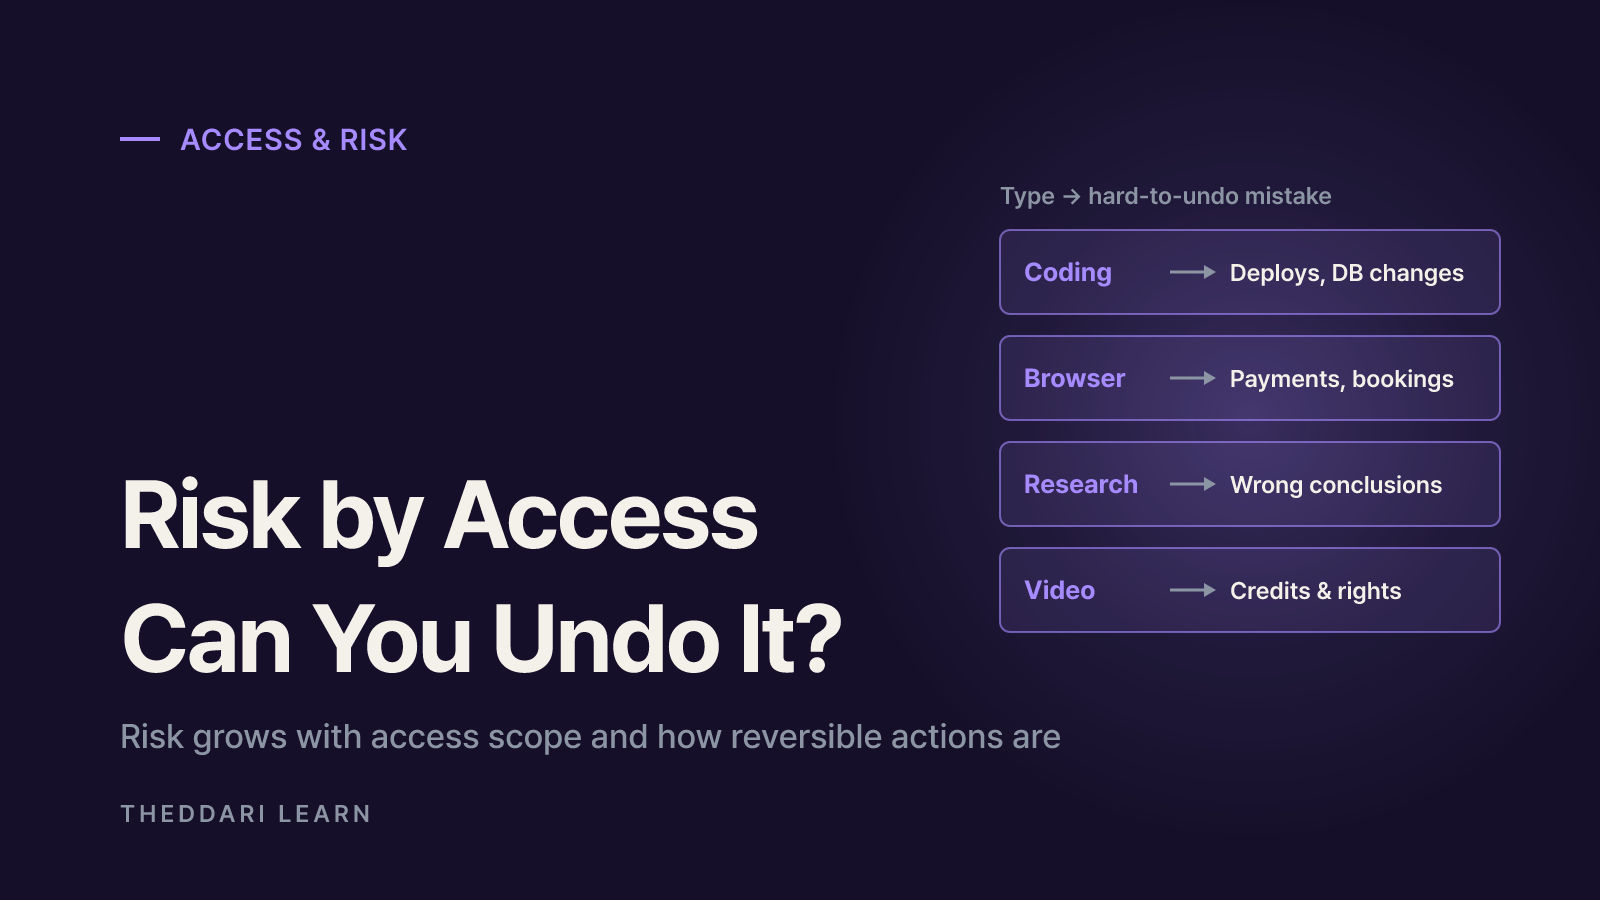
Side by side, the differences become clear. The table reflects the general structures described in official documentation as of October 2026; individual products and settings vary.
Coding agent
- Mainly observes
- Code, command output, tests
- Mainly changes
- Local files, shell commands
- Typical uses
- Bug fixes, refactors, writing tests
- Hard-to-undo mistakes
- Deployments, database changes, external API calls
Browser agent
- Mainly observes
- Rendered pages, page text
- Mainly changes
- Forms and buttons in signed-in accounts
- Typical uses
- Booking prep, plan comparisons, repetitive data entry
- Hard-to-undo mistakes
- Payments, confirmed bookings, sending personal data
Research agent
- Mainly observes
- Search results, documents, connected apps
- Mainly changes
- Mostly nothing (read-only)
- Typical uses
- Market scans, competitor comparisons, policy summaries
- Hard-to-undo mistakes
- Decisions built on a wrong conclusion
Video agent
- Mainly observes
- Brief, reference images, generated scenes
- Mainly changes
- New video, voice and music
- Typical uses
- Ads, social clips, previsualization
- Hard-to-undo mistakes
- Spent credits, publishing rights-infringing content
Risk grows with the scope of access and how reversible the actions are, not with how capable the model sounds. Anthropic notes that autonomy brings higher costs and the potential for compounding errors, recommends extensive testing in sandboxed environments with guardrails, and reminds builders that the simplest solution, sometimes not an agent at all, is often enough.
How to choose the right agent for a task
- 1
Define the output first
Decide whether you need changed code, a completed web task, a cited report or a finished video. That choice usually settles the category: a briefing document points to a research agent, repetitive web entry to a browser agent.
- 2
Grant the minimum access
Do not give write access for a read-only job. Use per-site approvals for browsers, allowed-command lists for coding tools and allowed domains for research.
- 3
Set human checkpoints
Require a pause before payments, confirmed bookings, deployments and public posts. The official products above are designed to ask before such steps; keep that behavior on.
- 4
Verify the real outcome
Check test results, the actual booking page, the cited source and the rendered video instead of relying on the agent's final message. Note the cost and time so you can compare next time.
Agent products change quickly. Each time a new one launches, ask what it observes, what it can change and what it cannot undo, and the marketing becomes easier to read. On theddari you can follow which agent stories are circulating in AI-focused Telegram channels and blogs, then go back to the original announcements and documentation before forming a view.
 theddari.comTrendsBlog PostsSummarized Naver blog posts
In short: coding agents fit verifiable software work, browser agents fit web tasks without an API, research agents fit gathering scattered information and video agents fit starting a production from a brief. Whatever the type, start with narrow permissions, keep a human in front of irreversible actions and verify the real result.
Frequently asked questions
What is the difference between an AI agent and a chatbot?
Is it safe to give a browser agent my password?
Can I trust a research agent because it cites sources?
How is a video generation agent different from a text-to-video model?
Should I give a coding agent full permissions to save time?
Sources and references
- 1Anthropic: Building effective agents(opens in a new tab)www.anthropic.com
- 2Claude Code Docs: How Claude Code works(opens in a new tab)code.claude.com
- 3OpenAI API Docs: Computer use(opens in a new tab)developers.openai.com
- 4OpenAI Help Center: Using cloud browser in ChatGPT(opens in a new tab)help.openai.com
- 5OpenAI Academy: Deep research(opens in a new tab)academy.openai.com
- 6Runway: Introducing Runway Agent(opens in a new tab)runway.com
Related articles
 AI
Haru-4B Explained: Full-Duplex Voice Model and Local Setup
Haru-4B, the top trending model on Hugging Face, is not a small text chatbot. It is an open speech-to-speech base model that listens and speaks at the same time. Here is how it works, what hardware it needs, and what to check before running it.
 AI
Gemini 4 Neon: Pricing, Access and Hydrogen vs Argon
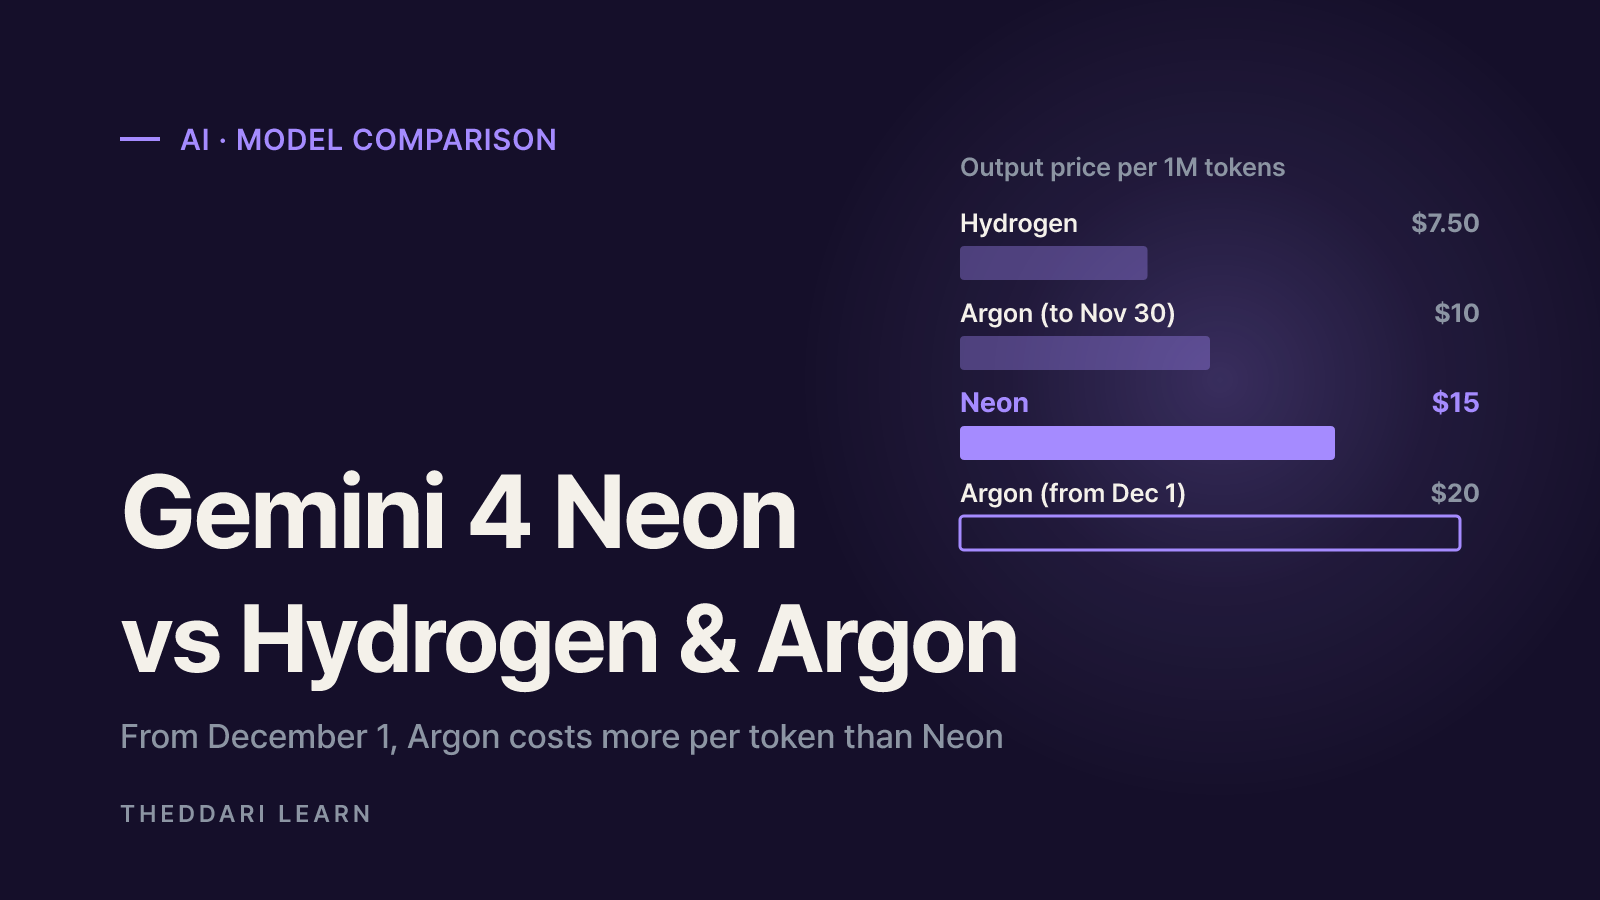
Gemini 4 Neon is Google's new mid-tier Gemini 4 model, priced at $3 input and $15 output per million tokens with no free tier. Here is what Google announced, how it stacks up against Hydrogen and Argon, and what to check before you switch.
 AI
MiniMax-H3-Image: Specs, ComfyUI Setup and License Limits
MiniMax-H3-Image topped Hugging Face trending. We checked the model card, the official ComfyUI tutorial and the license text: what the model does, how the Comfy-Org repack differs, how to set it up, and why US, UK, EU and Korean users are outside the default license.