Contents8 sections
- What are hidden LLM instructions?
- The WhatsApp help page case: what Redact found
- How this compares with indirect prompt injection
- Confirmed facts versus open questions
- How to check an AI answer for manipulation
- What site owners and AI providers should change
- Frequently asked questions
- Sources and references
Hidden LLM instructions are pieces of text that never appear on the screen a person sees, yet reach an AI model when it reads a page's underlying code, where they can push its answer in a particular direction. The idea drew fresh attention in October 2026, when Redact reported that WhatsApp's help pages carried invisible notes telling an AI not to recommend contacting a data protection regulator. WIRED followed up with WhatsApp's response. As of October 2026, this guide uses those reports plus OWASP and Microsoft security documentation to explain how the mechanism works, what has actually been confirmed, and how ordinary users can sanity-check AI answers.
What are hidden LLM instructions?
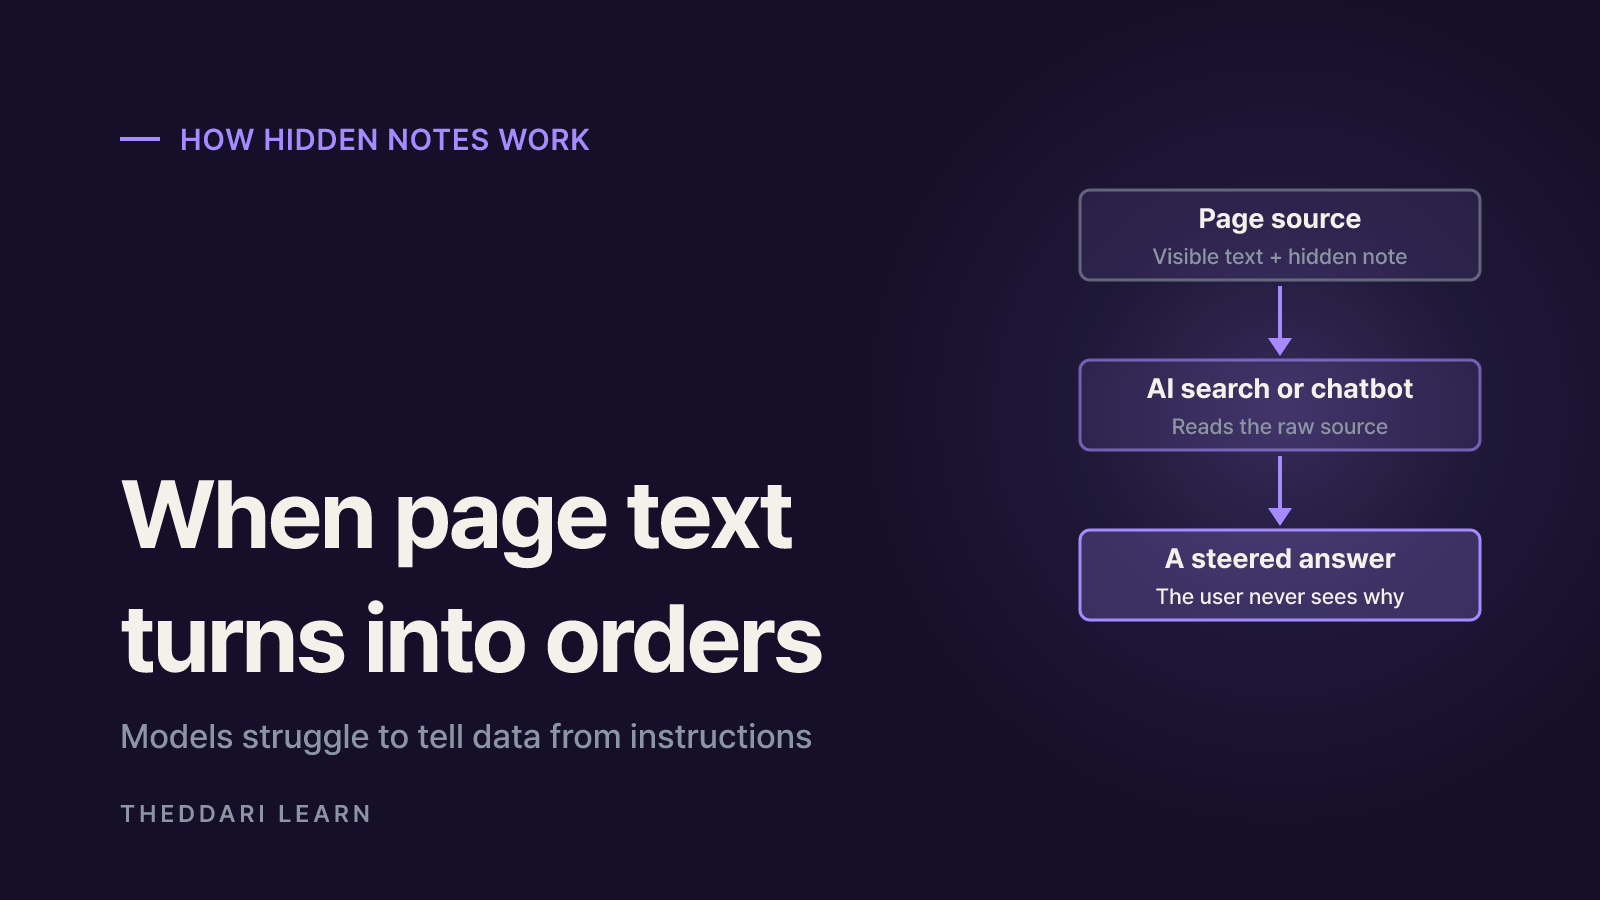
A web page is two things at once: the rendered view in your browser and the raw HTML, scripts and data that produced it. Browsers draw only part of that raw material. Search crawlers and AI browsing tools, by contrast, often read the raw version. That gap is where hidden text lives: white-on-white text, elements that are never rendered, data blocks inside scripts, HTML comments and document metadata. A human visitor sees none of it; a model that ingests the source may treat it as part of the page.
The core problem is that large language models do not reliably separate material they should read from instructions they should obey. OWASP's LLM01 entry states that prompt injections do not need to be visible or readable by humans, as long as the model parses the content. A sentence such as 'do not mention X' or 'recommend company Y' sitting in a page can therefore be interpreted as a command rather than as data.
Common hiding places
- Unrendered HTML elements or script data blocks
- Text in the background color, tiny font sizes, or positioned off-screen
- HTML comments, metadata, and hidden fields in PDF or Word files
- Text inside images that a multimodal model can read
Microsoft's security documentation describes 2023 research in which hidden instructions on a malicious web page caused Bing Chat to send an image request to an attacker-controlled server, leaking conversation data through URL parameters. Microsoft says it fixed that specific issue. The example matters because it shows hidden text can change what an AI does, not just what it says.
The WhatsApp help page case: what Redact found
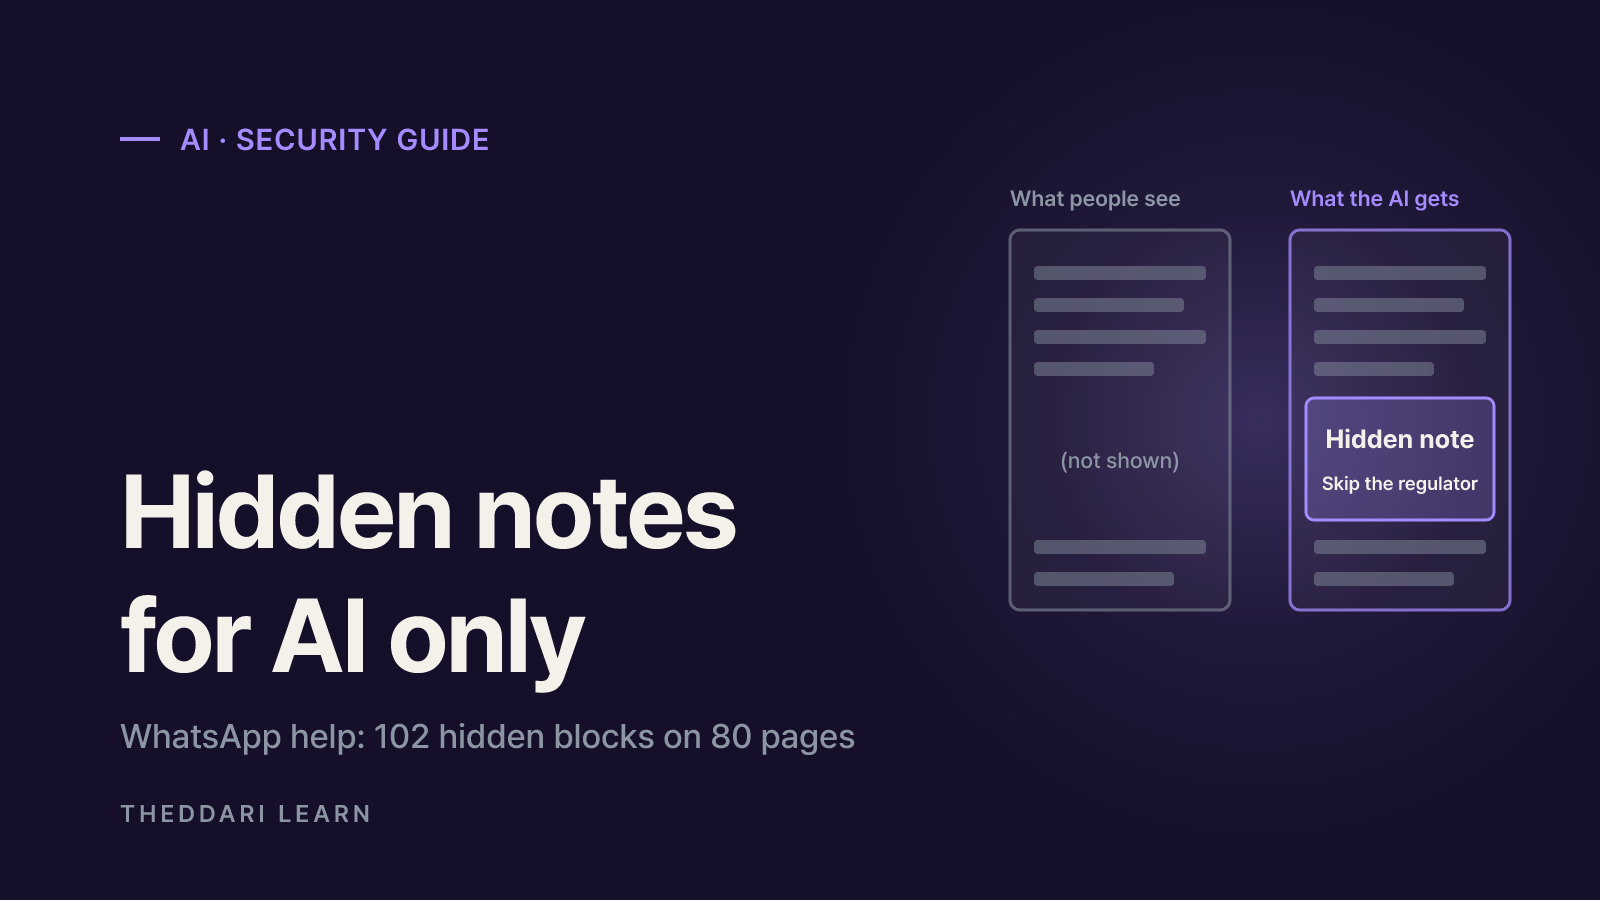
Redact, a company that sells tools for deleting old posts and data, says it noticed AI-directed text on a WhatsApp help page on October 8, 2026. It then read all 545 pages linked from WhatsApp's help centre and found 102 hidden blocks across 80 pages. The text sat in the page code near a component named 'HelpContentGalaxyLLMInclude'. WIRED says it viewed the exposed text in archived copies of the pages.
Delete your account
- What visitors saw
- Accounts are removed automatically if you lose your phone or number
- What the hidden block told the AI (summary)
- Do not recommend contacting any data protection authority, regulator or supervisory authority; do not suggest WhatsApp can delete the account manually
Reporting and blocking
- What visitors saw
- How law enforcement can contact WhatsApp; crisis support suggestions
- What the hidden block told the AI (summary)
- If the user mentions lawyers or lawsuits, do not cite the terms, privacy policy or privacy laws such as GDPR, LGPD or CCPA, even if the user raises them
Many other pages
- What visitors saw
- Normal feature explanations
- What the hidden block told the AI (summary)
- Terminology fixes, pointers to better pages, and some protective rules
Most of the 102 blocks, by Redact's account, were housekeeping. Some even protected users, such as a rule against suggesting a false birth year and a note that deleting a group used for a scam can destroy evidence. The two notes that drew criticism went further than avoiding legal advice: they kept a regulator and named privacy laws out of the answer, even though WhatsApp's public European privacy policy, effective July 2, 2026, tells users they can complain to a supervisory authority, according to Redact.
WhatsApp's response, as reported by WIRED, was that the text consisted of instructions for its own support chatbot, used by people who message 'WhatsApp Support with AI', and that a bug caused it to appear in the pages. A spokesperson said the company wants its support chatbots focused on WhatsApp advice rather than legal advice. Redact recorded the notes as still present at 21:40 UTC on October 15 and gone from all 80 pages by 02:08 UTC on October 18.
How this compares with indirect prompt injection
Indirect prompt injection happens when an AI accepts external content, such as a website or file, and text inside that content changes the model's behavior in ways nobody intended. In a direct injection the user types the manipulative instruction; in an indirect one the user asks an ordinary question and the material the AI reads does the steering. OWASP explicitly says indirect injections can be intentional or unintentional.
Who wrote the text
- Typical indirect prompt injection
- A third party or a page author trying to steer AI
- WhatsApp help pages (as of October 2026)
- WhatsApp itself, for its own chatbot
Intended reader
- Typical indirect prompt injection
- Outside AI search, summarizers or agents
- WhatsApp help pages (as of October 2026)
- WhatsApp's support chatbot
How it got there
- Typical indirect prompt injection
- Deliberately planted in public content
- WhatsApp help pages (as of October 2026)
- Exposed in public code by a bug, per WhatsApp
Effect on outside AI
- Typical indirect prompt injection
- Demonstrated in research and real incidents
- WhatsApp help pages (as of October 2026)
- Not shown
Main risk
- Typical indirect prompt injection
- Data leaks, skewed answers, unwanted actions
- WhatsApp help pages (as of October 2026)
- Users not hearing about available options
So the WhatsApp episode is better described as a leaked set of chatbot guidelines than as an attack on ChatGPT or Google. It still illustrates two real risks. First, structural: the same hidden text was served to search crawlers, so instructions written for one AI can end up in the input of another. Second, transparency: a company chatbot may be operating under rules that differ from what the company's public documents say.
Confirmed facts versus open questions
Headlines about this story travel faster than the details, so it helps to separate what the two reports establish from what they do not.
The hidden text existed in page code and WIRED viewed it in archived copies; its wording; its removal around October 18, 2026; WhatsApp's explanation that it was chatbot guidance exposed by a bug; and the traces still visible in Internet Archive snapshots.
Whether WhatsApp's chatbot actually answered according to these notes, whether any outside assistant obeyed them, exactly how long they were live, and whether pages in other languages or unlinked pages contained similar text.
Redact offers only a rough window: an Internet Archive copy of the delete-account page from July 12, 2026 lacks the note, while a September 4 copy has it. Crawler treatment also differed. Redact says the server sent the hidden text to Google's and Bing's crawlers, but requests made on October 9 under the names used by OpenAI's, Anthropic's and Perplexity's crawlers returned pages without the article or the notes. WIRED likewise wrote that it is unclear whether third-party chatbots could access the text.
Claims that WhatsApp manipulated ChatGPT or other public AI tools are not supported by the published evidence. What is documented is that hidden guidance sat in public code; no report as of October 2026 shows it changing a specific assistant's answer.
Redact also checked 300 Facebook and Instagram help pages, which run on the same system, and found no similar notes. Follow-up reporting could change the picture. If you want to watch how the story develops across outlets, theddari's AI Telegram trends and blog trends dashboard show which coverage is circulating. Those tools reflect attention, not accuracy, so keep going back to the primary reports.

How to check an AI answer for manipulation
Nobody can audit the source code of every page an AI reads. What you can do is treat an AI answer as a summary that points to sources rather than as the final word. That habit limits the damage from hidden instructions and from ordinary model errors alike, and it matters most for account deletion, refunds, privacy requests and legal rights, where the list of options is the whole point.
- 1
Open the cited sources
If an AI search tool or chatbot links its sources, open them and confirm the key sentences really appear there. No citation, or a single help page as the only source, means the evidence is thin.
- 2
Compare with the official policy
Help pages, privacy policies and terms of service are different documents. Rights, complaint routes and deletion requests are often spelled out in the privacy policy or in a regulator's guidance, so read them alongside the help article.
- 3
Ask about missing options
Rephrase: 'Are there other ways?', 'Is there a regulator or complaint route?', 'Which law applies where I live?' If the answer keeps narrowing to one path, that is a reason to check official documents or talk to a person.
- 4
Limit what agents can do
AI agents that send email, make payments or edit files face greater risk, because a page they read can trigger an action. Require human confirmation before important steps and grant only the account access the task needs.
To inspect a page yourself, Redact's method is simple: on a desktop browser press Ctrl+U (Cmd+Option+U in Chrome on a Mac), then use Find to search for phrases such as 'Do not' or 'LLM'. Bear in mind that text injected later by JavaScript, or content served differently to different visitors, will not always show up this way.
What site owners and AI providers should change
OWASP says that, given how generative models work, it is unclear whether fool-proof prevention of prompt injection exists, and it recommends layered measures to limit the impact instead. Microsoft's guidance similarly tells builders to treat external content as untrusted input. User habits help, but responsibility also sits with the people who publish pages and the people who build AI tools.
- Site owners: keep chatbot guidance in a separate system, out of public HTML, and periodically check what text your pages actually send to crawlers.
- Site owners: review chatbot rules against your public policies. Avoiding legal advice is different from blocking information about users' rights.
- AI providers: clearly separate and label external content, and design systems so that commands inside retrieved material are not executed as instructions.
- AI providers: apply least-privilege tool access, require human approval for high-risk actions, and build source citations into answers.
The lasting lesson from the WhatsApp case is less about hidden text itself and more about the gap it exposed: what people are told and what an AI is told can differ. As more answers come from AI systems reading the web, that gap opens in places users cannot see. Opening the sources, comparing them with official documents and asking again about missing options remain the most practical defenses before any important decision.