Contents8 sections
- How a diffusion language model generates text
- Diffusion LLM vs autoregressive LLM at a glance
- What Inception Labs says about Mercury 3
- Speed and quality trade-offs of diffusion LLMs
- How text diffusion relates to image diffusion
- Checklist before trying a diffusion LLM like Mercury 3
- Frequently asked questions
- Sources and references
A diffusion language model (diffusion LLM) generates text by starting with a fully masked response and refining many positions in parallel over a set number of steps, rather than writing one token after another from left to right. Because it needs fewer sequential passes for a long answer, it can respond much faster. The most visible commercial example as of October 2026 is Mercury 3, which Inception Labs announced on October 19, 2026. This guide explains how diffusion LLMs differ from standard autoregressive models, what Mercury 3's published numbers do and do not show, and where the speed and quality trade-offs appear.
How a diffusion language model generates text
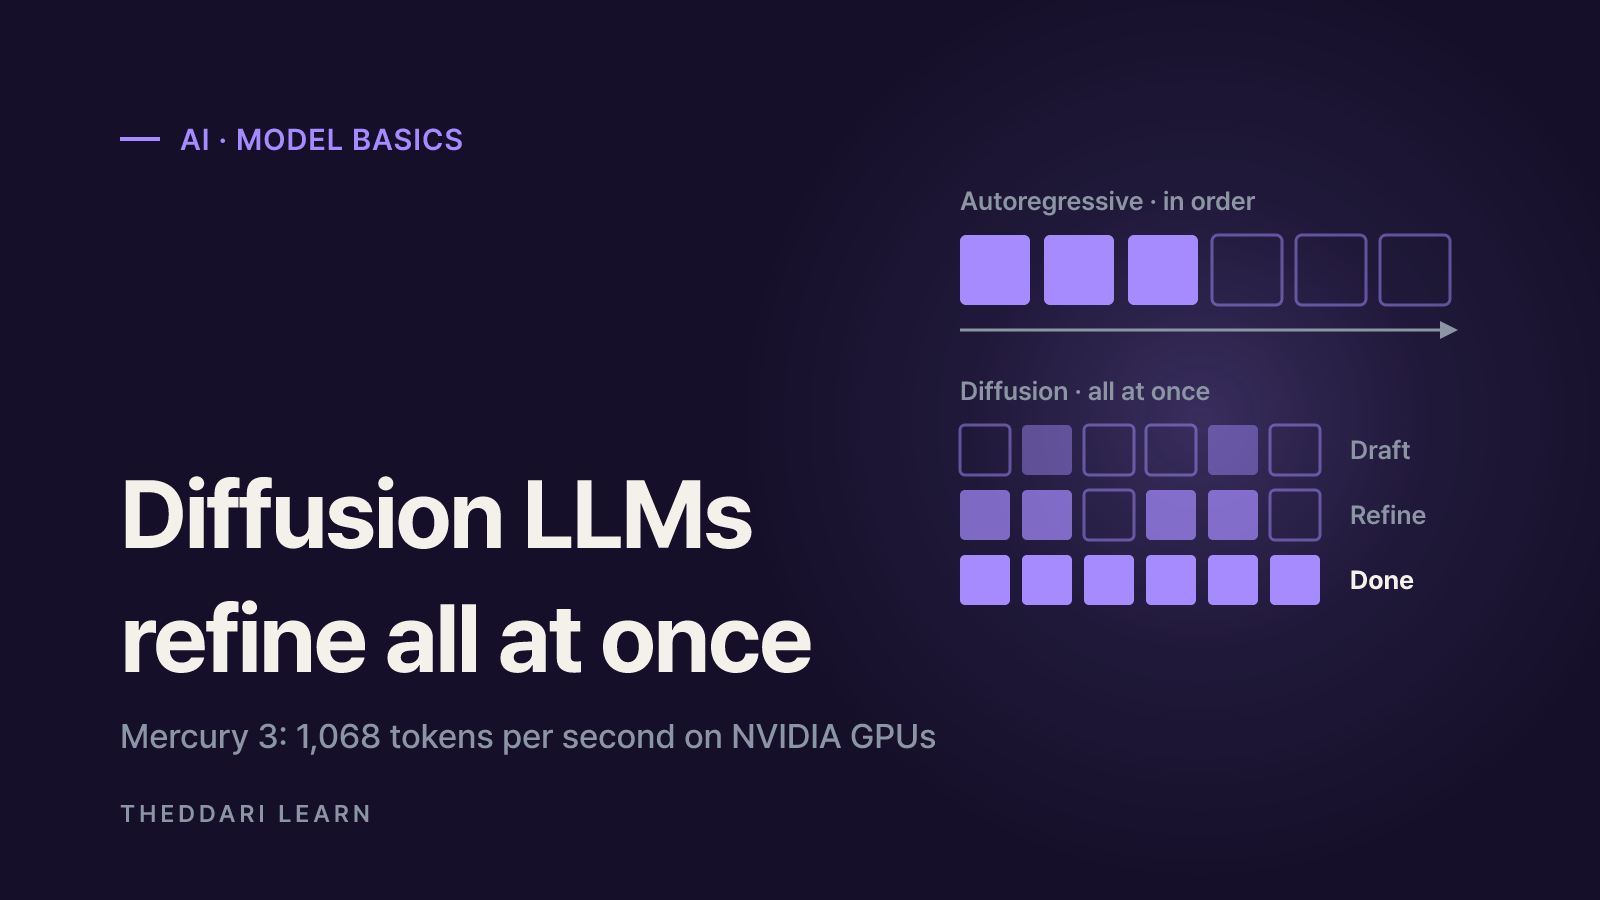
Almost every chatbot you have used is autoregressive. The model reads everything so far, predicts the single next token, appends it, and repeats. A 500-token answer needs roughly 500 sequential forward passes, and token 300 cannot be computed until token 299 exists. That strict ordering produces fluent text, but latency grows with output length and GPUs often sit underused between steps.
Masked diffusion models take a different route. In the LLaDA paper, training randomly masks a share of the tokens in each sentence and teaches a Transformer to predict the hidden ones. At inference time the model begins with a response of a chosen length where every position is masked. In each step it predicts all masked positions at once, keeps the predictions it is most confident about, and re-masks the low-confidence ones. After the planned number of steps the draft is complete. Think of a student working through a fill-in-the-blank test in several passes, locking in the easy answers first and revisiting the uncertain ones.
Bidirectional context
Because each step can see tokens on both sides of a gap, diffusion models use bidirectional context during generation. The LLaDA authors report that this helped their 8B model outperform GPT-4o on a reversal poem completion task, a known weak spot for left-to-right models. They also report that LLaDA 8B performed comparably to their own autoregressive baselines and was competitive with LLaMA3 8B. Treat that as evidence the approach can work at scale, not as proof that diffusion models reason better in general.
Diffusion LLM vs autoregressive LLM at a glance
Both approaches can use the same Transformer backbone. The difference lies in the training objective and the order in which the answer is produced. The table summarizes general properties described in the papers cited here; individual products mix in techniques such as block-wise generation or speculative decoding, so treat it as a starting point.
Generation order
- Autoregressive LLM
- Left to right, one token per pass
- Diffusion LLM
- Whole response refined in parallel over several steps
Sequential passes
- Autoregressive LLM
- Roughly one per output token
- Diffusion LLM
- A configurable number of sampling steps
Context used while generating
- Autoregressive LLM
- Only earlier tokens
- Diffusion LLM
- Tokens on both sides of each gap
Main speed/quality dial
- Autoregressive LLM
- Model size, decoding tricks
- Diffusion LLM
- Number of sampling steps
Reported weak spots
- Autoregressive LLM
- Latency grows with answer length
- Diffusion LLM
- Long-context scaling, batched throughput
Ecosystem
- Autoregressive LLM
- Mature serving engines, tooling and evals
- Diffusion LLM
- Fewer production models and serving options
The key row is sequential passes. LLaDA's authors describe the step count as a hyperparameter that trades efficiency against sample quality: fewer steps are faster but can lower output quality. Any tokens-per-second figure for a diffusion model therefore depends on the step setting and the hardware it was measured on.
What Inception Labs says about Mercury 3
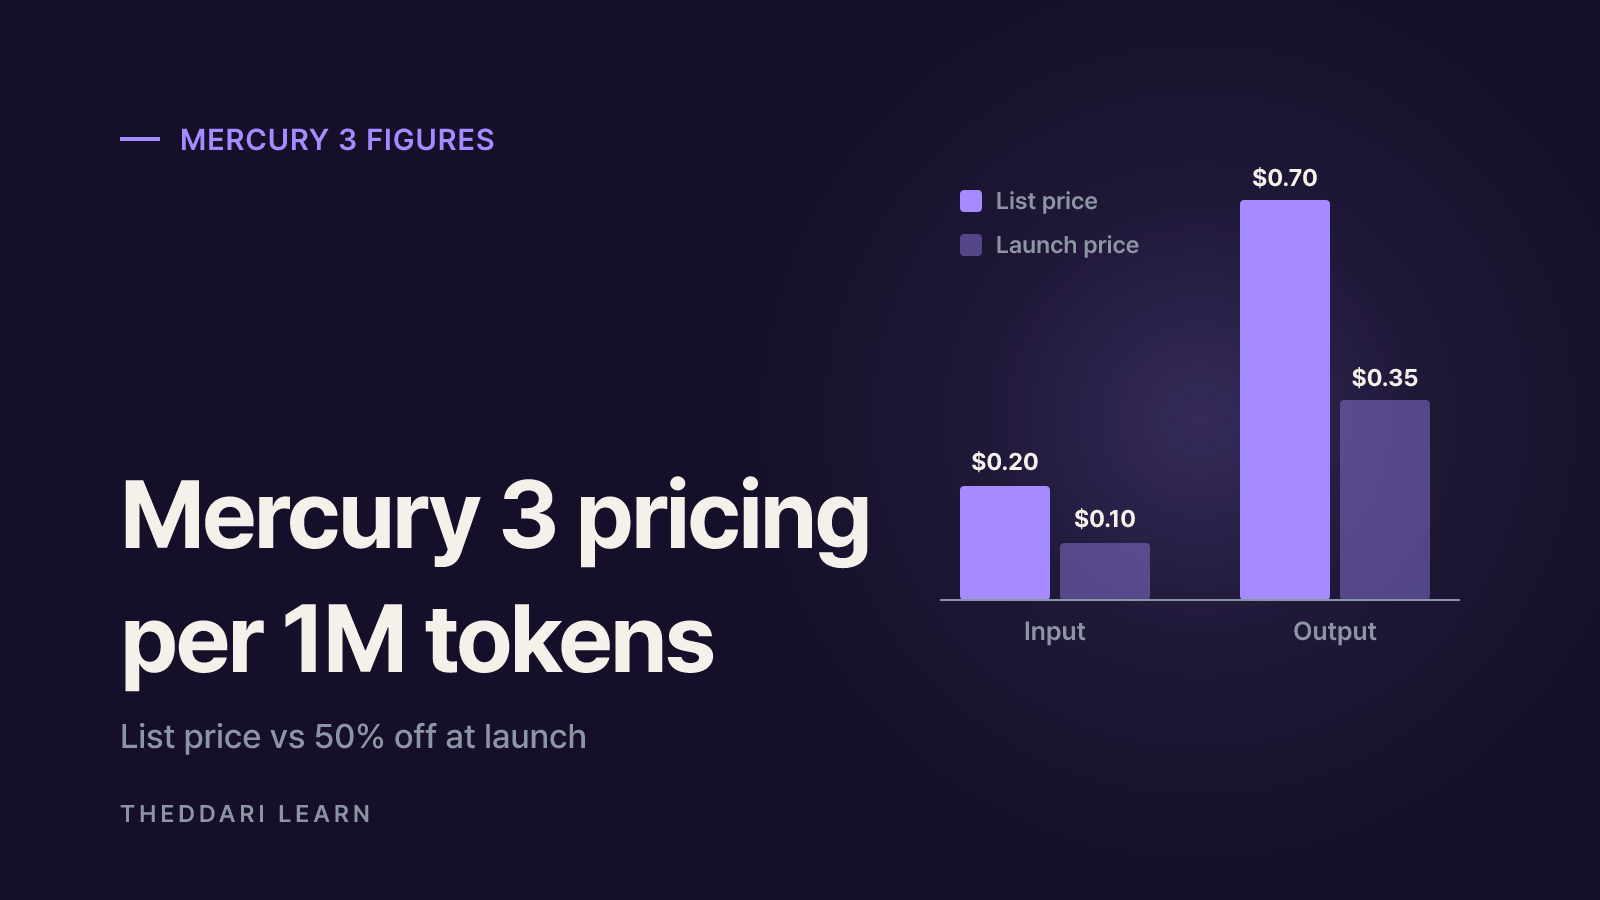
The Mercury 3 announcement calls it the most capable diffusion-based LLM released to date. These are the headline figures as published, checked against the original post on October 20, 2026. All of them are vendor-reported.
- Speed: 1,068 tokens per second on NVIDIA GPUs, described as 4–8x faster than the comparison models
- Quality: on par with or better than GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks
- Scale: more than 40x the total parameters of Mercury 1, with a 3x gain on standard benchmarks from Mercury 1 (mini)
- Context window: 1M tokens, up from 260K for Mercury 2.5
- List price: $0.20 per million input tokens and $0.70 per million output tokens; 50% off at launch ($0.10 / $0.35), with cached input tokens 90% off
- Access: Inception API Platform, OpenRouter, Baseten and Vercel; OpenAI API compatible
Start with the comparison set. GPT-6 Luna and Claude Haiku 5.5 are speed-optimized tiers, so the claim is about being the strongest among fast models, not about beating every frontier model. The post does not lay out per-benchmark scores and test settings in enough detail to reproduce them, so independent measurements matter.
Partner results deserve the same care. One web-agent team reports Mercury 3 completed 50% of 50 live Mind2Web navigation tasks; a search company reports a median generation time of 0.9 seconds and median end-to-end response of 2.2 seconds. These are useful real-world signals, but they come from small samples inside each company's own harness. For context, the earlier Mercury technical report cited independent Artificial Analysis measurements of 1,109 tokens/sec for Mercury Coder Mini and 737 tokens/sec for Mercury Coder Small on H100 GPUs. That was a different generation, so it should not be compared directly with Mercury 3.
Speed and quality trade-offs of diffusion LLMs
Where diffusion models tend to shine
The clearest wins are latency-sensitive, interactive workloads: voice assistants, chat support, live tutoring and multi-step agents. Inception's own early-access examples fall into these categories. Agents call the model many times per task, so shaving time off every call compounds. A lower output price also lets you afford more retries or longer reasoning within the same budget.
Where the advantage can shrink
A performance study by Kim et al. found that diffusion models achieve higher arithmetic intensity by working on many token positions at once, but fail to scale effectively with longer contexts. Block-wise decoding helped restore scaling similar to autoregressive models. In batched inference, autoregressive models showed superior throughput because they benefit more from processing many sequences together. The authors concluded that reducing the number of sampling steps is the main path for open-source diffusion models to beat autoregressive latency.
In practice, a diffusion LLM is most likely to feel faster when one user is waiting on one answer. For overnight batch jobs or very long documents, the gap may narrow or reverse. Quality risks include the need to pick a generation length in advance, the step-count trade-off and a thinner ecosystem of tooling and evaluations. Note that this research focused on open models; how far Mercury 3's proprietary optimizations overcome these limits cannot be confirmed from public material.
How text diffusion relates to image diffusion
Image generators such as Stable Diffusion also start from a corrupted state and restore it over many steps; the word diffusion refers to that forward corruption and learned reverse process. The difference is the data. Pixels are continuous values, so image models add and remove noise. Text is a sequence of discrete tokens from a fixed vocabulary, so models like LLaDA use masking as the corruption step and train with a cross-entropy loss on the masked positions. The familiar steps-versus-quality trade-off carries over, but benchmarks and failure modes need to be judged on their own terms.
Checklist before trying a diffusion LLM like Mercury 3
- 1
Name your bottleneck
For interactive apps, measure time to first token and end-to-end latency. For batch pipelines, measure throughput and total cost. Research suggests diffusion models compare differently in these two settings.
- 2
Build an eval from your own prompts
Run the same prompt set and output format against your current model. Track accuracy, failure rate and latency together; your data matters more than headline benchmarks.
- 3
Test long inputs and tool use separately
Supporting a 1M-token window is not the same as being accurate across it. Test long documents, structured output and tool calls as separate scenarios and log failures.
- 4
Budget at list price
Separate launch discounts from list pricing and cached-token discounts. Promotions end, so confirm the project still works at $0.20 input and $0.70 output per million tokens.
New model launches generate a burst of commentary within days. theddari's AI Telegram trends page tracks which AI stories are circulating in channels, and the blog trends dashboard shows which topics bloggers are covering. Attention is not evidence of quality, so use these to spot follow-up reviews and independent tests, then check them against the original sources.

Diffusion language models challenge the assumption that text must be generated strictly one token at a time. Mercury 3 is Inception Labs' argument that the approach keeps working as models grow, with speed and price as its clearest selling points. Keep in mind that the quality comparison is against other fast models, that the figures are self-reported, and that published research flags long-context and batch-throughput limits. Read the numbers with those conditions attached and test on your own workload.