Contents7 sections
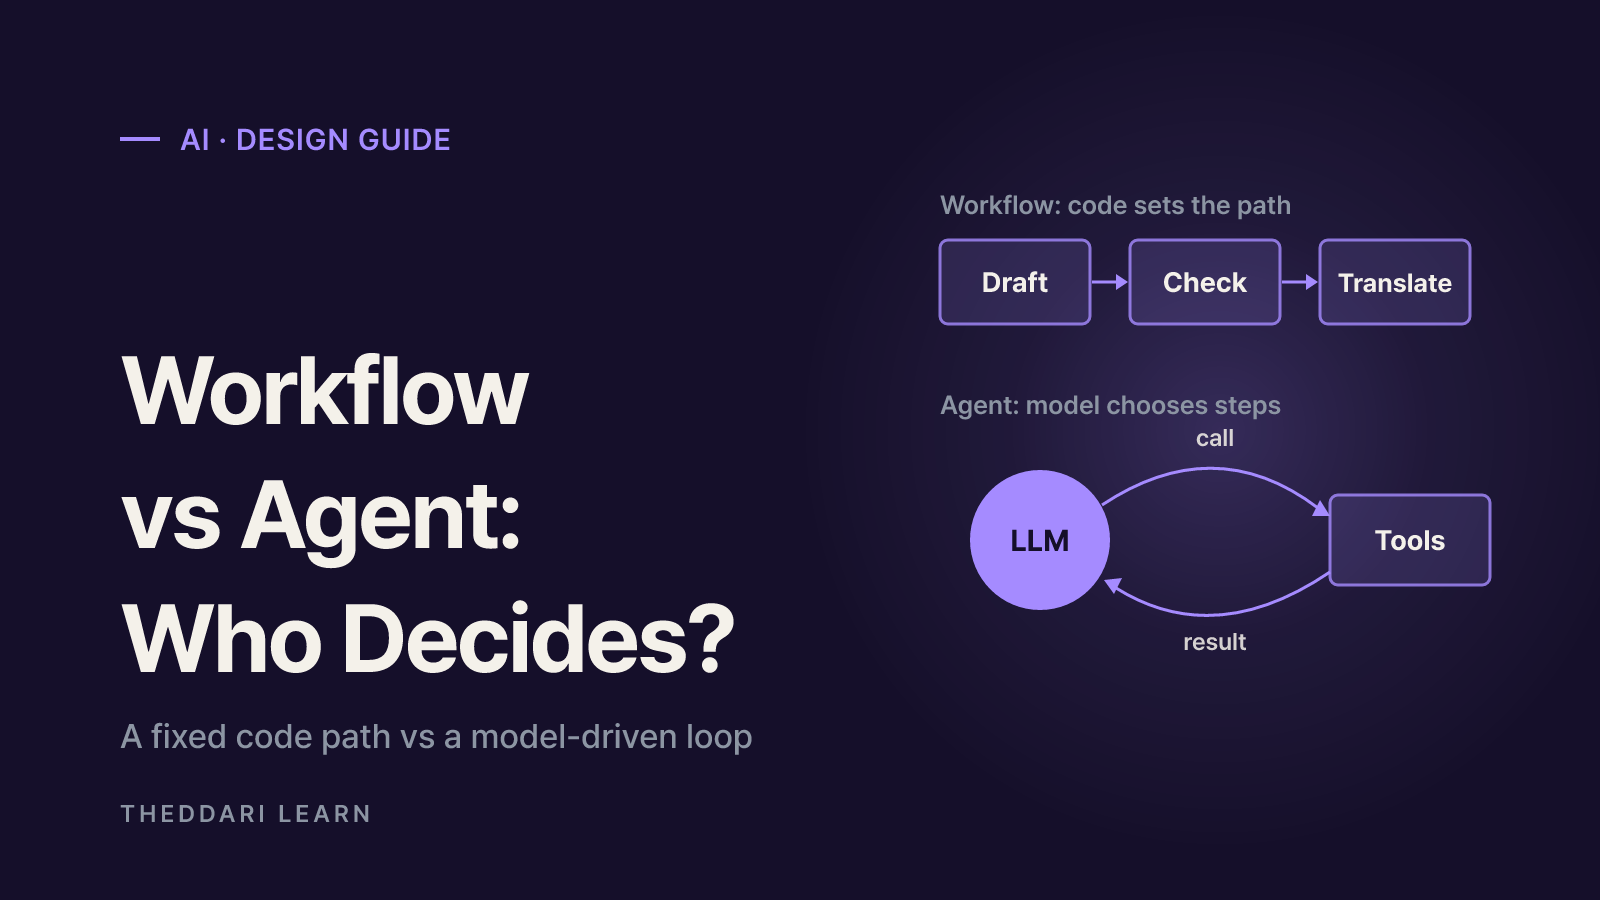
The AI workflow vs agent question comes down to one thing: who decides the next step. In a workflow, your code defines the path and the LLM does the language work inside each step. In an agent, the model looks at the situation and chooses which tool to call, how many times and when it is done. If you can write the steps down before the run starts, a fixed workflow is usually the cheaper, more predictable and more testable choice. Agents earn their extra cost on open-ended problems where the path cannot be planned. This guide reflects the official documentation from Anthropic, OpenAI and LangChain as of October 2026; it is about architecture choices, not a benchmark of specific products.
AI workflow vs agent: the core difference
Anthropic's 'Building effective agents' groups both under the umbrella of agentic systems but draws a clear architectural line. Workflows are systems where LLMs and tools are orchestrated through predefined code paths. Agents are systems where LLMs dynamically direct their own processes and tool usage. The LangChain documentation uses the same framing: workflows have predetermined code paths and run in a set order, while agents define their own process.
An agent is often simpler to implement than the hype suggests. Anthropic describes agents as LLMs using tools based on environmental feedback in a loop. The model calls a tool, reads the result, picks its next action and stops when it reaches the goal or hits a stopping condition such as a maximum number of iterations. OpenAI's practical guide breaks an agent into three parts, a model, tools and instructions, and centers the design on a run loop that continues until an exit condition is met. It also notes that apps which use an LLM without letting it control workflow execution, such as simple chatbots or sentiment classifiers, are not agents.
A quick test: can you draw the flowchart before the system runs? If yes, you are building a workflow. If the path only exists after the model makes decisions at runtime, you are building an agent.
Cost, reliability and debugging trade-offs
Anthropic frames agentic systems as trading latency and cost for better task performance. Workflows offer predictability and consistency for well-defined tasks; agents are the better option when flexibility and model-driven decisions are needed at scale. The same post adds that for many applications, optimizing a single LLM call with retrieval and in-context examples is enough.
Who picks the next step
- Fixed workflow
- Your code
- Agent
- The model, at runtime
Number of LLM calls
- Fixed workflow
- Known in advance
- Agent
- Varies per task
Cost and latency
- Fixed workflow
- Predictable
- Agent
- Variable, often higher
Testing
- Fixed workflow
- Test each step like normal code
- Agent
- Evaluate outcomes over many runs
Failure mode
- Fixed workflow
- Easy to find the failing step
- Agent
- Small errors can compound
Unexpected inputs
- Fixed workflow
- Only handles designed cases
- Agent
- Can adapt to new situations
The cost gap is measurable. In Anthropic's write-up of its multi-agent research system, published in June 2025, the company reports that in its data agents typically use about 4x more tokens than chat interactions, and multi-agent systems about 15x. The same post says a multi-agent setup outperformed a single agent by 90.2% on an internal research evaluation. Those figures come from Anthropic's own evaluation of breadth-first research tasks, so they should not be read as a universal ratio for every workload.
Debugging changes too. Anthropic notes that agents make dynamic decisions and are non-deterministic between runs even with identical prompts, which made failures hard to diagnose until the team added full production tracing. With a fixed workflow, you can usually inspect the input and output of the step that went wrong.
Five common LLM workflow patterns
A fixed workflow is not limited to a straight line. Anthropic describes five recurring patterns, and LangChain ships examples under the same names.
Prompt chaining
- How it works
- Each LLM call processes the previous output, with optional code checks (gates)
- Good fit
- Tasks that split cleanly into fixed subtasks
Routing
- How it works
- Classify the input, then send it to a specialized prompt, tool or model
- Good fit
- Distinct categories that can be classified accurately
Parallelization
- How it works
- Run independent subtasks at once, or run one task several times and vote
- Good fit
- Speed, or higher confidence from multiple attempts
Orchestrator-workers
- How it works
- A central LLM splits the task at runtime and delegates to workers
- Good fit
- Subtasks that cannot be predicted in advance
Evaluator-optimizer
- How it works
- One call generates, another critiques, in a loop
- Good fit
- Clear evaluation criteria and measurable gains from iteration
Orchestrator-workers and evaluator-optimizer let the model influence the path, so they blur into agent territory. It helps to think of autonomy as a spectrum rather than two boxes. A support system might route tickets with a fixed classifier and hand only the refund branch, which needs judgment, to an agent.
When to use a fixed workflow instead of an agent
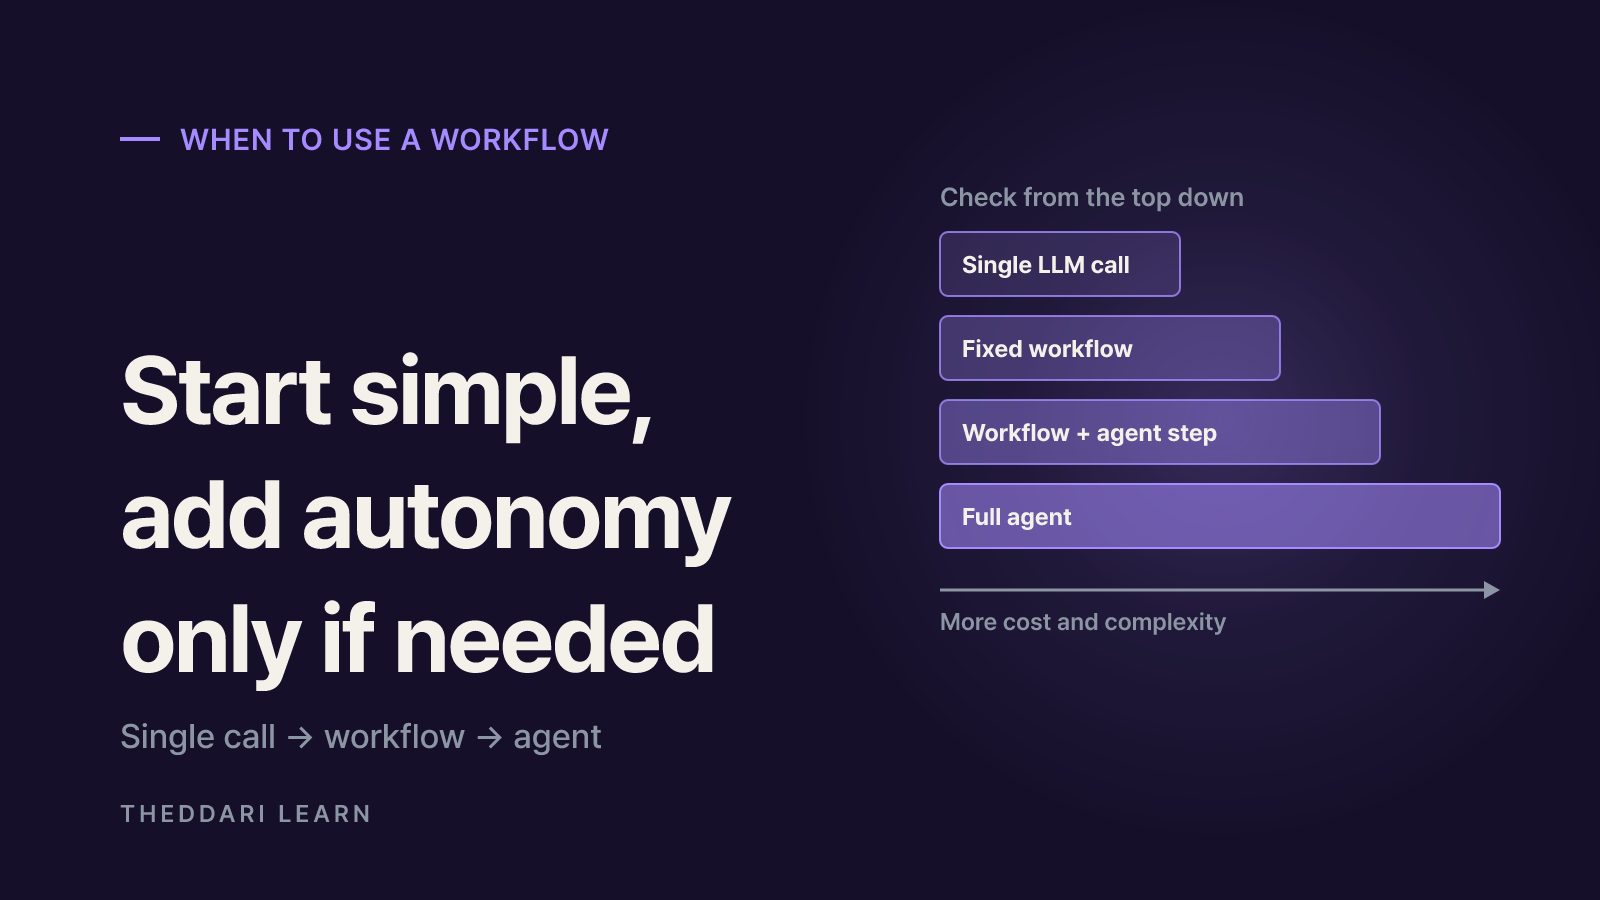
Anthropic recommends agents for open-ended problems where it is difficult or impossible to predict the required number of steps and you cannot hardcode a fixed path. OpenAI's guide suggests prioritizing processes that have resisted conventional automation: complex decision-making such as refund approvals, difficult-to-maintain rules such as vendor security reviews, and heavy reliance on unstructured data such as home insurance claims. If your use case does not clearly meet those criteria, the guide says a deterministic solution may suffice. Work through these questions in order.
- 1
Try a single LLM call first
If one well-prompted call with retrieval and examples meets your quality bar, stop there. Both vendors recommend the simplest solution that works.
- 2
Write the steps down? Build a workflow
Summarize then translate, or classify then call a specialized prompt: use chaining, routing or parallelization, and add programmatic checks between steps.
- 3
Only one step is unpredictable? Make that step agentic
Keep the overall pipeline fixed and give the model control only where the path genuinely depends on what it discovers, such as an open research step.
- 4
Fully open-ended? Check the value against the cost
Confirm the task is valuable enough to absorb higher token use and latency, and that success can be measured through tests or clear criteria, before committing to an agent.
Anthropic's own examples of where agents add value match this checklist. Coding agents can verify their work with automated tests and iterate on the results. Customer support combines conversation with actions such as looking up orders or issuing refunds, and resolution can be measured. Generating the same report format every week, or moving data according to fixed rules, is a better job for a fixed flow.
Agent tooling and design advice change quickly. You can follow which agent frameworks and case studies developers are discussing in the theddari AI Telegram trends and blog trends, then check any claim against the original documentation.
 theddari.comTrendsBlog PostsSummarized Naver blog posts
Guardrails if you do choose an agent
Anthropic warns that autonomy brings higher costs and the potential for compounding errors, and recommends extensive testing in sandboxed environments with appropriate guardrails. In practice, design these controls alongside the agent itself.
- Exit conditions: cap iterations or require a final output type so the loop cannot run indefinitely.
- Human handoff: OpenAI recommends escalating when the agent exceeds retry limits or before high-risk actions such as cancelling orders, large refunds or payments.
- Tool risk ratings: rate each tool by read-only versus write access, reversibility, required permissions and financial impact, and add checks before high-risk calls.
- Tool descriptions: while building its SWE-bench agent, Anthropic spent more time optimizing tools than the overall prompt, and requiring absolute file paths removed a class of mistakes.
- Tracing and outcome evals: since paths differ between runs, log full traces and judge whether the final state is correct rather than whether a prescribed sequence was followed.
The practical takeaway: if you can draw the flowchart, build the flowchart first and measure it. When one step keeps sprouting new branches, promote that step to an agent and compare token use, latency and success rate against the old version on the same test set. Adding complexity only when it demonstrably improves outcomes is the common conclusion of both vendor guides.