Contents8 sections
Short answer: AI detector accuracy is not good enough for a score to prove who wrote something. As of October 2026, published research shows detectors make two kinds of mistakes. They flag genuine human writing as AI-generated (false positives), and they miss AI text that has been lightly rewritten (false negatives). This guide is for students, teachers, editors, hiring managers and developers who either run AI text detection or have been flagged by it. It covers how detectors work, what independent tests found, why AI humanizer tools exist, and how far efforts to detect AI-written code have come.
The clearest warning came from OpenAI itself. It launched an AI text classifier on January 31, 2023, and, as the note on its original announcement says, pulled it on July 20, 2023 "due to its low rate of accuracy." At launch, the classifier caught only 26% of AI-written text and wrongly labeled human text as AI-written 9% of the time.
How AI text detection works
Most detectors use one of two approaches. Some measure how predictable a passage is to a language model. Others are classifiers trained on labeled examples of human and machine text. Either way, the output is a statistical guess that a passage resembles AI output. No detector finds a record showing that a model actually produced the words.
Perplexity: predictable writing looks machine-made
Perplexity measures how surprised a model is by the next word. Language models tend to pick high-probability words, so their output often scores low. The catch is that people write predictable text too: second-language writing with a smaller vocabulary, templated business reports, or content with only one right answer. OpenAI's own example was a list of the first 1,000 prime numbers, which reads the same whoever types it.
Classifiers break outside their training data
Trained classifiers do well on text like what they learned from and can be confidently wrong on anything else. OpenAI warned its tool was very unreliable below 1,000 characters, performed significantly worse in languages other than English, and was unreliable on code. Each new model generation also changes the statistical fingerprint detectors look for, so a score's meaning drifts over time.
A "90% AI" score does not mean a 90% chance the text is AI-written. It is usually an internal confidence value. The real odds depend on the tool's false positive and miss rates and on how much of the checked text is actually AI-generated.
AI detector accuracy in independent tests
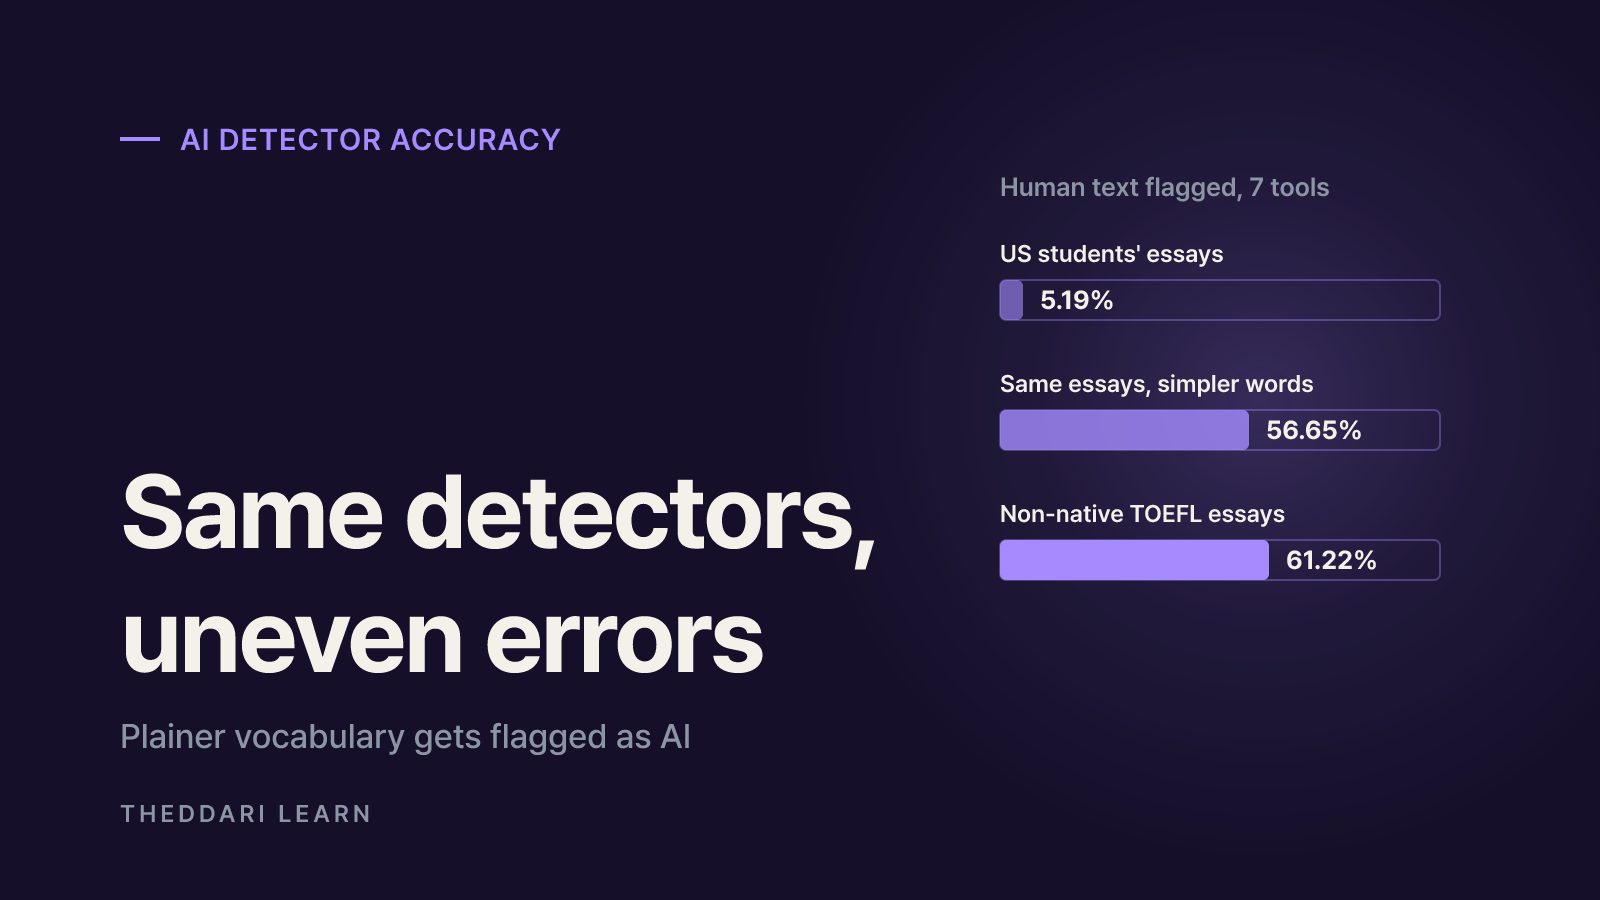
Two numbers matter. The false positive rate is how often human text gets flagged. The detection rate is how often AI text gets caught. Tuning a tool to protect honest writers usually means it misses more AI text, and the reverse.
OpenAI classifier (Jan 2023)
- What was tested
- English challenge set
- Key result
- Caught 26% of AI text, flagged 9% of human text; withdrawn July 20, 2023
Liang et al., Stanford (Jul 2023)
- What was tested
- 91 TOEFL essays, 7 detectors
- Key result
- Average false positive rate 61.22%; 89 essays (97.80%) flagged by at least one detector
Mozilla re-test (Mar 2024)
- What was tested
- Binoculars on a public dataset
- Key result
- About 0.7% false positives (roughly 1 in 140) vs. 0.01% claimed; 43% detection
Park et al. (Aug 2026, EMNLP 2026)
- What was tested
- 135,389 edited document pairs, 13 detectors
- Key result
- False positive rates on human text ranged from 0.0% to 100.0%
Non-native writers get flagged more
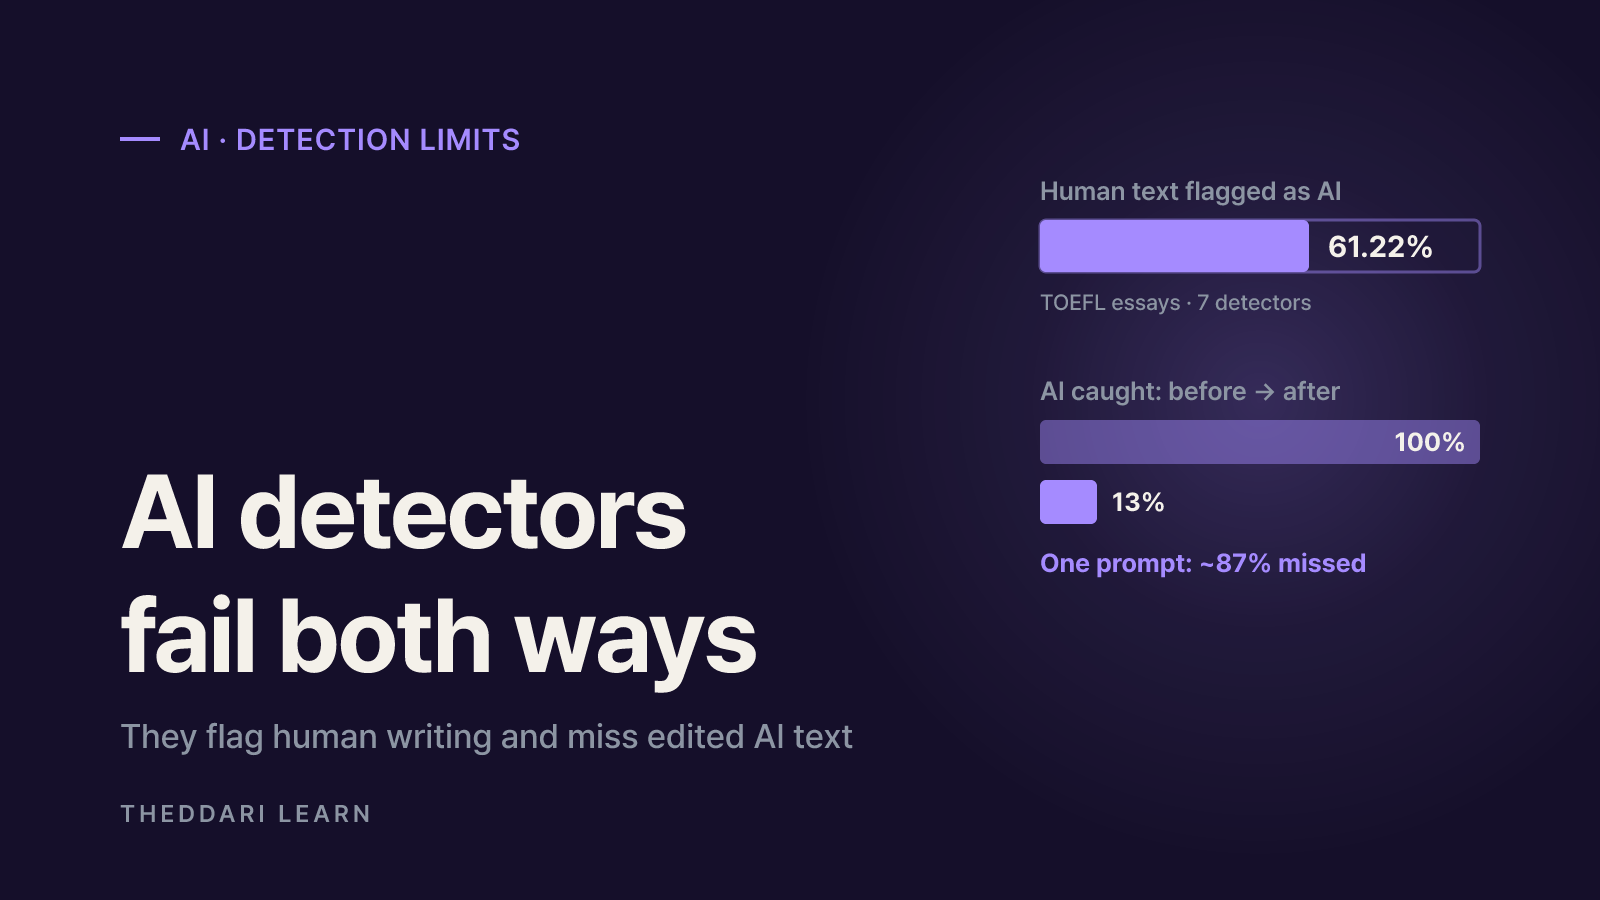
In the 2023 Stanford paper, seven popular detectors, including GPTZero and Originality.ai, were near-perfect on essays by US eighth graders but flagged human-written TOEFL essays as AI-generated at an average rate of 61.22%. All seven agreed, wrongly, on 18 essays (19.78%). When the researchers simplified the US essays' vocabulary to mimic non-native writing, the average false positive rate jumped from 5.19% to 56.65%. Word choice, not authorship, drove the verdict.
A much larger 2026 study by Park and colleagues ran 135,389 pairs of non-native manuscripts and their professionally edited versions through 13 detectors. False positive rates on human writing ranged from 0.0% to 100.0% across tools, and the same edit raised AI scores on some detectors while lowering them on others. The authors call professional editing style a confounding variable in detector output.
Small error rates add up at scale
Mozilla Foundation re-tested Binoculars, a detector whose authors reported a 0.01% false positive rate. On a public dataset, Mozilla measured roughly 0.7%, meaning about one false accusation in 140 texts rather than one in 10,000. A university checking tens of thousands of assignments a term could flag a large number of innocent students even at that rate.
Can an AI humanizer beat detectors?
An AI humanizer rewrites a machine-made draft so it reads as human: uneven sentence length, fewer stock transitions, more concrete words. Because detectors rely on statistical patterns, changing those patterns changes the verdict.
One prompt is often enough
No special tool was needed in the Stanford study. For 31 college admission essays written by ChatGPT-3.5, detection rates reached up to 100% at first. After one follow-up prompt asking to "elevate the provided text by employing literary language," they fell to at most 13%, so detectors missed about 87% at that point. Generated scientific abstracts dropped from up to 68% detected to 28%. Mozilla saw the same pattern: asking ChatGPT to add natural phrasing and small errors turned a flagged text into one rated human.
Dedicated humanizer models
In October 2026 a downloadable humanizer drew wide attention on Hugging Face. According to its model card, jialinyyzz/humanizer is a 12B model fine-tuned from Google's Gemma 4 12B, rewrites English and Chinese drafts, runs locally and is released under Apache 2.0. Its author reports that on October 2, 2026, Originality.ai at its strictest setting flagged 11 of 210 English rewrites as AI. The card says no AI detector was used in training.
The same card lists the costs. A strict LLM judge found no factual problem in 376 of 420 English rewrites, which means the rest changed some detail such as a number or name. The author calls the detector figure one measurement on one date, says nothing guarantees any detector outcome, and tells users to follow school, employer or publisher rules on AI help. These are self-reported numbers, not an independent benchmark.
Passing a detector is not the same as following the rules. Where AI use must be disclosed, hiding it with a humanizer can still surface later through version history, an oral check or an honor code review.
How to detect AI-written code, and why it is harder
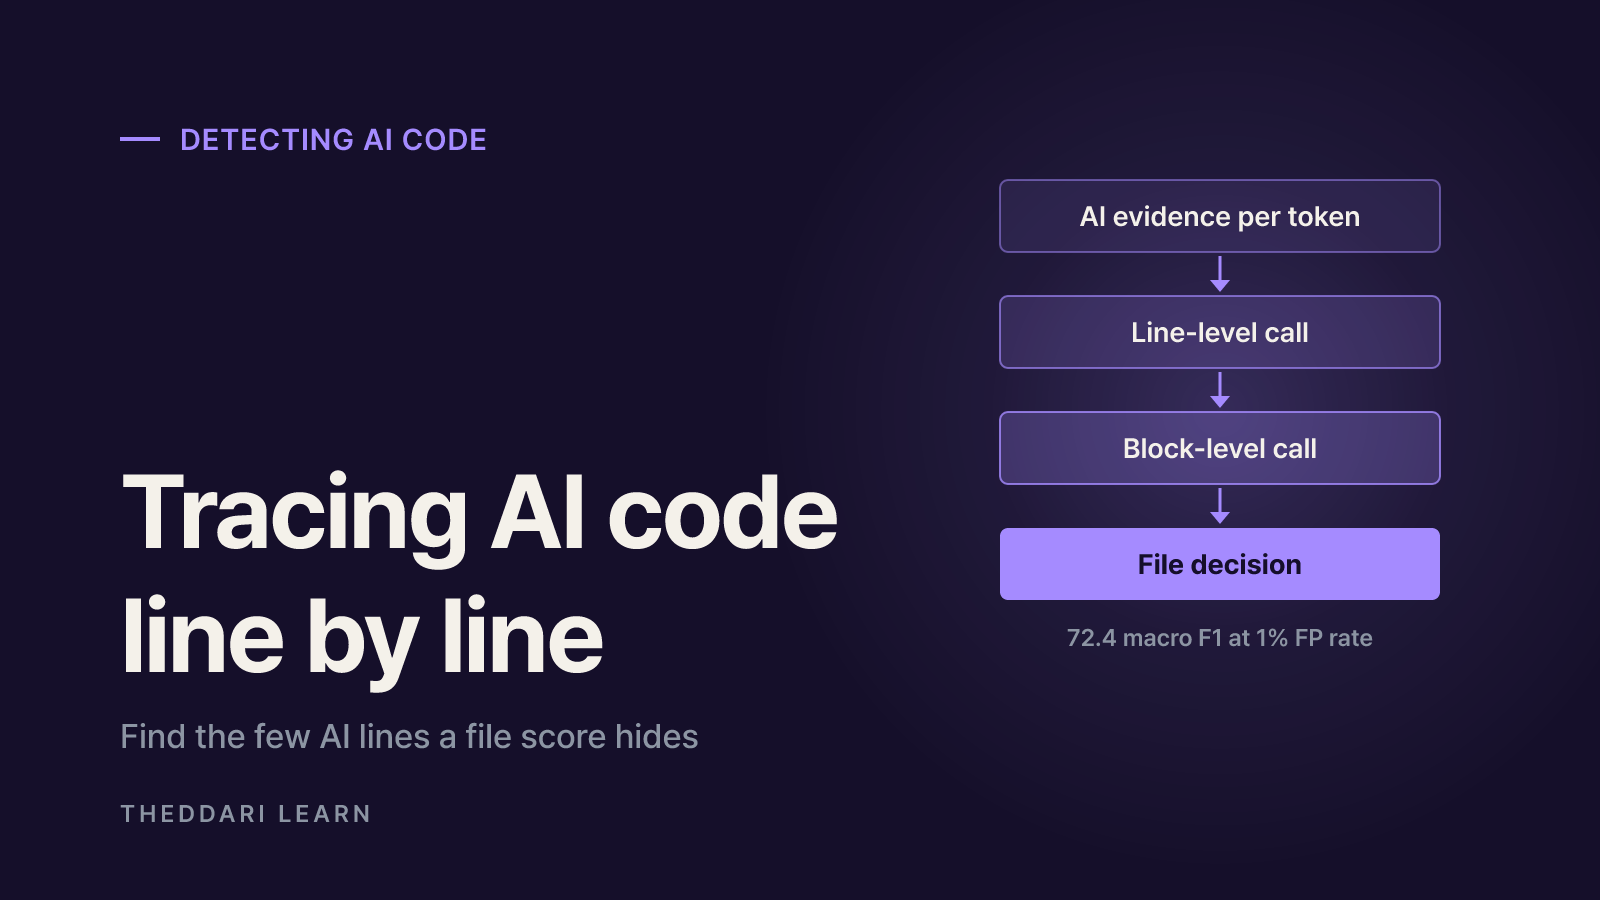
Code is harder to attribute than prose. Syntax and idioms already make human and model code look alike, and real files are often mixed: a developer writes most of it and accepts a few autocomplete suggestions. A single file-level score averages those few lines away.
The From Tokens to Files preprint, posted to arXiv on October 20, 2026, targets that gap. It adds two lightweight adapters to a frozen code model, one trained on machine-written files and one on human files, and uses their per-token likelihood ratio as local evidence. Small heads aggregate that evidence into line, block and file decisions, so the method can point at which lines look AI-involved.
- On an internal test set of 11,773 AI-involved files and 2,541 human files, it reports 72.4 macro F1 at a 1% false positive rate.
- On the external HybridCodeAuthorship benchmark, with no adaptation, it reports 62.5 line-level F1, above the 56 that benchmark's own paper lists as best.
- On 19,445 human-written files from repositories created before 2022, the false positive rate stayed between 0.55% and 0.81%.
Those results are promising but unreviewed, and a sub-1% false positive rate still flags many human files across a large codebase. For engineering teams, commit history, pull request review and a written AI-tool policy remain the more dependable way to track where code came from.
What to do with a detector result
Whether you are reviewing a flag or responding to one, the rule is the same: one score should never settle the question.
- 1
Record the tool and settings
Note the detector, version, strictness setting and date. The same text can get opposite verdicts from different tools or settings.
- 2
Check whether the text fits the tool
Short text under 1,000 characters, non-English text, code, templated documents and professionally edited writing all carry higher false positive risk.
- 3
Look for process evidence
Version history, dated drafts, research notes and the writer's ability to explain their choices say far more than a score.
- 4
Read the actual policy
Find out whether AI help is banned, allowed, or allowed with disclosure. Permitted use may make the score irrelevant.
- 5
Let a person decide, with a fair hearing
Use the result to start a conversation, and give the flagged person a chance to present evidence.
Detector and humanizer news moves quickly. You can follow the discussion through Theddari's AI Telegram trends and blog trend pages.
 theddari.comTrendsBlog PostsSummarized Naver blog posts
Bottom line on spotting AI text and code
- A detector score is a lead, not evidence. OpenAI's withdrawn classifier and several independent tests show why.
- False positives cluster in non-native, formulaic and professionally edited writing, and tools disagree sharply with each other.
- Rewrite prompts and humanizers cut detection rates easily, but they add factual errors and do not change disclosure rules.
- Line-level detection of AI-involved code is an active research area, still unverified as of October 2026.
- The most trustworthy approach combines process records, clear AI-use policies and human judgment.