Contents8 sections
- AI agent evals vs observability: what each one does
- Offline evals vs online evals
- Designing agent evals: tasks, graders and metrics
- Agent monitoring in production: traces, cost and failure rates
- How to roll out evals for AI agents in production
- Risks before you trust an eval score
- Frequently asked questions
- Sources and references
AI agent evals are automated tests that give an agent a defined task and apply grading logic to measure whether it succeeded. Observability is the ability to see what an agent actually did in production, usually through traces of every model call and tool call. Teams putting AI agents in production need both: evals tell you before a release whether a change made things better or broke something, and observability tells you after release how the agent behaves on real traffic, what it costs and where it fails. This guide, written as of October 2026, draws on Anthropic's engineering write-up on agent evals, the LangSmith and OpenAI evaluation docs, and the OpenTelemetry GenAI semantic conventions. It does not recommend a vendor; product names and features change, so check the current documentation of whichever platform you use.
AI agent evals vs observability: what each one does
Anthropic describes an eval as a test for an AI system: give it an input, apply grading logic to the output, and measure success. A single-turn chatbot eval needs only a prompt, a response and a check. Agents are harder because they work over many turns, call tools, modify state in an environment and adapt to intermediate results. A mistake early in a run can propagate and compound, which is why agent evaluation needs more structure than a list of prompts and expected answers.
Observability supplies the record of those runs. OpenAI's agent eval guide defines a trace as the end-to-end record of model calls, tool calls, guardrails and handoffs for one run, and suggests trace grading as the fastest way to find workflow-level issues such as picking the wrong tool or skipping a required handoff. In short, observability produces the raw material and evals provide the judgment about it.
Key terms
Task
- Meaning
- One test with defined inputs and success criteria
- Example
- Process a refund request
Trial
- Meaning
- One attempt at a task
- Example
- Run the same task five times
Grader
- Meaning
- Logic that scores one aspect of performance
- Example
- Unit tests, an LLM rubric
Transcript or trace
- Meaning
- Full record of outputs, tool calls and intermediate results
- Example
- The complete messages array
Outcome
- Meaning
- Final state of the environment after the trial
- Example
- Does the booking exist in the database?
The transcript-versus-outcome distinction matters. A booking agent may say the flight is booked, but success should be judged by whether a reservation actually exists. Grading only what the agent claims can count a run that did nothing as a pass.
Offline evals vs online evals
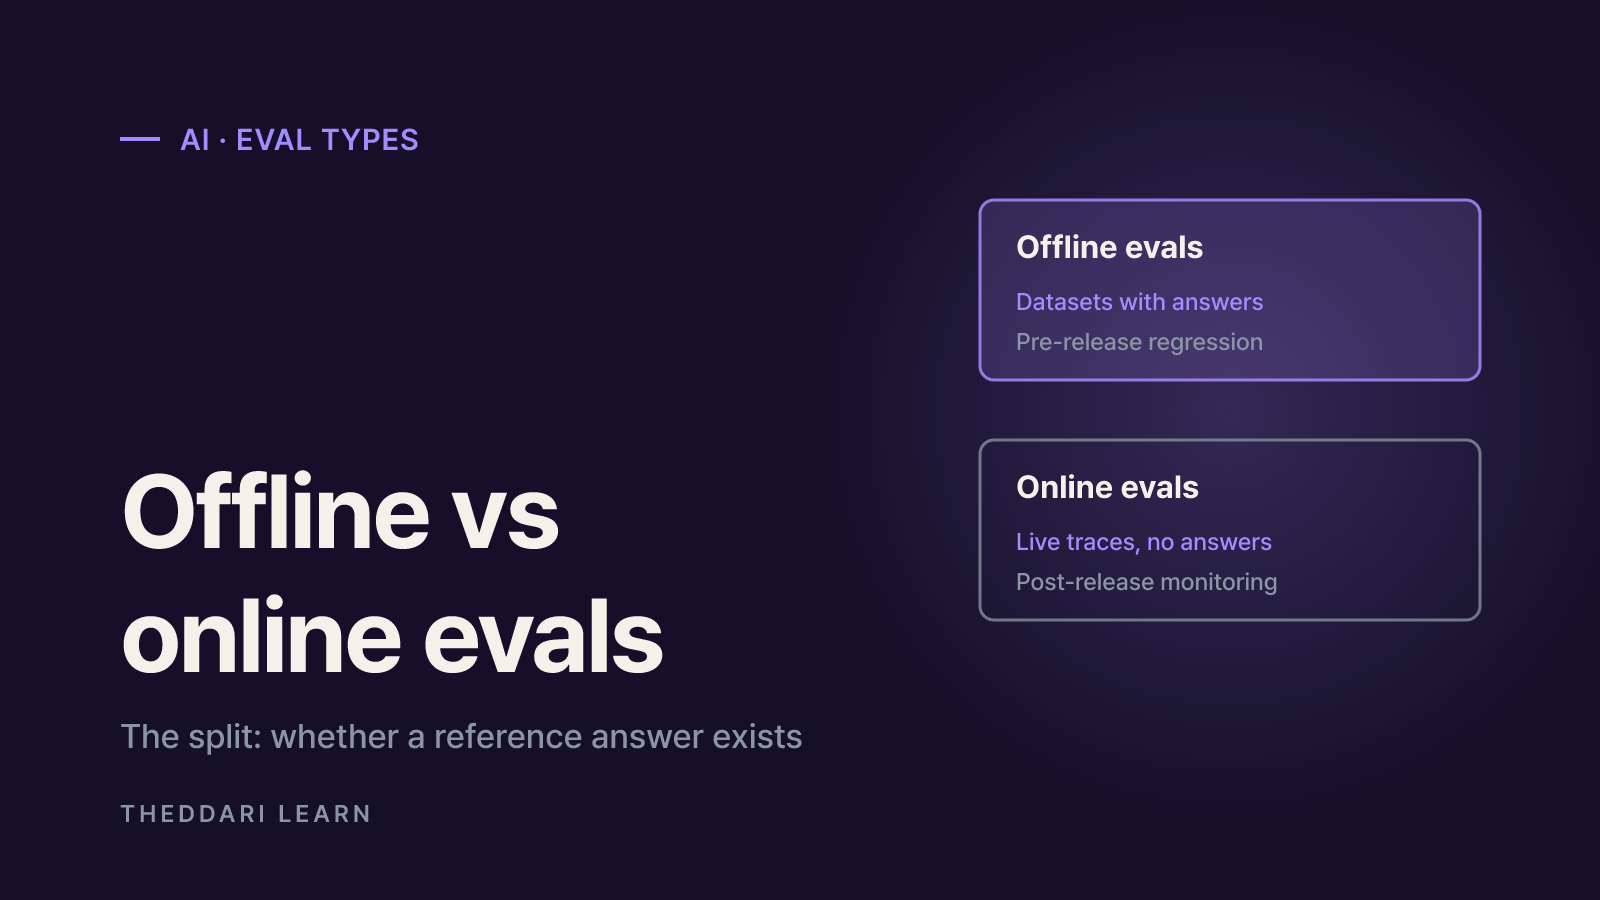
The LangSmith evaluation concepts page splits evaluation into offline evals for pre-deployment testing and online evals for production monitoring. The deciding difference is whether a reference answer exists. Offline evals run on curated examples that can include reference outputs, so they can check correctness directly. Online evals run on real production runs and threads, which have inputs and outputs but no reference, so they focus on safety, format, quality heuristics and anomalies.
Runs on
- Offline evals
- Curated dataset of examples
- Online evals
- Production traces (runs and threads)
Reference answers
- Offline evals
- Available
- Online evals
- Not available
When
- Offline evals
- Before deployment, during development
- Online evals
- After deployment, real time or near real time
Main uses
- Offline evals
- Benchmarking, regression and unit tests, backtesting
- Online evals
- Quality monitoring, anomaly detection, feedback collection
Usable graders
- Offline evals
- Reference-based and reference-free
- Online evals
- Reference-free only
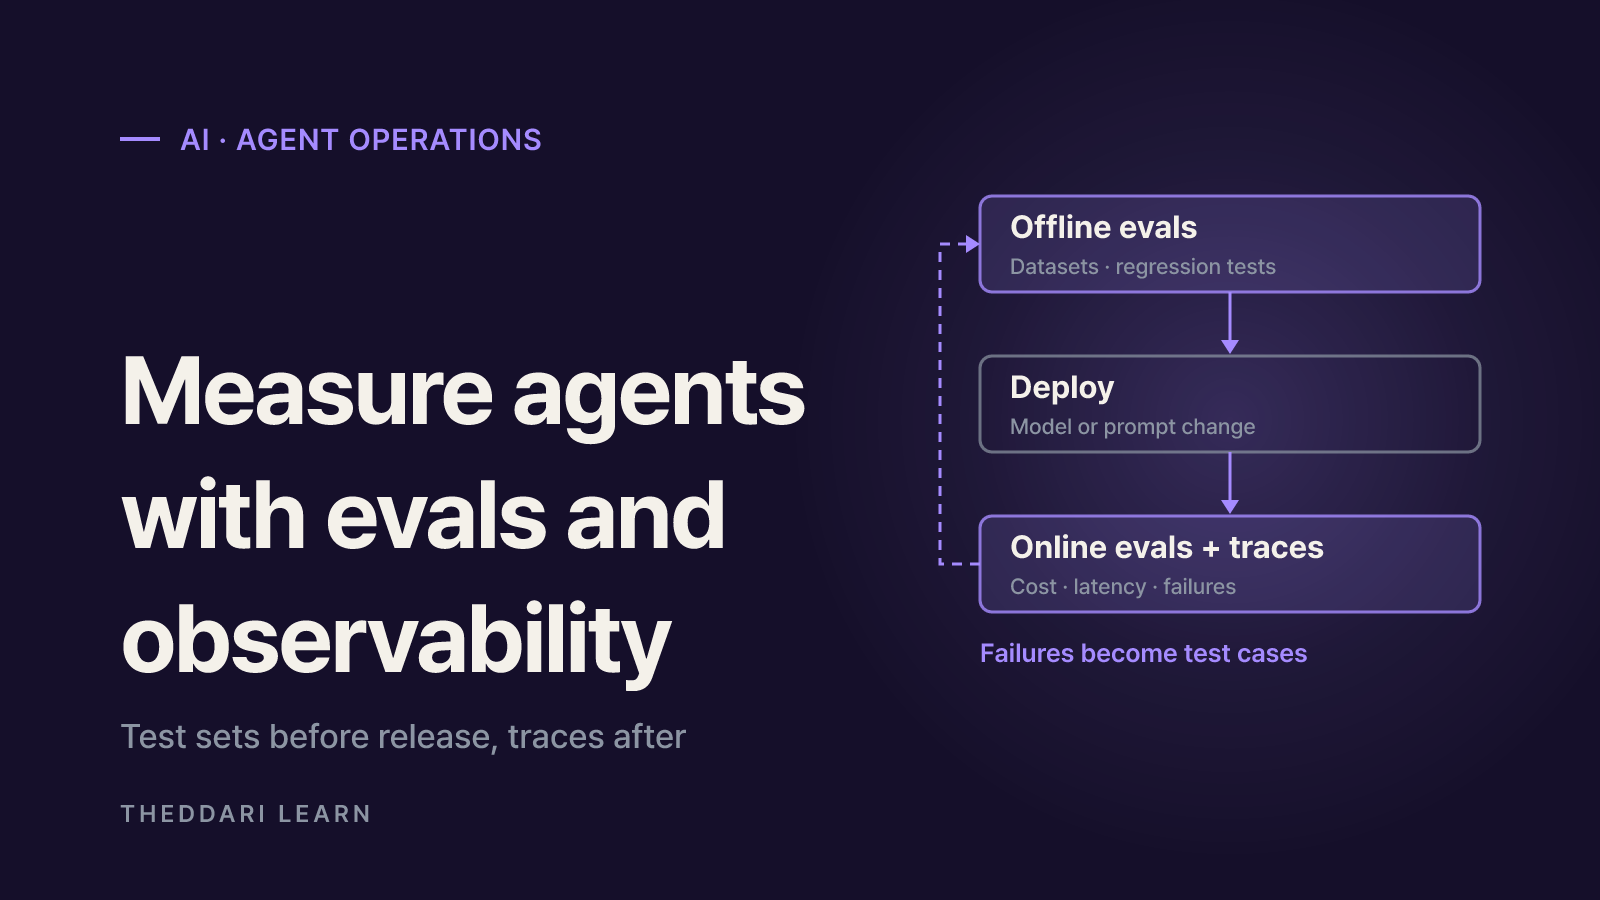
The two work best as a loop. Online evals surface odd runs in production; reviewed runs become new offline test cases; offline evals validate the fix; online evals confirm the improvement after release. Without that loop, a test set freezes the usage patterns of the day it was written and gradually stops representing real users.
Reference-free and reference-based graders
Reference-free graders include toxicity and PII detection, JSON or required-field checks, response length and latency heuristics, and LLM judges that rate clarity or tone without a gold answer. Because they work in both settings, they give you one consistent yardstick from testing to production. Semantic similarity to a reference, fact-checking against ground truth and exact-match classification need labeled answers, so they belong to offline evaluation.
Designing agent evals: tasks, graders and metrics
Anthropic groups agent graders into three families. Code-based graders such as string matching, unit tests, static analysis and tool-call parameter checks are fast, cheap and reproducible, but brittle when a valid answer is phrased differently. Model-based graders such as rubric scoring and pairwise comparison handle open-ended output, yet they are non-deterministic and need calibration against people. Human graders are the quality benchmark but slow and expensive, so they are mostly used to calibrate the model-based ones.
- Prefer deterministic code graders where they work; add LLM judges only where needed.
- Grade what the agent produced rather than forcing an exact tool-call sequence, because agents often find valid paths the eval designer did not anticipate.
- Give partial credit on multi-step tasks; an agent that identifies the problem and verifies the customer but fails the refund is better than one that fails immediately.
- Split rubrics into dimensions, judge each in isolation, and allow an Unknown answer when information is missing.
- Test both directions. If every case requires a web search, you may train an agent that searches for everything.
Capability evals and regression evals
Capability evals ask what the agent can do well and should start with a low pass rate, giving the team a hill to climb. Regression evals ask whether the agent still handles everything it used to and should stay near 100%; a drop signals breakage. Tasks that reach a high pass rate in the capability suite can graduate into the regression suite and run continuously.
Why pass@k and pass^k answer different questions
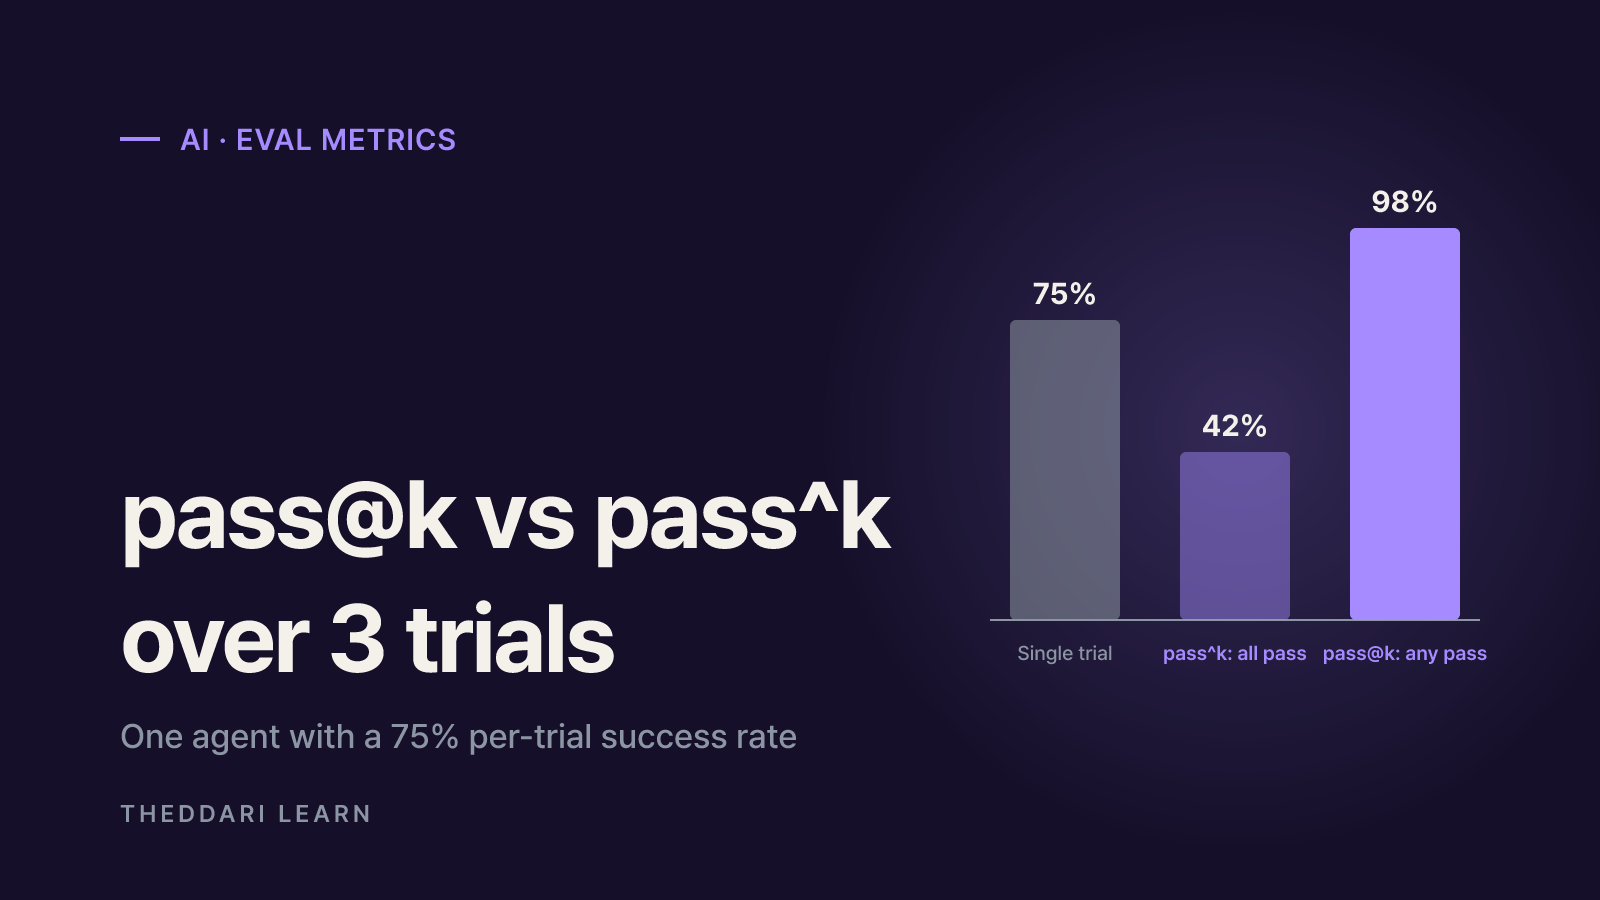
Agent output varies between runs, so a single pass or fail is weak evidence. pass@k is the probability that at least one of k trials succeeds; pass^k is the probability that all k succeed. Using Anthropic's example, an agent with a 75% per-trial success rate passes all three of 3 trials only about 42% of the time (0.75 cubed). The chance that at least one of those 3 trials succeeds is about 98% (one minus 0.25 cubed). A code-suggestion tool where one good candidate is enough fits pass@k; a customer-facing support agent that must behave reliably every time fits pass^k.
Agent monitoring in production: traces, cost and failure rates
Production monitoring shows real user behavior at scale and catches problems synthetic evals miss. Anthropic also lists its drawbacks: it is reactive, so issues reach users first; its signals are noisy; it needs instrumentation; and it lacks ground truth. Treat it as a complement to offline evals, not a replacement.
Cost
- Examples
- Tokens per task, cost per task
- Watch out for
- Compare like with like before and after model or prompt changes
Latency
- Examples
- Time to first token, total completion time
- Watch out for
- Do not average long and short tasks together
Reliability
- Examples
- Error rate, failed tool calls, retries and turn count
- Watch out for
- Separate timeouts from policy refusals
Quality
- Examples
- Online LLM-judge scores, policy-violation flags
- Watch out for
- Recalibrate judges against human review
User signals
- Examples
- Thumbs-down, rephrased questions, human handoff
- Watch out for
- Sparse and skewed toward severe issues
Collecting these metrics requires consistent traces. The OpenTelemetry GenAI semantic conventions define spans, metrics and events for generative AI client inference, agents, tool execution, evaluation and MCP operations; when checked in October 2026 they had moved out of the main semantic conventions repository into their own repository. Instrumenting to a shared format makes it easier to switch observability back ends later. The conventions are still evolving, so confirm attribute names against the version you adopt.
Online LLM judging costs money on every call. LangSmith, for example, lets you set a sampling rate, filters and spend limits for each project an evaluator is attached to. Rather than judging all traffic, prioritize runs with errors, long latency or negative feedback. Model launches and pricing changes are also natural triggers to rerun your suites; the theddari AI Telegram trends page is one way to keep an eye on those announcements.
How to roll out evals for AI agents in production
- 1
Write down what success means
List what the agent should and should not do. A good task is one where two domain experts would independently reach the same pass or fail verdict; if they would not, fix the task description first.
- 2
Build a small dataset from real failures
Start with the checks you already run by hand before each release, plus failures from your bug tracker and support queue. Create a reference solution for each task to prove it is solvable and that the graders are configured correctly.
- 3
Run isolated, repeated trials
Start every trial from a clean environment so leftover files or caches cannot leak between runs. Run each task several times and record both pass@k and pass^k.
- 4
Instrument traces and set baselines
Capture model calls, tool calls, errors, tokens and latency. Decide redaction and retention rules, then use offline results to set baselines for cost, latency, error rate and quality.
- 5
Close the loop
Send runs flagged by online evals or user feedback to human review, label them and add them to the offline set. Run the regression suite before every model or prompt change ships.
You do not need full automation on day one. OpenAI's guide suggests grading individual traces while you are still debugging behavior, then moving to repeatable datasets and eval runs once you know what good looks like. Following that order helps you notice early when a grader is measuring the wrong thing.
Risks before you trust an eval score
A score is only as good as its grader. Anthropic describes rigid grading that rejected 96.12 when it expected 96.124991, ambiguous task specs, and tasks that could not be reproduced, all of which pushed scores down for reasons unrelated to the agent. When many trials yield a 0% pass rate, suspect a broken task or grader before blaming the agent.
- Read transcripts. Only the record shows whether a failure was a real mistake or a valid answer the grader rejected.
- Watch for saturation. A suite near 100% still catches regressions but no longer shows improvement; add harder capability tasks.
- Make graders hard to game, so passing requires solving the task rather than exploiting leftovers from earlier runs or gaps in the rules.
- Refresh the dataset from production traces so it does not drift away from real usage and create false confidence.
- Public leaderboard scores do not replace an eval suite built around your own users and tools.
Quality management for AI agents in production is a loop: block regressions with offline evals before release, watch real behavior with traces and online evals after release, and turn production failures into new test cases. Whatever tooling you choose, define success clearly, start with deterministic graders and read transcripts before trusting the numbers. The theddari blog trends page collects developer posts where teams discuss their own eval and observability setups.
 theddari.comTrendsBlog PostsSummarized Naver blog posts