Contents8 sections
- Open source AI models compared at a glance
- License terms: what you can do commercially
- Hardware: how much memory each local LLM needs
- Picking by use case: coding, agents, documents and languages
- Self-host or API: a decision checklist
- Benchmark traps and deployment risks
- Frequently asked questions
- Sources and references
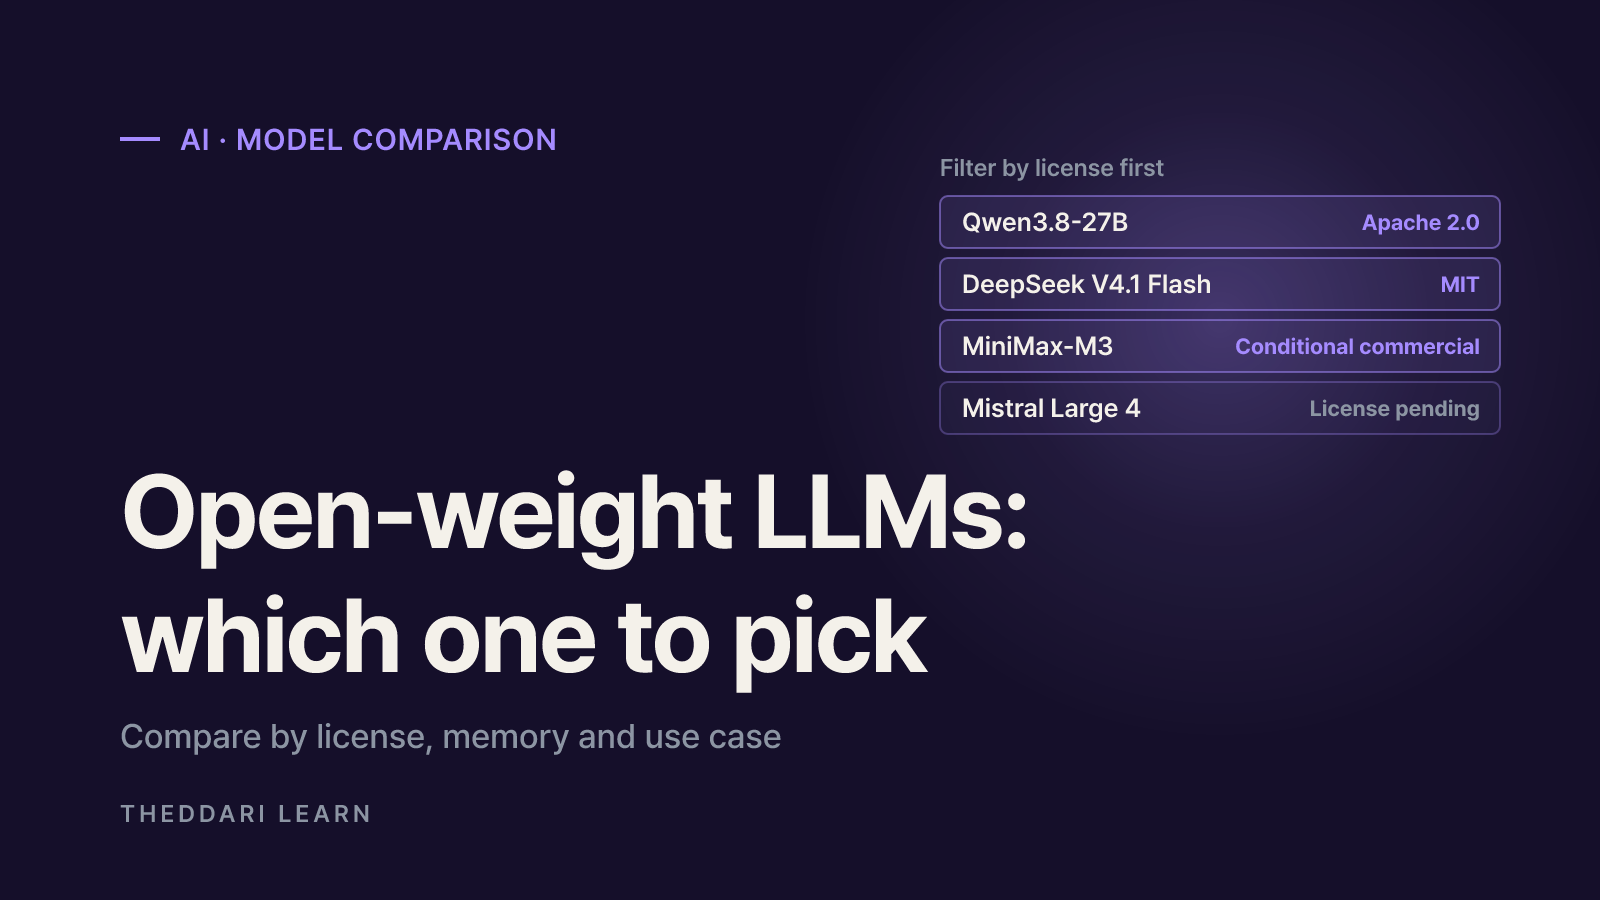
Choosing between open source AI models gets much easier once you answer two questions: where will it run (your own GPU or someone's API) and can you use it commercially. As of October 2026, Qwen3.8-27B is the only one of these four that fits on a single GPU or a high-memory workstation. DeepSeek V4.1 Flash 1017, MiniMax-M3 and Mistral Large 4 are server-class models that most people will reach through an API or a hosting provider. On licensing, DeepSeek (MIT) and Qwen (Apache 2.0) are the most permissive, MiniMax-M3 adds conditions for commercial use, and Mistral Large 4's terms will only be known when its weights ship.
This guide focuses on how to choose rather than on each model in isolation. Figures come from the official Hugging Face model cards and vendor announcements checked on October 24, 2026. Model cards change often, so re-check them before you commit.
Open source AI models compared at a glance
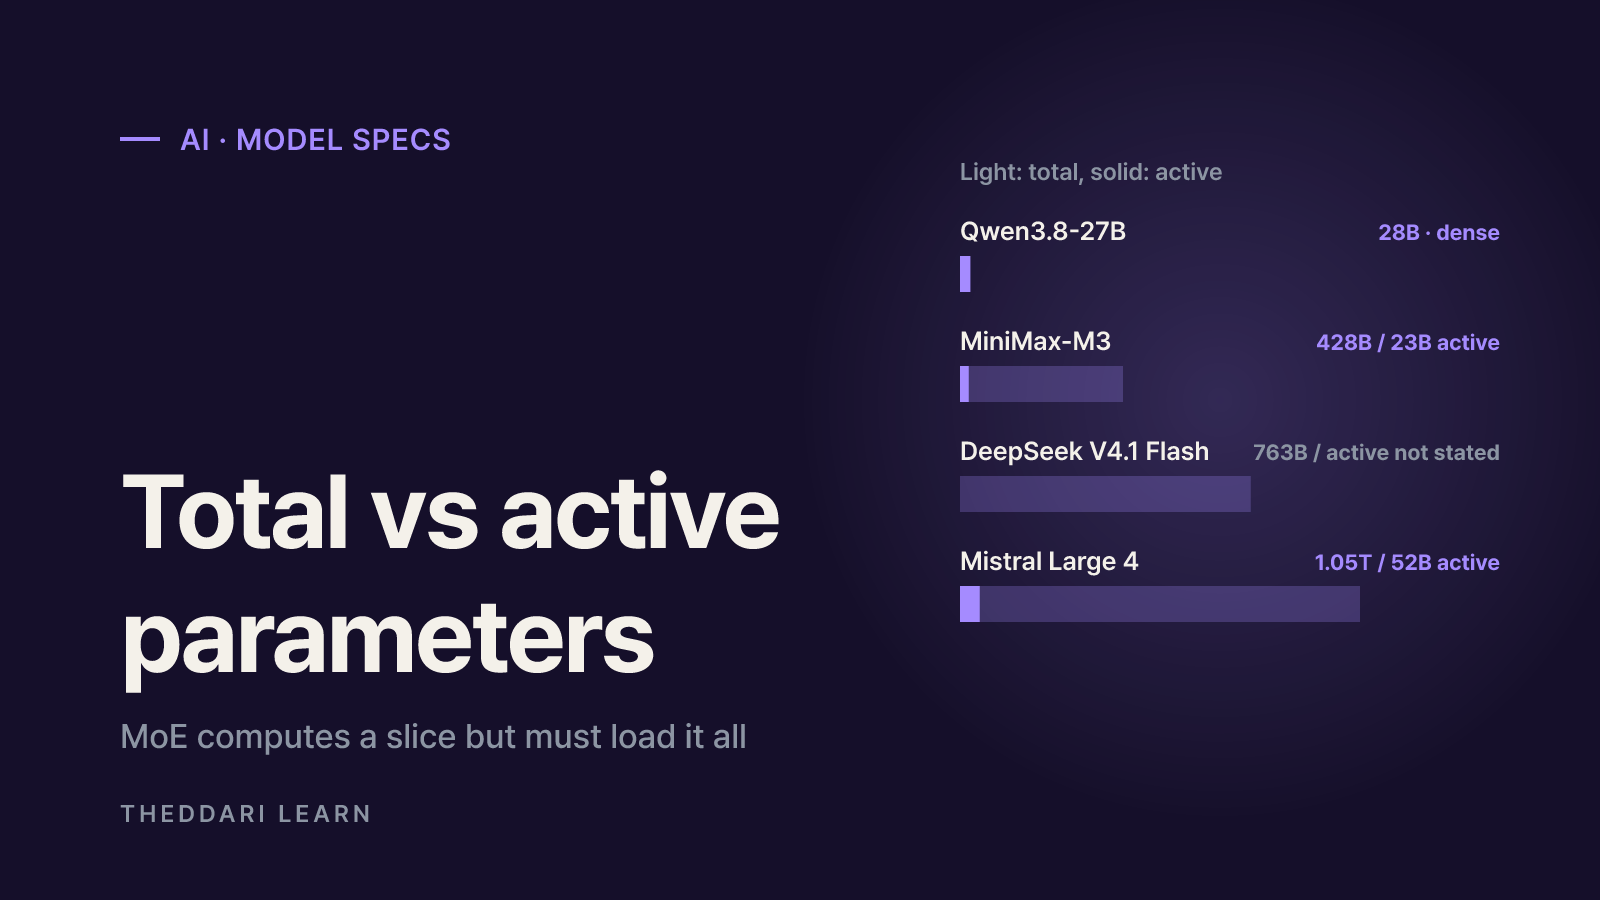
The table below only uses values stated on the model cards. "Active parameters" applies to mixture-of-experts (MoE) models: it is the slice of the network used for each token. A dense model like Qwen3.8-27B uses all of its parameters every time.
Architecture
- Qwen3.8-27B
- Dense, image and video input
- DeepSeek V4.1 Flash 1017
- MoE, image input
- MiniMax-M3
- MoE, text, image and video
- Mistral Large 4
- MoE, image input
Total parameters
- Qwen3.8-27B
- 27B (about 28B with vision)
- DeepSeek V4.1 Flash 1017
- About 763B
- MiniMax-M3
- About 428B
- Mistral Large 4
- About 1.05T
Active parameters
- Qwen3.8-27B
- 27B (all)
- DeepSeek V4.1 Flash 1017
- Not stated on card
- MiniMax-M3
- About 23B
- Mistral Large 4
- 52B
Context window
- Qwen3.8-27B
- 262,144 native, up to 1M with YaRN
- DeepSeek V4.1 Flash 1017
- 1M recommended
- MiniMax-M3
- 1M
- Mistral Large 4
- 1M
License
- Qwen3.8-27B
- Apache 2.0
- DeepSeek V4.1 Flash 1017
- MIT
- MiniMax-M3
- MiniMax Community License
- Mistral Large 4
- Check when weights ship
Status
- Qwen3.8-27B
- Weights available
- DeepSeek V4.1 Flash 1017
- Weights available
- MiniMax-M3
- Weights available
- Mistral Large 4
- API preview Oct 6; weights due end of October
Sources: Qwen3.8-27B card, DeepSeek-V4.1-Flash-1017 card, MiniMax-M3 card, Mistral Large 4 docs. The DeepSeek card does not state an active parameter count; 763B is the stored model size Hugging Face reports.
License terms: what you can do commercially
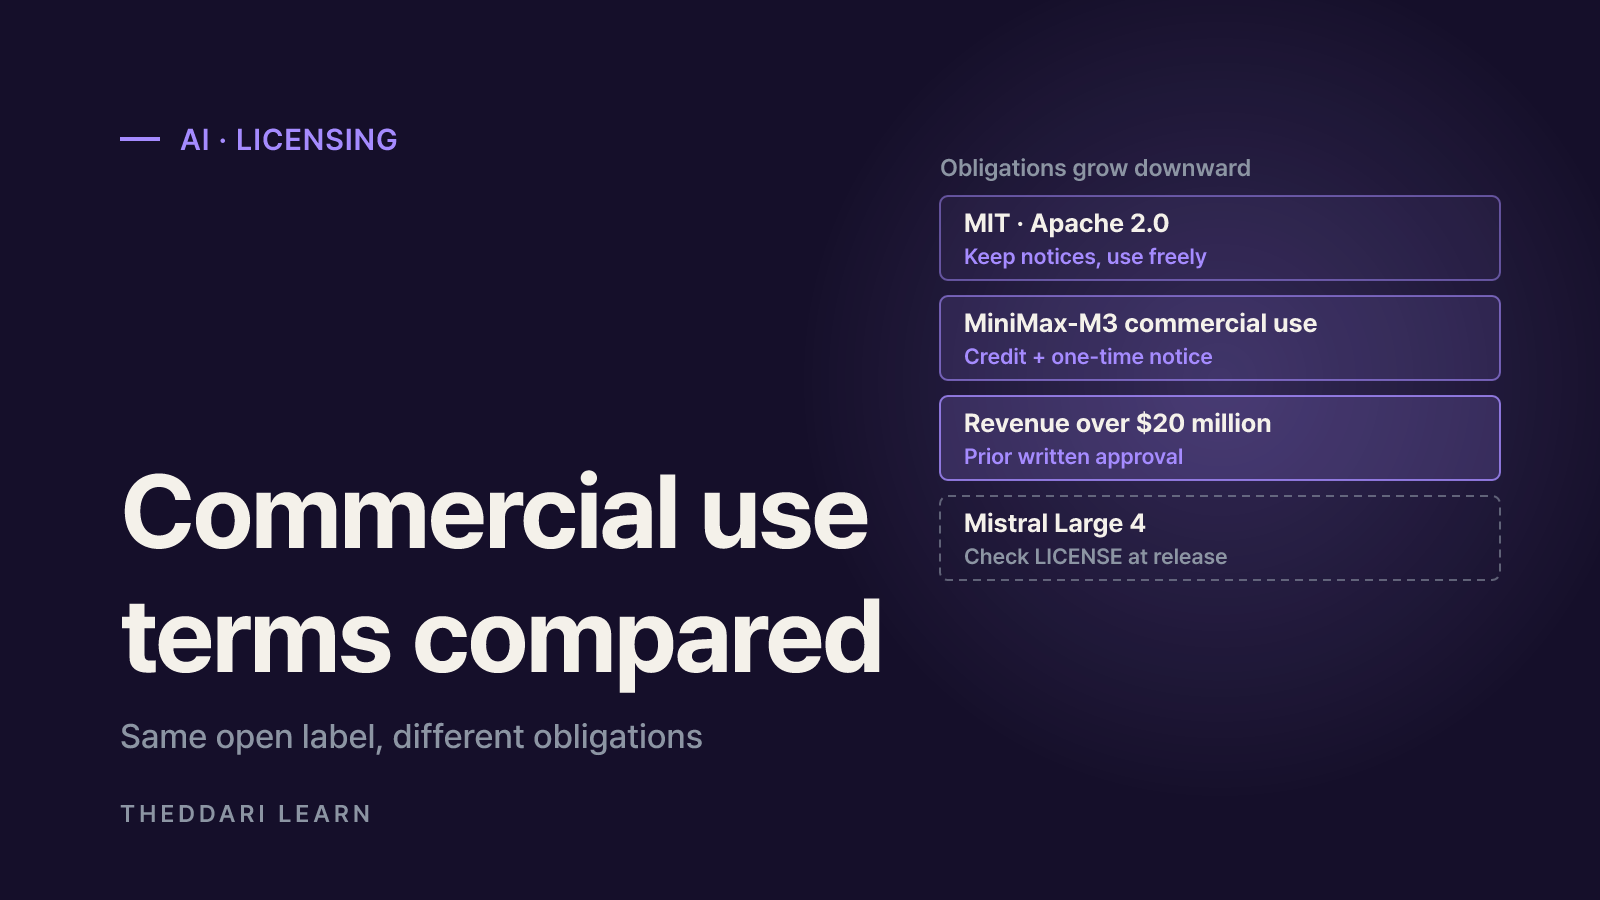
Two "open" models can come with very different rights. If you plan to ship a product or distribute a fine-tuned model, check this before you look at benchmarks.
- MIT (DeepSeek V4.1 Flash 1017): both the code and the weights are MIT. Keep the copyright and license notice and you can modify, sell and redistribute.
- Apache 2.0 (Qwen3.8-27B): commercial use and modification are allowed; redistributions must include the license and note your changes. It also includes an explicit patent grant, which legal teams tend to like.
- MiniMax Community License (MiniMax-M3): per the license text, the base grant covers non-commercial use. Commercial use requires a prominent "Built with MiniMax M3" credit and a one-time notice to MiniMax; products or services above $20 million in yearly revenue need prior written authorization. There is also a list of prohibited uses, including military purposes.
- Mistral Large 4: the launch post promises open weights by the end of the month but does not name a license on the pages reviewed. Read the LICENSE file in the repository once it is published.
MiniMax's license explicitly counts commercial deployment of fine-tuned or otherwise modified derivatives as commercial use. Internal experiments are one thing; the moment customers touch it, the credit and notice duties apply.
Hardware: how much memory each local LLM needs
A quick sanity check is parameter count × bytes per parameter. BF16 uses 2 bytes, 8-bit formats (FP8 or INT8) use 1 byte, and 4-bit quantization uses roughly half a byte. You also need room for the KV cache, which grows with context length, plus runtime overhead, so treat these numbers as floors.
Qwen3.8-27B (about 28B)
- BF16 (2 bytes)
- About 56GB
- 8-bit (1 byte)
- About 28GB
- 4-bit (0.5 byte)
- About 14GB
MiniMax-M3 (about 428B)
- BF16 (2 bytes)
- About 856GB
- 8-bit (1 byte)
- About 428GB
- 4-bit (0.5 byte)
- About 214GB
DeepSeek V4.1 Flash 1017 (about 763B)
- BF16 (2 bytes)
- Shipped as mixed FP8
- 8-bit (1 byte)
- About 763GB
- 4-bit (0.5 byte)
- About 382GB
Mistral Large 4 (about 1.05T)
- BF16 (2 bytes)
- About 2.1TB
- 8-bit (1 byte)
- About 1.05TB
- 4-bit (0.5 byte)
- About 525GB
The key takeaway: a small active parameter count does not shrink memory needs. MiniMax-M3 activates about 23B parameters per token, fewer than Qwen3.8-27B, yet all 428B must sit in memory because any expert might be selected. What MoE buys you is speed: less compute per token at the same memory footprint.
- Qwen3.8-27B: at 4-bit it is worth trying on a 24GB card or a machine with plenty of unified memory. Hugging Face lists 1,544 quantized derivatives, so llama.cpp, Ollama and LM Studio builds are easy to find.
- MiniMax-M3 and DeepSeek V4.1 Flash: the recommended path is a serving engine such as SGLang or vLLM across several data-center GPUs. That is a lab or company setup, not a hobby rig.
- Mistral Large 4: at roughly a trillion parameters, self-hosting means a sizable GPU cluster. Most people will start with the API.
Picking by use case: coding, agents, documents and languages
Coding and agent workflows
All four vendors pitch coding and long-horizon agent work. Qwen3.8-27B thinks by default and lets you set reasoning_effort to low, medium or xhigh. MiniMax-M3 exposes a thinking switch with enabled, adaptive and disabled modes. Lower effort can save tokens, but the Qwen card warns that in multi-turn agent tasks it can also cause more failures and retries, raising total latency and cost.
Long documents and multimodal input
MiniMax-M3, DeepSeek V4.1 Flash and Mistral Large 4 are built around a 1M-token context. Qwen3.8-27B is 262,144 tokens natively and can be stretched to 1M with YaRN, but its card notes that static YaRN can hurt performance on shorter inputs, so only enable it when you need it. If you need video understanding, start with Qwen3.8-27B or MiniMax-M3, which list video input.
Non-English workloads
Mistral says Large 4's training data spans more than 160 languages, including every official EU language, but none of the cards reviewed publish per-language scores you can compare across vendors. If a specific language matters, test it yourself with real prompts.
Self-host or API: a decision checklist
- 1
Decide whether data can leave your network
Sensitive or regulated data points to self-hosting or an API with region controls. Mistral says it runs a European deployment end to end.
- 2
Filter by license
For commercial products, start with the MIT and Apache 2.0 models. Include MiniMax-M3 only if you can meet its credit and notice terms.
- 3
Filter by hardware
Use the memory table above. Anything that does not fit, trial through an API or a Hugging Face inference provider.
- 4
Run your own evaluation
Run 30 to 50 real prompts through each candidate with identical settings and log accuracy, latency and output length.
- 5
Compare monthly cost
Price API usage per token (Mistral Large 4 preview: $1.36 input and $4.18 output per million tokens) against GPU, power and staff time for self-hosting.
Open-weight releases move fast. The AI Telegram trends page is a quick way to catch news such as the Mistral Large 4 weight drop, and blog trends shows which hands-on comparisons and reviews are gaining traction.

Benchmark traps and deployment risks
- Do not compare scores across harnesses: on DeepSWE 1.1, the Qwen card reports 42.2 with the Claude Code harness, the DeepSeek card reports 77.0 with the Mini-SWE-V2 harness, and Mistral reports 61.7%. Different tooling and settings make these numbers unsuitable for ranking.
- Discount in-house benchmarks: evaluations such as QwenSWEBench and CoWorkBench are built by the vendor. Prefer public benchmarks or your own tests.
- Review remote code: loading MiniMax-M3 with Transformers requires
trust_remote_code=True, which executes code from the repository. Pin a revision and review it first. - Mind the prompt format: DeepSeek V4.1 Flash 1017 ships without a Jinja chat template and relies on its own encoding code (the
encodingfolder and deepseek-recipe). Generic tooling may format prompts incorrectly. - Preview models keep changing: Mistral says Large 4's reinforcement learning run is still in progress. Avoid locking in long-term decisions based on preview results.
In short: pick Qwen3.8-27B for a local LLM on one GPU, DeepSeek V4.1 Flash 1017 for the most permissive license at large scale, MiniMax-M3 for a 1M-token multimodal agent if its conditional commercial terms work for you, and Mistral Large 4 if you want a European-hosted API now and open weights soon. Whichever you shortlist, let results on your own data make the final call.