Contents7 sections
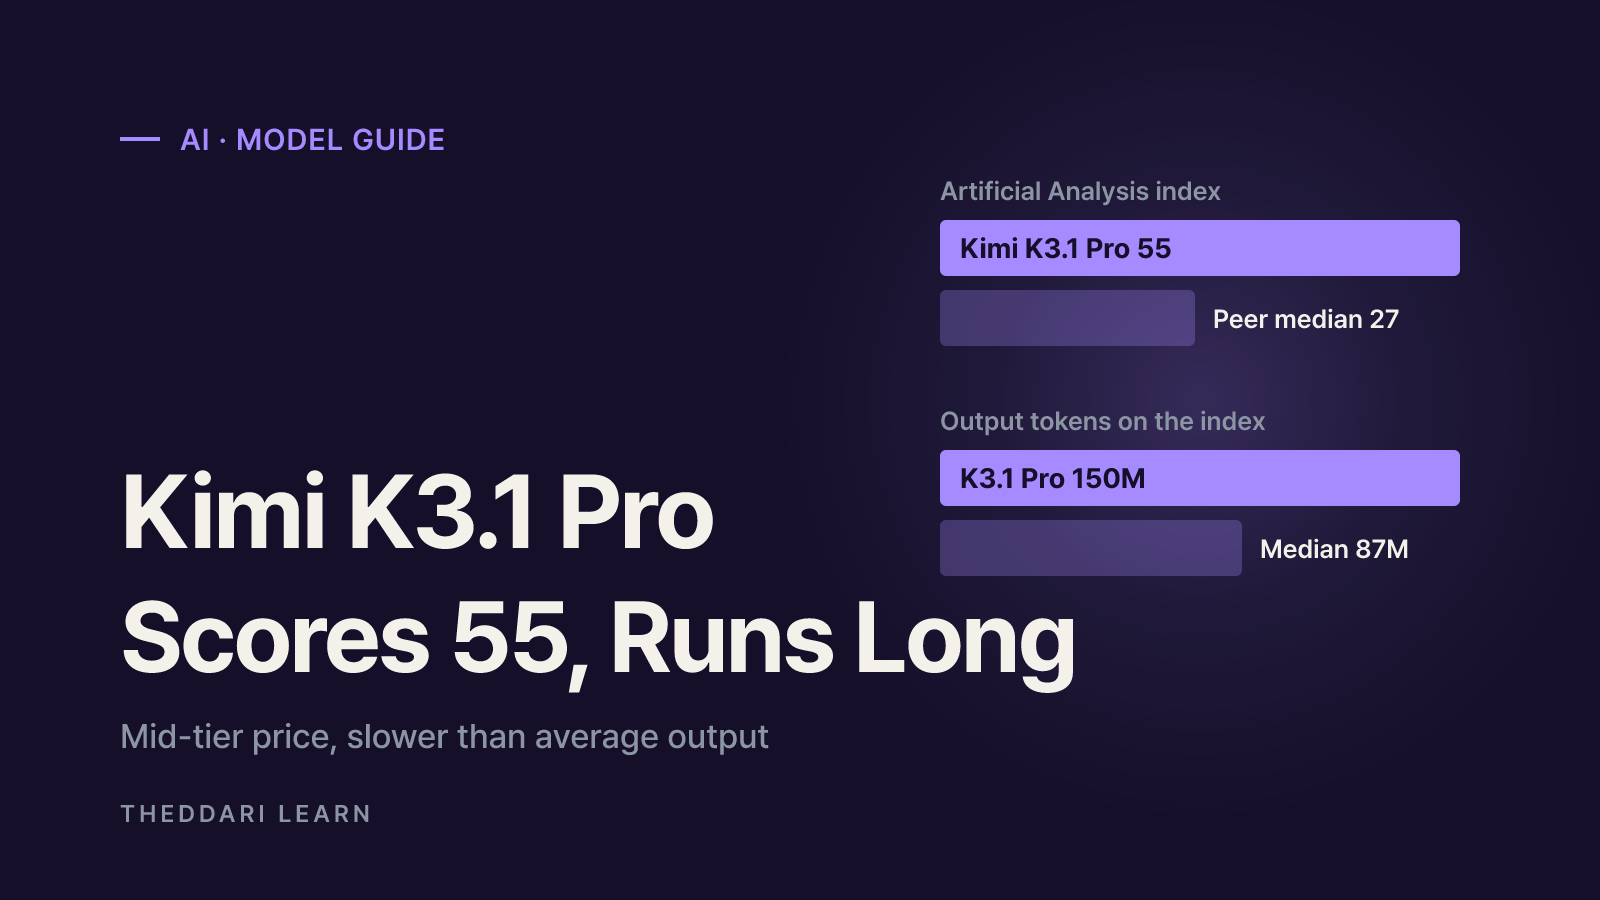
Kimi K3.1 Pro is Moonshot AI's newest flagship model, released on October 23, 2026, and it landed near the top of the independent Artificial Analysis Intelligence Index with a score of 55. The short version: it benchmarks like a frontier model, it is priced at the middle of its tier, and it is slower and far more verbose than average, which pushes real costs above what the list price suggests. This guide is based on the official Kimi blog, the Artificial Analysis model page and the Kimi API docs, all checked as of October 24, 2026.
What is Kimi K3.1 Pro?
Moonshot describes K3.1 Pro as a post-trained version of Kimi K3 that received substantially more post-training compute, with reinforcement learning run jointly across hundreds of domains. The company highlights coding, 3D creation, financial research and long-running agent tasks as its main improvements.
- Context window: 1,048,576 tokens, shared across the K3 series.
- Modalities: text and image in, text out. The API docs also show video file input.
- Size: Moonshot calls it a "3T-class" model; Artificial Analysis lists 2.8 trillion parameters.
- Reasoning: thinking is always on and cannot be disabled. You pick
reasoning_effortof low, high or max, and the default is max. - Highspeed variant: Kimi K3.1 Pro Highspeed is billed as 2-3x faster for more responsive use.
- Availability: Kimi.ai and mobile apps, Kimi Work, Kimi Code and the Kimi API today, with full weights promised by November 4, 2026.
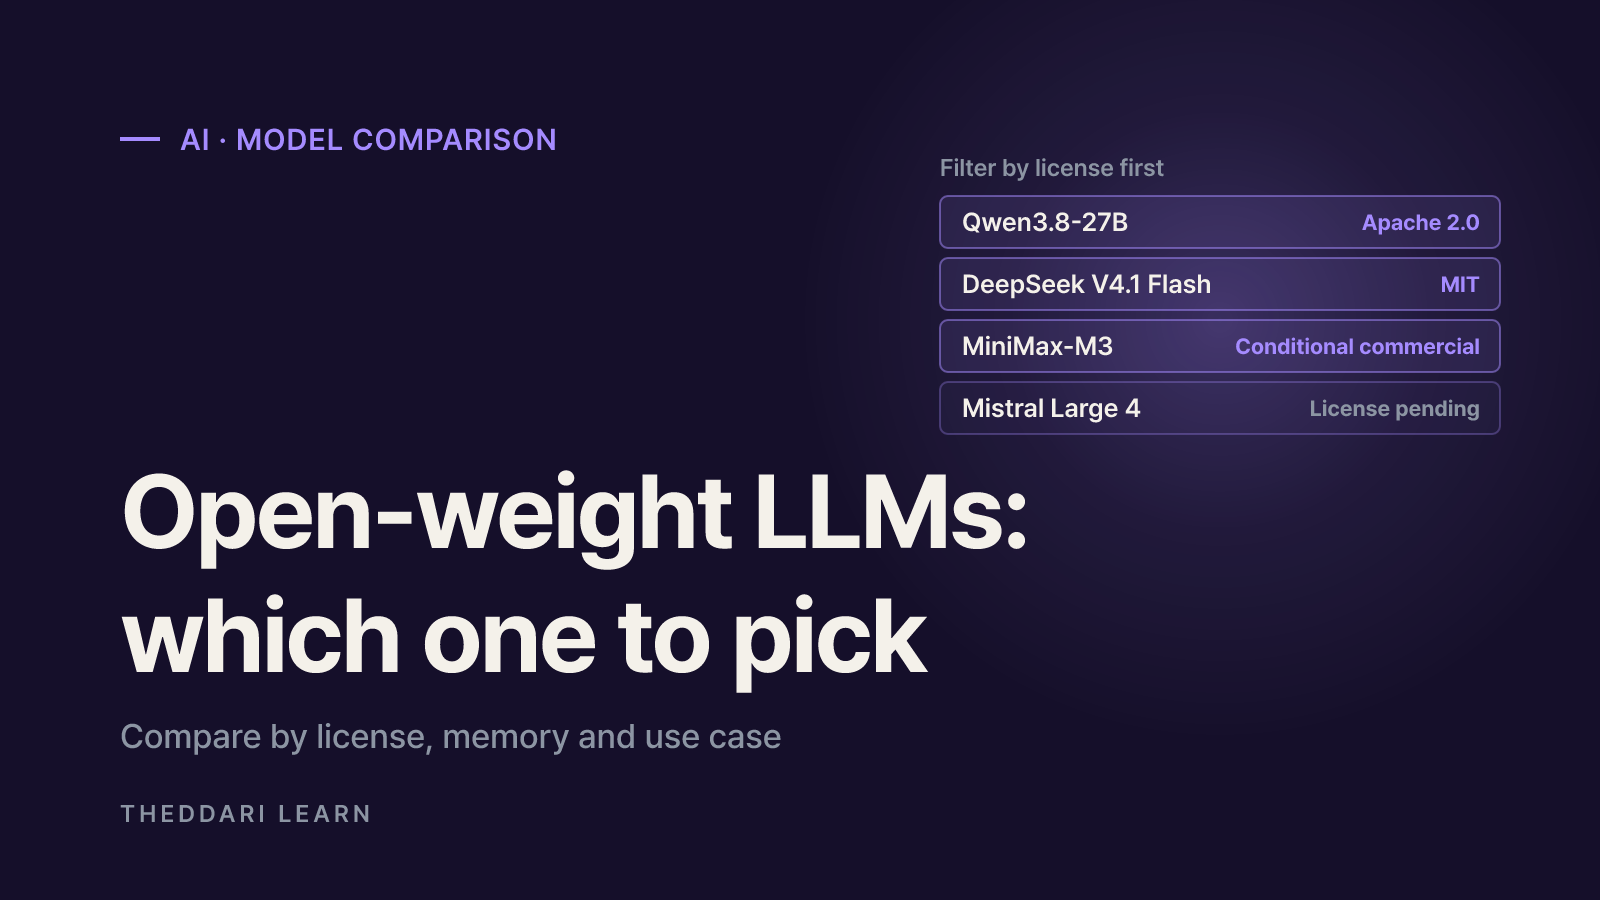
Treat the "open-weight" label as a promise for now. As of October 24, 2026, Artificial Analysis classifies Kimi K3.1 Pro as proprietary because the weights are not yet public. If you are planning local or on-prem deployment, wait for the actual weights and license terms.
What the Artificial Analysis score of 55 measures
The Intelligence Index v4.3.2 is not a single test. According to the methodology page, it is a weighted average of 10 evaluations split into Agents (30%), Coding (20%), Scientific Reasoning (20%) and General (30%). Artificial Analysis also notes the suite is primarily English and text-based; image and multilingual performance are measured separately.
Agents (30%)
- Evaluations
- AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA
- What it tests
- Multi-file knowledge work, SaaS workflow automation
Coding (20%)
- Evaluations
- Terminal-Bench 4.0, SciCode
- What it tests
- Terminal tasks, scientific Python
General (30%)
- Evaluations
- AA-Omniscience, GDP.pdf, AA-LCR v1.1
- What it tests
- Knowledge and hallucination, long-PDF and long-context reasoning
Scientific Reasoning (20%)
- Evaluations
- Humanity's Last Exam, CritPt
- What it tests
- Hard knowledge questions, physics reasoning
Rank versus median
The model page shows K3.1 Pro at #4 of 215 for intelligence and cites a median of 27 among similarly priced models. Proprietary models are compared against models in the same blended price band (3:1 input-to-output), so that rank is relative to a peer group, not the whole market. Differences of a point or two can move with repeat runs and grading, so avoid treating them as decisive.
What "on the Pareto line" means
The Hacker News headline that drew attention said the model sits on Artificial Analysis's Pareto line. A Pareto frontier is the boundary where no other model scores higher for the same cost, so being on it signals strong score-per-dollar. Keep in mind the cost axis is the weighted average cost of one index task; your own prompt lengths, output lengths and cache hit rate will shift the math. The placement appears on the chart rather than in the page text.
Kimi K3.1 Pro price, speed and token use
The figures below combine Artificial Analysis measurements of Kimi's first-party API with list prices from the Kimi API Platform, as of October 24, 2026. All prices are in US dollars and exclude tax.
Intelligence Index
- Kimi K3.1 Pro
- 55
- Reference
- Peer median 27
Input price per 1M tokens
- Kimi K3.1 Pro
- $2.00
- Reference
- Median $2.00
Output price per 1M tokens
- Kimi K3.1 Pro
- $10.00
- Reference
- Median $10.00
Cache hit price
- Kimi K3.1 Pro
- $0.20 (90% off)
- Reference
- vs. standard input
Cost per index task
- Kimi K3.1 Pro
- $2.11
- Reference
- #85 of 113
Output speed
- Kimi K3.1 Pro
- 77.1 tokens/s
- Reference
- Median 81
Time to first token
- Kimi K3.1 Pro
- 3.08 s
- Reference
- Median 3.54 s
Output tokens on the index
- Kimi K3.1 Pro
- 150M
- Reference
- Median 87M
The number to watch is token use. Unit prices match the median, yet the model generated roughly 1.7 times the median output tokens to finish the same evaluations. Always-on reasoning produces many thinking tokens before an answer, which raises both cost and wait time. That is why its cost-per-task rank sits well behind what the unit prices alone would suggest. Artificial Analysis also lists a blended rate of $1.54 per million tokens assuming a 7:2:1 mix of cache hits, input and output.
Highspeed tier and caching
Kimi K3.1 Pro Highspeed (kimi-k3.1-pro-highspeed) costs $4.00 input and $20.00 output per million tokens, double the standard tier. It makes sense for chat or interactive coding where latency matters; long batch jobs usually favor the standard model. Context caching applies automatically to repeated prefixes, with a default 5-minute TTL and an optional 1-hour TTL for workloads with longer gaps between calls.
Reading Moonshot's own Kimi benchmark claims
Moonshot reports 65.7% on Terminal-Bench 4.0, ahead of GPT-6 Astra (58.2%) and just behind Claude Opus 5.5 (66.4%). It also cites 92.7% with tools on the BenchCAD 3D reconstruction test and a state-of-the-art 64.4 on OfficeQA Pro v2 for financial documents. Before relying on these:
- Mixed sourcing. Kimi's runs use a Claude Code harness, while many rival scores are copied from other companies' reports or leaderboards.
- Max effort. Unless noted, results use maximum reasoning effort. Lower settings change both scores and spend.
- Internal tests. Kimi Code Bench, the internal finance suites and the hallucination benchmark cannot be independently reproduced.
- Inconsistent hallucination figures. The blog says claim-level hallucination fell from 23.4% to 8.3% versus K3, while the API docs say 23.35% to 6.85% and describe the test differently. Moonshot itself says neither reflects everyday error rates.
Terminal-Bench 4.0 is also part of the Artificial Analysis index, but the index blends 10 evaluations, so it will not line up one-to-one with any single vendor headline.
Checklist before you use it
- 1
Run your own task set
The index skews English and text-only. Pick 10 to 20 real tasks, such as summarizing your documents or editing your codebase, and compare against your current model under identical prompts.
- 2
Recompute cost from actual usage
Check the usage fields on test calls for input, output and cached tokens. Try reasoning_effort set to low or high to see whether quality holds at a lower bill.
- 3
Confirm API access rules
The model unlocks after a minimum $1 top-up, and cumulative top-ups determine concurrency, RPM, TPM and daily token limits. Temperature, top_p and similar parameters are fixed, so omit them, and send images as base64 or file IDs.
- 4
Review data handling and jurisdiction
Moonshot says Zero Data Retention is available to API customers, but confirm how it is enabled under your agreement. Kimi Enterprise admins must switch K3.1 Pro on, since access is off by default. Regional availability was not stated in the docs reviewed here, so check the terms for your country.
- 5
Plan K2 migrations
Kimi API stops offering K2-series models to new sign-ups from October 31, 2026 and plans to retire the K2 series by the end of December 2026.
The built-in web search tool is still being updated, and the docs advise against using it in production workflows for now. Pair the model with your own search tool if you are building retrieval agents.
Model launches move fast, and community chatter often runs ahead of official docs. You can follow how often new releases like this come up in theddari's Telegram AI trends feed and its blog trend tracker.
 theddari.comTrendsBlog PostsSummarized Naver blog posts
Bottom line: Kimi K3.1 Pro posts a top-tier independent score at a mid-tier unit price, but slow output and heavy reasoning tokens can make it more expensive in practice than the rate card implies. Wait for the weights and license if self-hosting matters to you, confirm data retention terms, and let a small benchmark on your own workload make the final call.