What Is Recursive Self-Improvement in AI? What New Research Shows and Its Limits
What recursive self-improvement (RSI) in AI means, what Sakana AI's MASS and the RSI-Anything paper actually improved, and where the limits are today.
目录7 个章节
核心要点
- Recursive self-improvement (RSI) is a loop in which an AI system improves itself and the improved version then drives the next round of improvement.
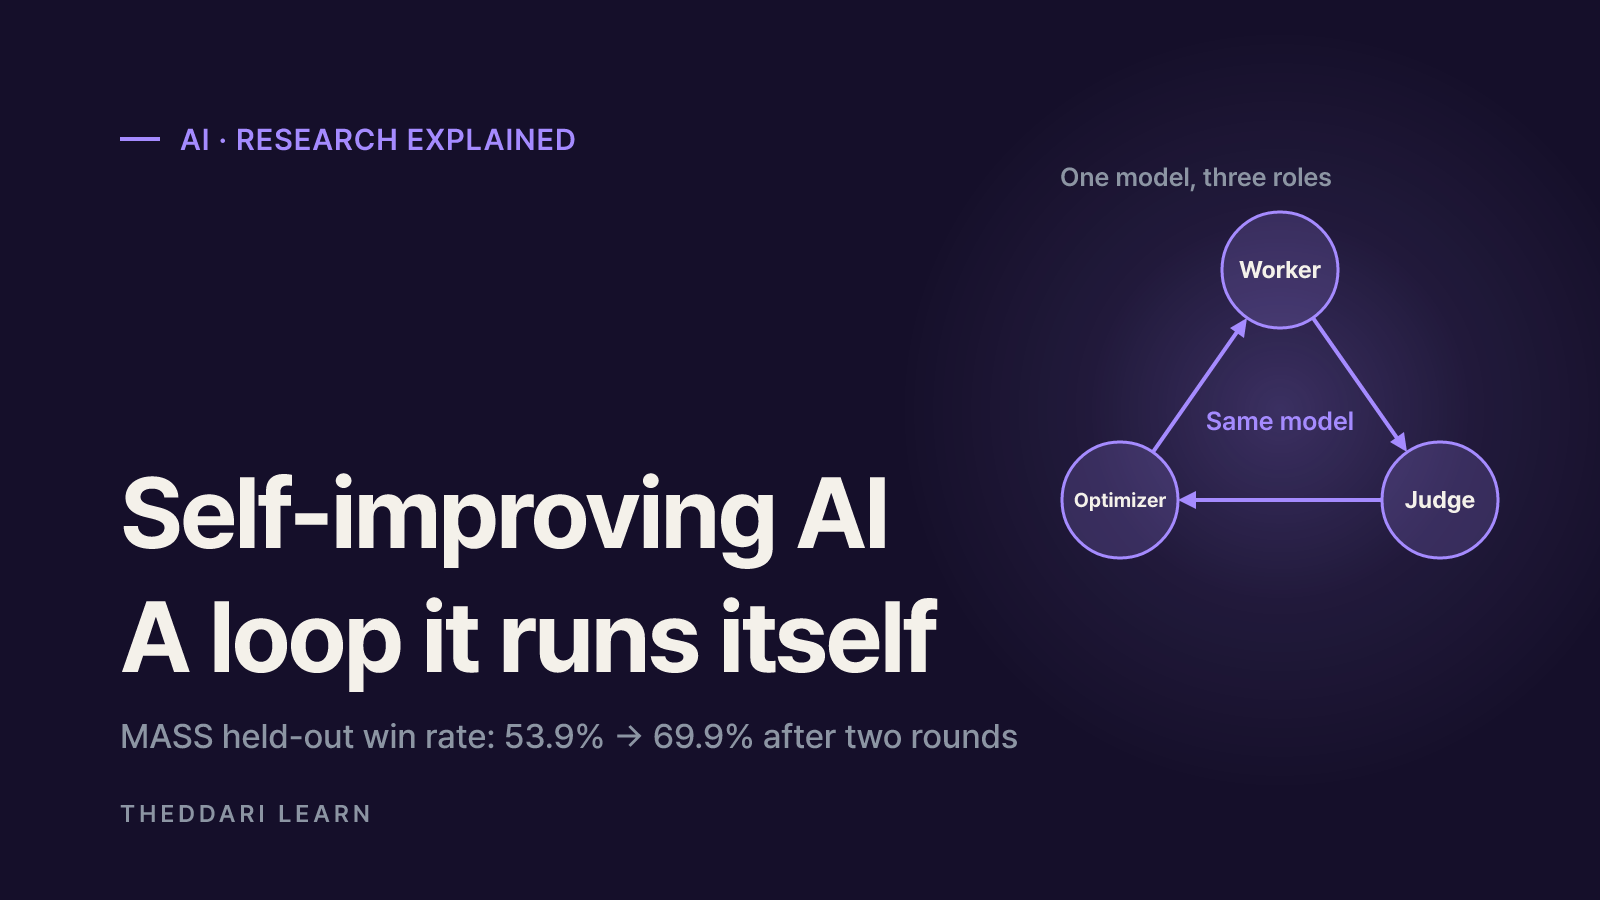
- Sakana AI and UC Berkeley's MASS uses one model as worker, optimizer and judge; after two rounds its win rate against the base model on held-out tasks reached 69.9% under external judges.
- RSI-Anything uses predictive world models to pick actions and training data, lifting code-repair success from 26.3% to 31.2% with the coder held fixed.
- Gains are uneven: MASS scored 0.94x the base model's score per output token on SWE-bench Verified.
- Both papers are arXiv preprints as of October 2026, and the authors flag shared blind spots in self-judging loops as a core safety risk.
Recursive self-improvement (RSI) is the idea that an AI system can make itself better, and that each improved version can then do a better job of improving the next one. As of October 2026, the published evidence does not show an AI that improves without limit. It shows something narrower but still interesting: models raising their scores on specific tasks over a few rounds, inside loops that humans designed. This guide walks through two preprints posted to arXiv on October 8 and 9, 2026, MASS from Sakana AI and UC Berkeley and RSI-Anything, and explains what actually improved and what did not.
What recursive self-improvement means
The Wikipedia overview defines RSI as a process in which an AI system iteratively designs a more capable successor, and links it to the hypothesis of an intelligence explosion. The key word is recursive. It is not a single upgrade. The output of one improvement step becomes the tool for the next step, and the loop keeps running.
Researchers usually split that loop into three jobs. The optimizee does the task. The optimizer changes how the task is done. The evaluator decides whether the new result is better. When one model fills all three roles, the MASS authors call it homogeneous RSI. It removes the need for a human answer key, but it also means a mistaken judge can steer the whole system in the wrong direction.
Optimizee (worker)
- What it does
- Produces the actual output
- What goes wrong if it fails
- Lower-quality work
Optimizer
- What it does
- Revises the workflow based on feedback
- What goes wrong if it fails
- Good feedback goes unused
Evaluator (judge)
- What it does
- Picks the better of two outputs
- What goes wrong if it fails
- Flawed work is kept as training data
An earlier, narrower example: AlphaEvolve
Google DeepMind announced AlphaEvolve on May 14, 2025. It found a way to split a matrix multiplication kernel that sped it up by 23% inside Gemini's architecture, cutting Gemini training time by 1%, including for the models that power AlphaEvolve itself. The catch is that AlphaEvolve relies on automated evaluators that can verify answers, which suits math and computing but not open-ended work like research reports.
Sakana AI's MASS: learning from a team of copies
MASS (Multi-Agent Self-Supervision) targets non-verifiable research tasks, where no rule-based grader exists. The same model runs a multi-agent team, judges the team's work, and then trains on the best team runs.
- 1
Inner loop: search for a better workflow
With weights frozen, the model rewrites a written workflow covering each subagent's role, instructions, output contract and call order. If the self-evaluator prefers the new result, it becomes the champion.
- 2
Outer loop: train on the best runs
Each champion workflow runs 18 times per task. The model ranks the results and keeps up to 16 trajectories (15 for training, one for validation), then fine-tunes itself with LoRA after removing the workflow text from the prompt.
- 3
Repeat
The updated model takes over all three roles for the next round.
Starting from Qwen3.6-27B, the team ran two rounds on 12 synthetic research tasks in finance, robotics and pharmacy, with three held out. According to Sakana AI's write-up, the win rate against the base model on held-out tasks rose to 53.9% after round one and 69.9% after round two, as scored by GPT-5.5 and Claude Opus 4.8, which were kept out of the training loop. On MLR-Bench, DSBench, ScienceAgentBench and AstaBench, score per output token reached 1.2x to 1.6x the base model.
Notable findings from MASS
- Role generalization: training only on task-solving runs also improved the optimizer and evaluator. Agreement with external judges rose from 73% to 93% across three cycles.
- The optimizer can be the bottleneck: swapping in GPT-5.5 as evaluator alone found winning workflows for 10 of 12 tasks; upgrading both evaluator and optimizer found all 12 within five iterations. The all-base loop reached 11 of 12 by iteration 13.
- Denser training signal: a model trained on multi-agent runs reached a 68.3% win rate after 28.8M supervised tokens, versus 64.0% after 42M tokens for single-agent runs.
RSI-Anything: using world models to choose what to learn
RSI-Anything, submitted October 9, 2026, starts from two practical problems: outside feedback is expensive, and a world model's predictions drift as the policy changes. Built on JEPA-Anything, it uses predictive world models to choose actions and training data, then keeps an updated policy-model pair only if it passes component and compatibility checks. In other words, not every change is allowed to stick.
Code repair (coder fixed)
- Comparison
- Static verifier vs predictive selection vs world-model adaptation
- Reported result
- 26.3% vs 29.2% vs 31.2% success
GUI tasks
- Comparison
- Against baseline
- Reported result
- Higher completion, 39.4% fewer actions on average
Lab planning
- Comparison
- Five successive policy versions
- Reported result
- 21.80% to 46.01%
Reaction optimization
- Comparison
- Bayesian optimization, same 40-experiment budget
- Reported result
- 96.15% vs 82.16% mean best yield
The code-repair gain is about five percentage points: a steady improvement from better data selection, not a sudden leap. The lab-planning jump happened across five versions, not in one step.
Limits of recursive self-improvement research today
- Uneven transfer. MASS scored 0.96x on Terminal-Bench 2.0 and 0.94x on SWE-bench Verified, below the base model on score per output token.
- Short horizons. MASS reports two rounds and RSI-Anything five policy versions. Nobody has shown the gains keep compounding.
- Noisy search. The MASS authors note that strong workflow iterations can be followed by sharp regressions.
- Human scaffolding. Task design, external judges, structural guardrails and retention checks were all set by people.
- Not yet peer reviewed. Both papers are v1 preprints as of October 2026, so numbers may change after replication.
The MASS authors call shared blind spots a possible Achilles' heel of RSI. When one model both produces and grades the work, a flaw can be accepted as an improvement, absorbed into the next model, and reinforced with each round, especially if humans also miss it. Critics raise a related concern about model collapse from training on self-generated data.
How to read the next RSI headline
- What changed: model weights, prompts and workflows, or data selection?
- Who judged: the model itself, another model, humans, or an automatic verifier?
- Did it improve on tasks it never trained on?
- Was the compute or experiment budget held constant?
- How many rounds were run before the claim was made?
AI research claims spread quickly and often lose their caveats along the way. To trace where a story started, compare the AI Telegram trends on theddari with the blog trends feed and check each claim against the original paper.

常见问题
What is the difference between recursive self-improvement and normal AI training?
Is recursive self-improvement already happening?
Could RSI lead to an intelligence explosion?
Why does it matter who the evaluator is?
来源与参考资料
- 1MASS: Recursive self-improvement through collective intelligence (Sakana AI)(在新标签页中打开)pub.sakana.ai
- 2arXiv:2610.12176 Recursive Self-Improvement through Multi-Agent Self-Supervision(在新标签页中打开)arxiv.org
- 3arXiv:2610.13912 RSI-Anything: Unlocking Recursive Self-Improvement with World Models(在新标签页中打开)arxiv.org
- 4Google DeepMind: AlphaEvolve, a Gemini-powered coding agent(在新标签页中打开)deepmind.google
- 5Wikipedia: Recursive self-improvement(在新标签页中打开)en.wikipedia.org
相关文章
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.