LIBERO-PeRM: Can Robots Learn Each User's Preferences?
LIBERO-PeRM is a NeurIPS 2026 benchmark scoring task success and user-preference satisfaction separately. See what it measures and where VLAs fall short.
目录9 个章节
核心要点
- LIBERO-PeRM is a personalized robot manipulation benchmark that reports task success (SR) and preference satisfaction (SA) as two separate numbers.
- As released in October 2026, it contains 312 tasks in five suites, 37 single preferences, 18 preference pairs and about 40.8K demonstrations, all in LIBERO simulation.
- Preferences come in three levels: motion, skill and user profile. None of them changes the task goal, only how the task is carried out.
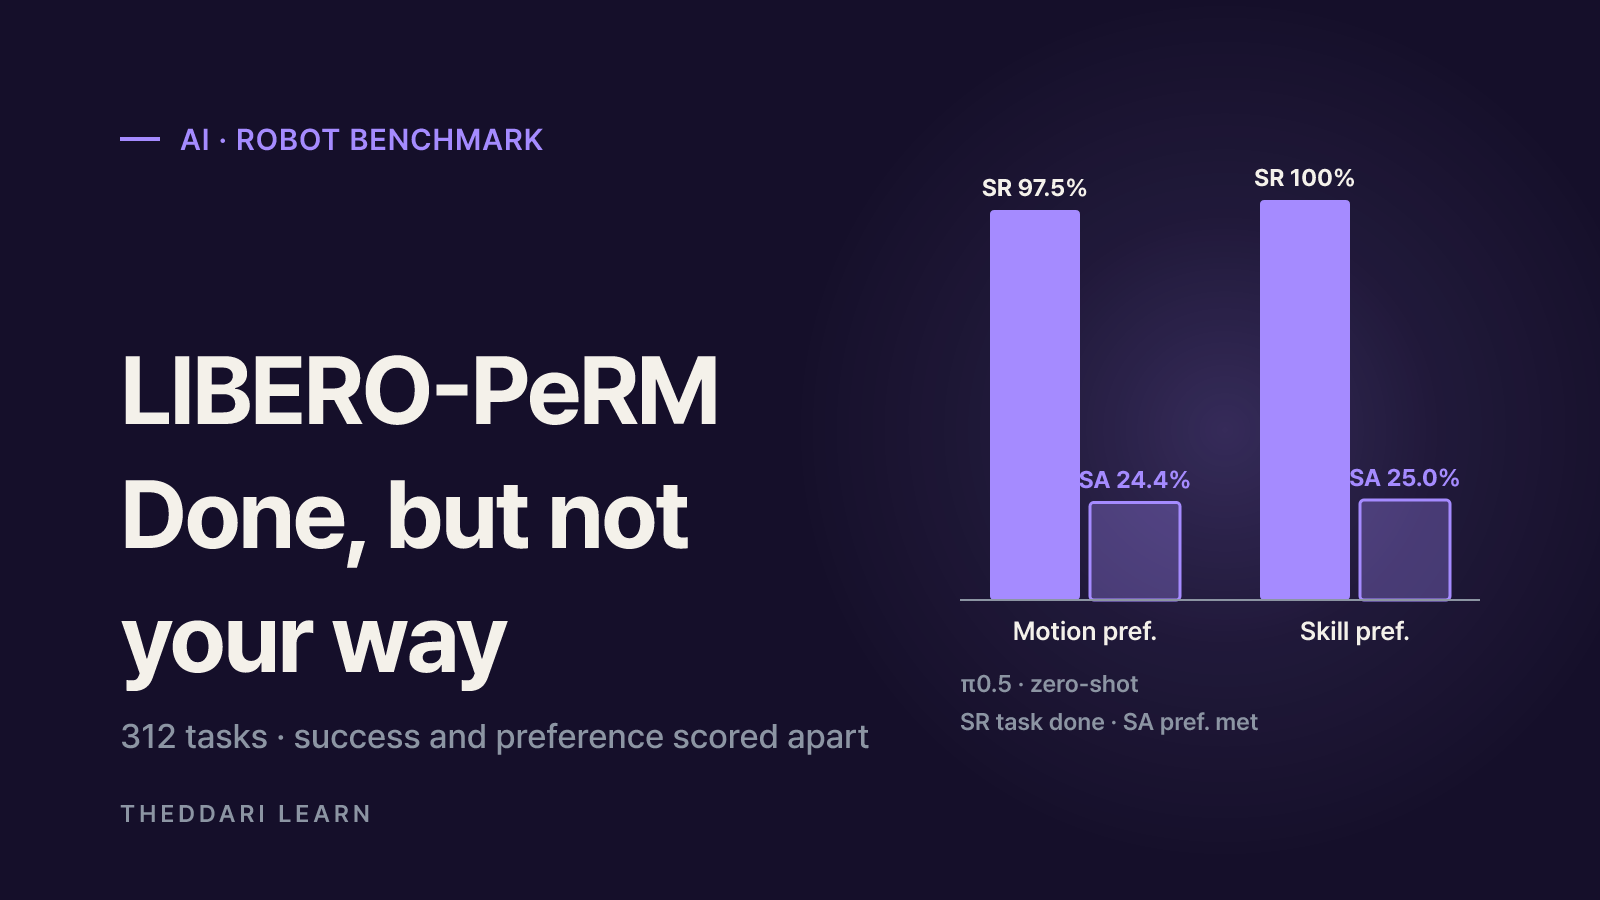
- Zero-shot, π0.5 finished 97.5% of motion-preference tasks but satisfied the preference only 24.4% of the time.
- Fine-tuning makes preferences learnable, but generalizing to new layouts and resolving conflicting preferences remain open problems.
LIBERO-PeRM is a robot manipulation benchmark that asks a simple question: can a policy do the task the way you want it done? Released on arXiv on October 15, 2026 (paper, project page) and listed as a NeurIPS 2026 Evaluations and Datasets Track paper, it separates two things most robot benchmarks blend together: finishing the task and respecting a user's preference. The short answer from its first round of experiments, as of October 2026, is that today's vision-language-action (VLA) models usually finish the task and ignore the preference unless they are fine-tuned for it.
What LIBERO-PeRM measures
Picture a household robot asked to put a mug on a shelf. One person wants it moved slowly. Another wants the arm to stay clear of a knife on the counter. A third always wants the red mug used first. The goal is identical, but the acceptable execution is not. The authors call this personalized robotic manipulation (PeRM) and argue it is essential if general-purpose robots are going to be practical at home. Their point is that the field lacked a controlled benchmark that could tell task completion and preference satisfaction apart.
The benchmark was built by ten researchers from UC Riverside, Yale, Georgia Tech, the University of Michigan and the University of Toronto. Code, datasets and demos are public.
| Item | Details (October 2026 release) |
|---|---|
| Tasks | 312, split into five suites |
| Preference levels | Motion, skill, user profile |
| Preferences | 37 single, 18 paired |
| Demonstrations | About 40.8K, paired with and without preference |
| Models tested | Six open VLA policies, plus π0.5 fine-tuning runs |
| Environment | LIBERO simulation |
A preference changes the how, not the what
In LIBERO-PeRM, a preference is not a second goal. It is a conditioning signal that biases execution while the task goal stays fixed. The scope is deliberately narrow: preferences must be expressible in language, instantiable in LIBERO without changing the goal, scored automatically and reusable across tasks. The policy receives one prompt in the form "Task: … Preference: …" plus images from a third-person camera and a wrist camera.
Three preference levels
Constrains the path. Scored from trajectory quantities such as time per subtask, end-effector acceleration, carry height, straightness and clearance from a named object.
Constrains the key moment. Scored at the grasp or release pose: gripper position relative to the object, approach angle, how the object is set down.
Constrains the choice. Scored from the executed subtask plan: which object is picked first or where it is placed, checked against what the profile implies.
All three levels map to the same four-step label (0, 1/4, 3/4, 1), so results are comparable. User-profile preferences are the hardest because they change which object is the target, for example by adding a red twin of an item and phrasing the task so that one sentence covers both behaviors.
How it differs from the original LIBERO robot manipulation benchmark
The original LIBERO, released in 2023, targets lifelong robot learning: four task suites with 130 tasks and human-teleoperated demonstrations, used to study how knowledge transfers as a robot learns new tasks over time. LIBERO-PeRM reuses its simulator and layouts but changes the question.
Core question
- LIBERO (2023)
- Does knowledge carry over across new tasks?
- LIBERO-PeRM (2026)
- Does the robot do the same task differently per user?
Scale
- LIBERO (2023)
- 4 suites, 130 tasks
- LIBERO-PeRM (2026)
- 5 suites, 312 tasks
Demonstrations
- LIBERO (2023)
- Human teleoperation
- LIBERO-PeRM (2026)
- Procedurally generated, human-reviewed, paired with and without preference
Headline metric
- LIBERO (2023)
- Task success
- LIBERO-PeRM (2026)
- Task success (SR) and preference satisfaction (SA) reported separately
How the data is generated
- 1
Minimal layout edits
A vision-language model makes the smallest scene change needed for a preference to be acted on. Motion and skill preferences leave layout and task language untouched.
- 2
Paired plans and trajectories
The VLM writes a plan without the preference and a plan with it. A skill library, each skill built from one human demo plus a motion planner, turns both into trajectories. The project page says more than 72% of skills needed no per-task offset tuning.
- 3
Explicit metrics
Each preference gets its own scoring rule, so evaluation runs without a human judge.
The five suites and how to read SR and SA
- LIBERO-SinglePref (100 tasks): learning and executing one preference at a time.
- LIBERO-PrefScale (100 tasks): how learning scales with more demonstrations, tasks and layouts.
- LIBERO-PrefConflict (48 tasks): two preferences that cannot both hold, or a preference that argues against the task.
- LIBERO-PrefCompose (64 tasks): no preference, preference A, preference B and A + B on matched layouts.
- LIBERO-ComprePref: no new tasks; it rewrites prompts from the other suites, including implicit cues that suggest a preference without naming it.
SR is the share of episodes that reach the task goal. SA multiplies each successful episode by its satisfaction label and averages, so failed episodes score zero. A high SR with a low SA means the robot did the job but not your way.
Key results: task done, preference ignored
All figures below come from the project page and describe simulated evaluation.
π0.5, no preference
- Result
- SR 97.6%
- Takeaway
- Scene edits did not make tasks harder
π0.5, motion preference (zero-shot)
- Result
- SR 97.5% / SA 24.4%
- Takeaway
- Finishes the task, follows the preference about one time in four
π0.5, skill preference (zero-shot)
- Result
- SR 100% / SA 25.0%
- Takeaway
- Same pattern
π0.5, user profile (zero-shot)
- Result
- SR 19.1%
- Takeaway
- Changing the target breaks task success itself
LoRA fine-tuning, all preferences
- Result
- SR 85.0 / SA 82.5
- Takeaway
- Preferences are learnable from demonstrations
Same model, unseen layout
- Result
- SR 37.5 / SA 28.4
- Takeaway
- Generalization is still weak
Training trade-offs
Training on LIBERO first and preferences second dropped no-preference success to 52.3%. Mixing both in one run kept it at 91.0% and held up better on rewritten prompts (72.8 / 70.1 on ComprePref versus 44.0 / 42.6 for preference-only training). The cost showed up on motion preferences, where success fell from 90.0% to 66.9%, so mixing is not a free win. At a fixed budget of 2.25K demonstrations, spreading them across more layouts helped more than adding demonstrations per layout.
Composition, decomposition and conflict
- Trained on A and B separately, the policy combined A + B with 25.0% SR and SA.
- Asked to recover B alone after training on A + B and A, it reached 37.5% SR but 0.0% SA.
- With two conflicting preferences, SR / SA fell from 73.0 / 63.4 to 66.0 / 47.8, and neither preference clearly won.
- When the preference argued against the task, the robot followed the task 33.3% of the time, the preference 29.2%, and neither 37.5%.
Limits to keep in mind
It would be a stretch to read this as proof that robots cannot personalize. Everything runs in simulation, without real lighting, clutter or sensor noise. Only language-expressible, auto-scorable preferences are covered, so subjective requests like "make it look tidy" are out of scope. Fine-tuning results come from a single base model, π0.5. And the paper is a v1 preprint as of October 2026, so cite the version if you quote numbers, because they may change in later revisions.
Robotics papers often get amplified into bigger claims as they spread. If you want to see how a topic like this is being discussed, theddari's AI Telegram channel tracker and blog trends page show where the conversation is happening.

Checklist for reading personalized robotics research
- Look for task success and preference satisfaction reported separately; a high success rate alone says nothing about doing it your way.
- Check whether a number is zero-shot or after fine-tuning.
- Look for results on unseen layouts and tasks, not just in-domain scores.
- Confirm whether the setup is simulated or on real hardware, and note the paper version and date.
常见问题
Was LIBERO-PeRM tested on real robots?
How is personalization different from instruction following?
Why can SA never be higher than SR?
Which models were evaluated in LIBERO-PeRM?
来源与参考资料
相关文章
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.