How Do Legal AI Models Differ from General LLMs? What GLM-Legal and Knowledge Graph Research Show
Legal AI models differ from general LLMs in how they find, cite and verify sources. We compare GLM-Legal with two knowledge graph studies.
目录7 个章节
核心要点
- The main difference between a legal AI model and a general LLM is process: following the structure of legal sources, citing them verifiably and completing real deliverables.
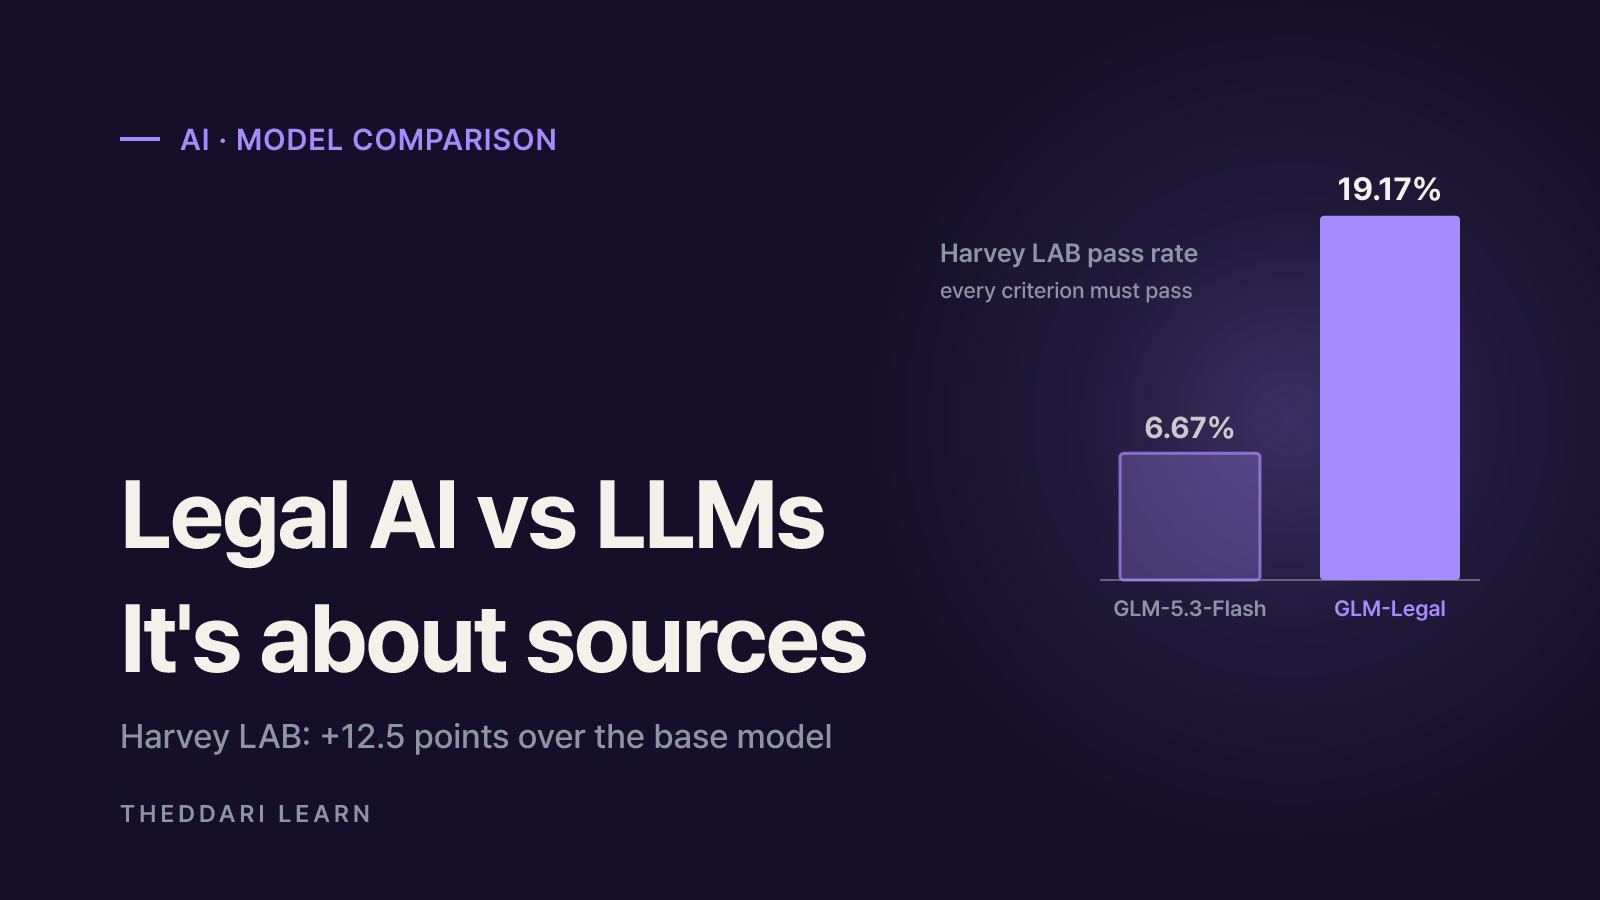
- Z.ai announced GLM-Legal on October 12, 2026. Built on GLM-5.3-Flash, it reports a 19.2% all-pass rate on Harvey LAB, 12.5 points above its base model.
- Its LegalBench and PLawBench results are self-reported. As of October 2026 access is an application-only beta with no published price or open weights.
- Two arXiv papers on German law show two routes for knowledge graphs: guiding retrieval to make citations checkable, or shaping pre-training to improve reasoning.
- No legal AI replaces a qualified lawyer; jurisdiction coverage and every cited provision still need checking against primary sources.
A legal AI model differs from a general large language model less in how much law it has memorized and more in how it works: it is trained and engineered to pull the issues out of source documents, retrieve and cite the right provision, and carry a task through to a deliverable a lawyer can actually review. As of October 13, 2026, two strands of evidence illustrate this well: Z.ai's GLM-Legal announcement and two new arXiv papers that use knowledge graphs for legal reasoning on German law. Most of the numbers below are either vendor-reported or limited to specific jurisdictions, and we flag which is which.
How a legal AI model differs from a general LLM
General-purpose LLMs learn language from broad web and book text. They can produce fluent answers to legal questions, but they often cannot show which provision supports an answer, and they can invent cases or clauses. In legal work, being right is not enough; the reasoning has to be verifiable by someone else. A conclusion that cannot be traced back to a statute, contract clause or opinion is hard to rely on in practice.
Legal specialization usually changes three layers. The model may receive additional training on legal corpora. Retrieval can be structured around how statutes and contracts are organized, often with retrieval-augmented generation (RAG) or a knowledge graph. And evaluation shifts from trivia-style questions to task-level legal work, sometimes reinforced with training signals from practitioners.
Training data
- General LLM
- Broad web and book text
- Legal AI approach (examples here)
- Extra legal corpus mid-training (GLM-Legal)
Finding sources
- General LLM
- Mostly internal memory
- Legal AI approach (examples here)
- Structure-driven knowledge graph retrieval (German Legal Code study)
Statutory structure
- General LLM
- Text treated as flat sequences
- Legal AI approach (examples here)
- Hierarchy built into pre-training objectives (German traffic law study)
Evaluation
- General LLM
- General Q&A and reasoning tests
- Legal AI approach (examples here)
- Task-level legal benchmarks such as Harvey LAB and LegalBench
Coverage
- General LLM
- Language in general
- Legal AI approach (examples here)
- Skewed to specific jurisdictions; verify per country
What GLM-Legal changes: training plus the harness
Z.ai introduced GLM-Legal on October 12, 2026. According to Unite.AI's report, it sits on the lightweight GLM-5.3-Flash foundation and adds three stages. Mid-training expands high-quality legal corpora so the model links facts, rules and conclusions. Post-training uses reinforcement learning across tens of thousands of realistic legal environments, where the model plans analysis and produces deliverables under constraints. A feedback stage then has legal professionals grade outputs on missed issues, sound citations, adherence to the brief and whether the work can be used without rework.
The notable piece is the harness, the runtime layer that manages task context, connects tools and routes execution feedback. Z.ai says the harness and the model were improved in lockstep. In other words, a legal AI product is closer to a model plus its working environment than to a standalone chatbot. The published demos reflect that: tracked-change edits to a software services contract, a contradiction map across 40 documents in a project dispute, and a pre-launch privacy checklist for Singapore, Malaysia and Indonesia.
Reading the benchmark numbers
Harvey LAB grades law-firm style tasks across 24 practice areas and counts a task as passed only if every rubric criterion passes. Z.ai reports a 19.2% all-pass rate, 12.5 percentage points above the base model. CellCog's check found the Vals AI leaderboard, updated the same day, listing GLM-Legal at 19.17% in sixth place, with GLM-5.3-Flash at 6.67%. The jump is real, but the strict grading also means the model missed at least one criterion on most tasks.
LegalBench and PLawBench need more caution. Z.ai describes parity with frontier closed models, yet per the company chart summarized by CellCog, GLM-Legal scored 86.2 on LegalBench against 88.6 and 87.1 for two comparison models, and 77.3 on PLawBench, a Chinese legal practice benchmark, against 77.7. Both are Z.ai's own runs, and no independent scores were available as of October 13, 2026.
As of October 2026, GLM-Legal is an application-only beta aimed at law firms, legal tech companies, in-house teams and practitioners. No GLM-Legal price has been published and no weight release has been confirmed. Integration with Z.ai's AutoClaw desktop agent is described as coming soon.
Two routes for knowledge graph legal reasoning
Two papers submitted to arXiv on October 9, 2026, both on German law, show different places to put a knowledge graph: at retrieval time, or inside training.
Retrieval: making citations checkable
The first paper (arXiv 2610.13695) starts from the premise that automation in reliability-critical fields such as law must be transparent and verifiable. RAG grounds generation in documents a human can inspect, but the authors note that naive retrieval degrades as the number and size of sources grow. They parse the German Legal Code by its structure into a knowledge graph and compare several graph-informed chunking and retrieval strategies by the accuracy of the retrieved citations. The 7-page paper was accepted at the RAGE-KG 2026 workshop at ISWC 2026.
Training: building legal structure into the weights
The second paper (arXiv 2610.13722) argues that legal language models trained only with masked language modeling treat statutes as flat token sequences. For German traffic law (StVO), it combines next sentence prediction, knowledge graph guided clustering and knowledge graph aware paragraph classification. Across nine Transformer encoders and 324 runs, it reports relative gains of 10.3% to 155.0% on synthetic StVO question answering, improvement on four of seven LexGLUE benchmarks, and zero-shot gains of 3.4% to 15.8% on Austrian driving regulations.
Keep the scope narrow: these are encoder models rather than large generative chatbots, the question answering set is synthetic, and relative improvements look large when baselines are low. The direction is still clear: use the explicit structure of legal sources to improve traceability and reasoning.
A practical checklist before you test a legal LLM
- 1
Confirm jurisdiction and language
GLM-Legal's public results center on Chinese legal practice and English-language documents; the papers cover German and Austrian law. Ask the vendor about the jurisdictions you work in.
- 2
Verify every citation
Look up each statute section, case or clause in the primary source and check that the version in force matches the date of your matter.
- 3
Run a small internal evaluation
Use anonymized documents and real tasks, and log missed issues and wrong citations. Your own failure patterns matter more than a leaderboard rank.
- 4
Review data handling terms
Confirm storage location, training use and confidentiality terms before sending anything through an API.
Early coverage of new models can be inaccurate; some aggregator headlines described GLM-Legal as open-weight, while the confirmed access route on launch day was an application form. The theddari AI Telegram trends and blog trends pages help you see which model releases people are discussing, so you can then go back to the announcement and independent leaderboards.

Limits and risks
Legal AI can speed up first drafts and surface contradictions in large document sets. Professional responsibility for the result still sits with the user and a qualified lawyer. Benchmarks measure fixed tasks and rubrics, not the facts, venue and latest amendments of a particular matter. A knowledge graph reflects the law as of when it was built, so update cycles matter in fast-changing areas.
常见问题
Is a legal AI model more accurate than ChatGPT or other general chatbots?
Which jurisdictions does GLM-Legal cover?
Does knowledge graph RAG eliminate hallucinations in legal research?
Can I upload client documents to a legal AI tool?
来源与参考资料
- 1Unite.AI: Z.ai Unveils GLM-Legal, an Agentic Model for Legal Workflows (Oct 12, 2026)(在新标签页中打开)www.unite.ai
- 2CellCog: GLM-Legal, Benchmarks Checked (Oct 12, 2026)(在新标签页中打开)cellcog.ai
- 3arXiv 2610.13695: Verifiable Retrieval for Legal Reasoning through Structure-driven Knowledge Graph(在新标签页中打开)arxiv.org
- 4arXiv 2610.13722: Enhancing Legal Reasoning in Pre-trained Language Models via Knowledge Graph-Guided Multi-Task Pre-training(在新标签页中打开)arxiv.org
相关文章
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.