What Is EmbeddingGemma 2? How to Choose an Embedding Model for RAG
EmbeddingGemma 2 explained: 740M parameters, 768-dim vectors, 8K context and 100+ languages, plus a practical checklist for choosing an embedding model for RAG.
目录8 个章节
核心要点
- EmbeddingGemma 2 is an open, Apache 2.0 licensed multimodal embedding model released by Google DeepMind on October 6, 2026, with 740M total parameters.
- For text-only RAG you can skip the vision and audio encoders and run a 270M-parameter footprint that outputs 768-dimensional vectors.
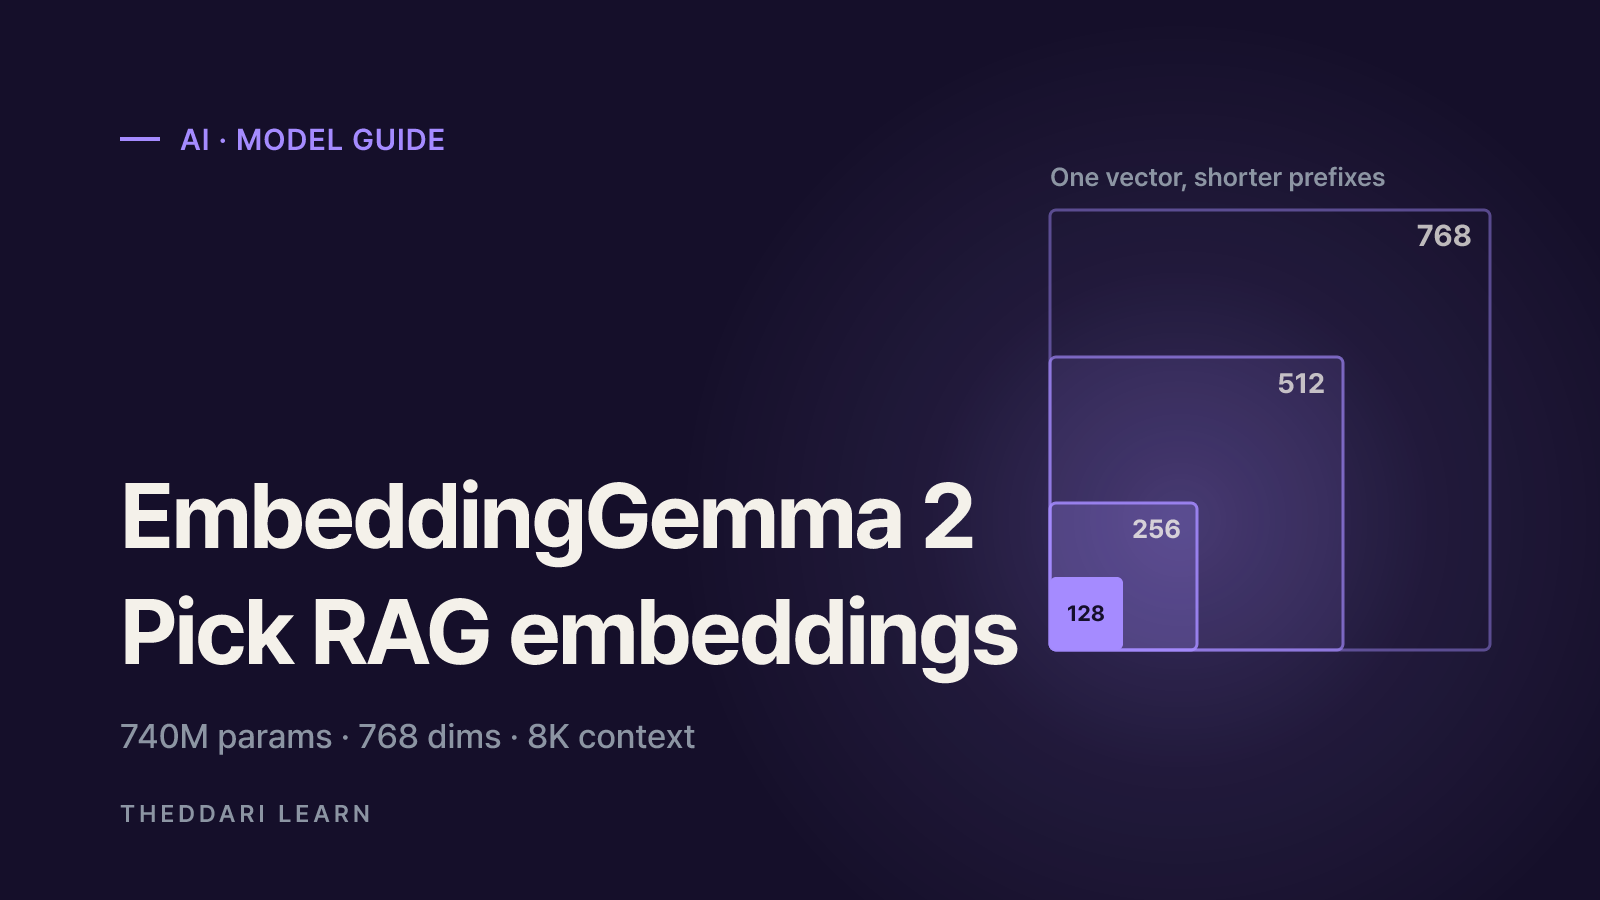
- Matryoshka training lets you truncate vectors to 512, 256 or 128 dimensions; the model card shows small text-quality losses down to 256.
- Multilingual MTEB is roughly flat versus the first version, while code retrieval improved from 68.76 to 78.68.
- Leaderboard averages are a starting point. The deciding test is recall on your own queries and documents.
EmbeddingGemma 2 is an open embedding model from Google DeepMind, released on October 6, 2026, that maps text, code, images, video and audio into a single 768-dimensional vector space. If you are choosing an embedding model for RAG, it is a strong candidate for local and on-device retrieval, but the right choice still depends on your languages, document lengths, storage budget and where the model will run. This guide summarizes the official model card and launch post as of October 2026, then walks through a selection checklist you can apply to any model.
Why the embedding model matters in a RAG pipeline
In retrieval-augmented generation, the embedding model turns each document chunk and each user query into a vector. A vector database then returns the chunks whose vectors sit closest to the query. The language model only sees what retrieval hands it, so if the right passage never reaches the top results, a larger generator will not fix the answer. When a RAG system gives poor answers, checking whether the correct chunk appears in the top five or ten results is usually the fastest diagnosis.
Two operational facts follow. First, queries and documents must be embedded with the same model, the same dimension and the same preprocessing rules. Second, switching models means re-embedding the whole corpus, because vectors from different models are not interchangeable. That makes the embedding choice harder to reverse than a prompt change, and worth testing carefully.
EmbeddingGemma 2 at a glance
Release and license
- Official figure
- October 6, 2026; Apache 2.0
- What it means for RAG
- Commercial use allowed; Gemma Prohibited Use Policy also applies
Total parameters
- Official figure
- 740M
- What it means for RAG
- Text 270M + vision 170M + audio 300M
Output
- Official figure
- 768 dimensions
- What it means for RAG
- Truncatable to 512, 256 or 128 via MRL
Context window
- Official figure
- 8,192 tokens
- What it means for RAG
- Four times the first EmbeddingGemma
Languages
- Official figure
- 100+
- What it means for RAG
- Quality is not equal across languages
Inputs
- Official figure
- Text (incl. code), images, video, audio
- What it means for RAG
- Mixed inputs can produce one embedding
Training data cutoff
- Official figure
- January 2025
- What it means for RAG
- Newer terms may be weakly represented
On benchmarks, the model card reports a multilingual MTEB (v2) mean of 61.36 against 61.15 for the first version, and an English MTEB (v2) mean of 68.46. The headline gain is code: MTEB code rose from 68.76 to 78.68, which Google positions as useful for local codebase indexing and coding-agent retrieval. Image, video and audio scores are also published, but there is no first-generation baseline for those because the original model was text-only.
A small footprint for text-only retrieval
The vision and audio encoders are separate modules. According to the model card, loading text only gives an effective size of 270M parameters, text plus images 440M, and text plus audio 570M. Google says that with quantization the model needs roughly 191 MB of active RAM for text-only weights and about 567 MB for the full multimodal model on a Pixel 11 Pro. For desktop experiments, the community Unsloth GGUF build offers files from 176 MB (4-bit) to 310 MB (8-bit) and 558 MB (BF16) that run in llama.cpp or Ollama.
Prefixes and precision are not optional details
The model was trained with short task prefixes. For search, format queries as task: search result | query: {query} and documents as title: {title} | text: {content}, using title: none when there is no title. Skipping prefixes still works but reduces precision. Run inference in bfloat16 or float32. The model card warns that float16 can return NaN values or silently degraded embeddings without raising an error.
How to choose an embedding model for RAG
Use the same six questions for every candidate, whether it is EmbeddingGemma 2, a hosted API or another open model. No single model wins every scenario.
Languages and cross-lingual queries
A multilingual label means a language is supported, not that it performs best. EmbeddingGemma 2 covers more than 100 languages, but its own card notes that performance varies by language and it does not publish per-language retrieval scores. If your users search in one language over documents in another, or your corpus is full of domain jargon and abbreviations, include those cases in your test set.
Dimensions and storage cost
A 768-dimensional float32 vector takes 3,072 bytes, so one million chunks need about 3 GB before index overhead. Matryoshka Representation Learning lets you keep only the leading dimensions. The model card's truncation results:
768
- Compression
- 1:1
- Multilingual MTEB
- 61.36
- MMEB (multimodal)
- 59.01
- float32 size per vector
- 3,072 bytes
512
- Compression
- 1:1.5
- Multilingual MTEB
- 61.17
- MMEB (multimodal)
- 58.38
- float32 size per vector
- 2,048 bytes
256
- Compression
- 1:3
- Multilingual MTEB
- 60.41
- MMEB (multimodal)
- 56.24
- float32 size per vector
- 1,024 bytes
128
- Compression
- 1:6
- Multilingual MTEB
- 57.89
- MMEB (multimodal)
- 45.65
- float32 size per vector
- 512 bytes
Text retrieval holds up well to 256 dimensions; at 128, multimodal quality drops sharply. Always L2-normalize truncated vectors, otherwise ranking quality degrades without any error message.
Context length versus chunk size
An 8,192-token window lets you embed long passages, but a long chunk can blend several topics into one vector and blur its match to a specific question. Treat the window as a ceiling and tune chunk size against your document structure.
Local embedding model or hosted API
Hosted embedding APIs reduce operations work but send your text to a third party and bill per call. A local embedding model keeps data on your hardware and can work offline, at the cost of managing throughput, hardware and upgrades yourself. EmbeddingGemma 2 was designed for on-device use, which makes it relevant for privacy-sensitive corpora.
Modalities, domain and licensing
If you need to search images, scanned pages or audio with text queries, a shared multimodal space is useful; if not, those encoders are memory you can skip. For code search, check code-specific benchmarks. Finally, confirm the license and usage policy, pin the model version and document your prefix and dimension settings.
Reading benchmarks without being misled
The original MTEB paper covered 8 task types, 58 datasets and 112 languages, and found that no single embedding method dominated across all tasks. Compare scores only within the same benchmark version, look at retrieval tasks rather than the overall mean, check the metric (NDCG@10, Hit@1 and MRR@10 measure different things), and note whether results come from the vendor or an independent run. Quantized builds may score differently from the full-precision checkpoint.
A practical evaluation workflow
- 1
Build a small labeled set
Collect realistic user questions and mark the chunk that answers each one. Even a few dozen pairs reveal meaningful differences between candidates.
- 2
Fix the pipeline
Keep chunking, normalization, prefixes, dimension and top-k identical for every model, and use EmbeddingGemma 2's recommended query and document prefixes.
- 3
Measure retrieval first
Record recall@5, recall@10 or NDCG before judging generated answers.
- 4
Test dimensions and quantization
Compare 768, 512 and 256 dimensions and any GGUF builds you plan to deploy, alongside storage and latency.
- 5
Log the decision
Save the model version, settings, scores and date so you can rerun the same test when a new model appears.
Limitations to plan for
- Uneven language quality: per-language results are not published, so verify your languages directly.
- No safety alignment: the card says the model has no post-training alignment or output moderation; retrieval filtering is the deployer's job.
- Knowledge cutoff: training data runs to January 2025.
- Precision traps: avoid float16, re-normalize truncated vectors and keep dimensions consistent.
- Third-party builds: community conversions differ in quantization and maintainer, so check quality and license notes.
New embedding releases attract fast community discussion. The theddari AI Telegram trends and blog trends pages can help you see which models and tools developers are talking about, so you can widen your shortlist. Popularity is not a substitute for testing on your own data.

常见问题
Is EmbeddingGemma 2 free for commercial use?
Can I run EmbeddingGemma 2 locally with Ollama or llama.cpp?
How does EmbeddingGemma 2 differ from the first EmbeddingGemma?
Which dimension should I use for a vector database?
来源与参考资料
相关文章
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.