What Is Mistral Voxtral 3? Speech Model Features and Checks
Mistral's Voxtral 3, announced October 20, 2026: transcription and TTS models, API pricing, language support, open-weight status, and checks before you build.
目次7セクション
要点
- Voxtral 3, announced by Mistral AI on October 20, 2026, bundles three speech-to-text models, one text-to-speech model and a LiveKit-based voice agent SDK.
- Batch transcription covers 50 languages; the realtime model is documented at 45 languages and dialects. Korean, Japanese and Chinese appear in the benchmark sets.
- List prices: $0.0035/min (Mini Transcribe 3), $0.004/min (Small Transcribe 3), $0.008/min (Realtime 3) and $13 per 1M characters (Speech 3).
- As of October 21, 2026, no Voxtral 3 weights are listed in Mistral's Hugging Face Voxtral collection; on-prem deployment goes through Mistral's sales team.
- For summaries, Q&A or translation of audio, Mistral's docs point to voxtral-small-latest (Voxtral 2) at launch, not to a Voxtral 3 model.
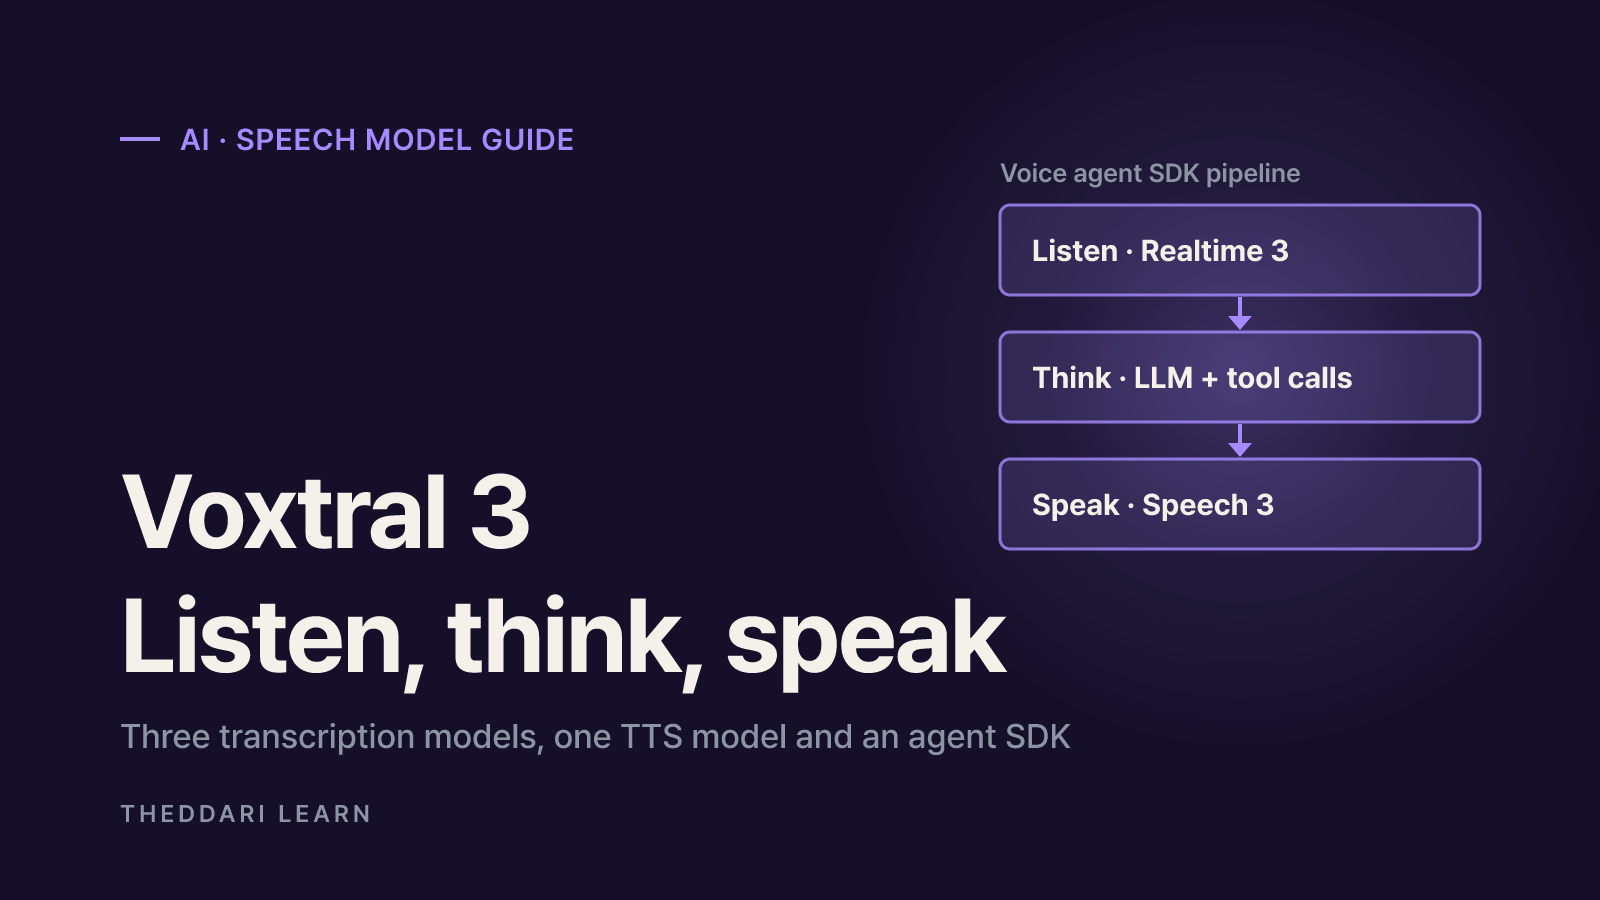
Voxtral 3 is a family of speech AI models that Mistral AI announced on October 20, 2026. It includes three speech-to-text (STT) models for recorded files and live audio, one text-to-speech (TTS) model, and a voice agent SDK that chains them with a language model (Mistral announcement). This guide reflects Mistral's announcement, documentation and Hugging Face pages as checked on October 21, 2026.
The short answer: Voxtral 3 is an API-first release focused on transcription and speech generation. Despite Mistral's history of open-weight audio models, no Voxtral 3 weights were downloadable when we checked, and the docs still route "audio understanding" tasks such as summaries and Q&A to the older Voxtral 2 chat model. Below is what's in the family, what changed from earlier Voxtral releases, what it costs, and what to test before you put it in production.
Voxtral 3 lineup: three transcription models, TTS and an agent SDK
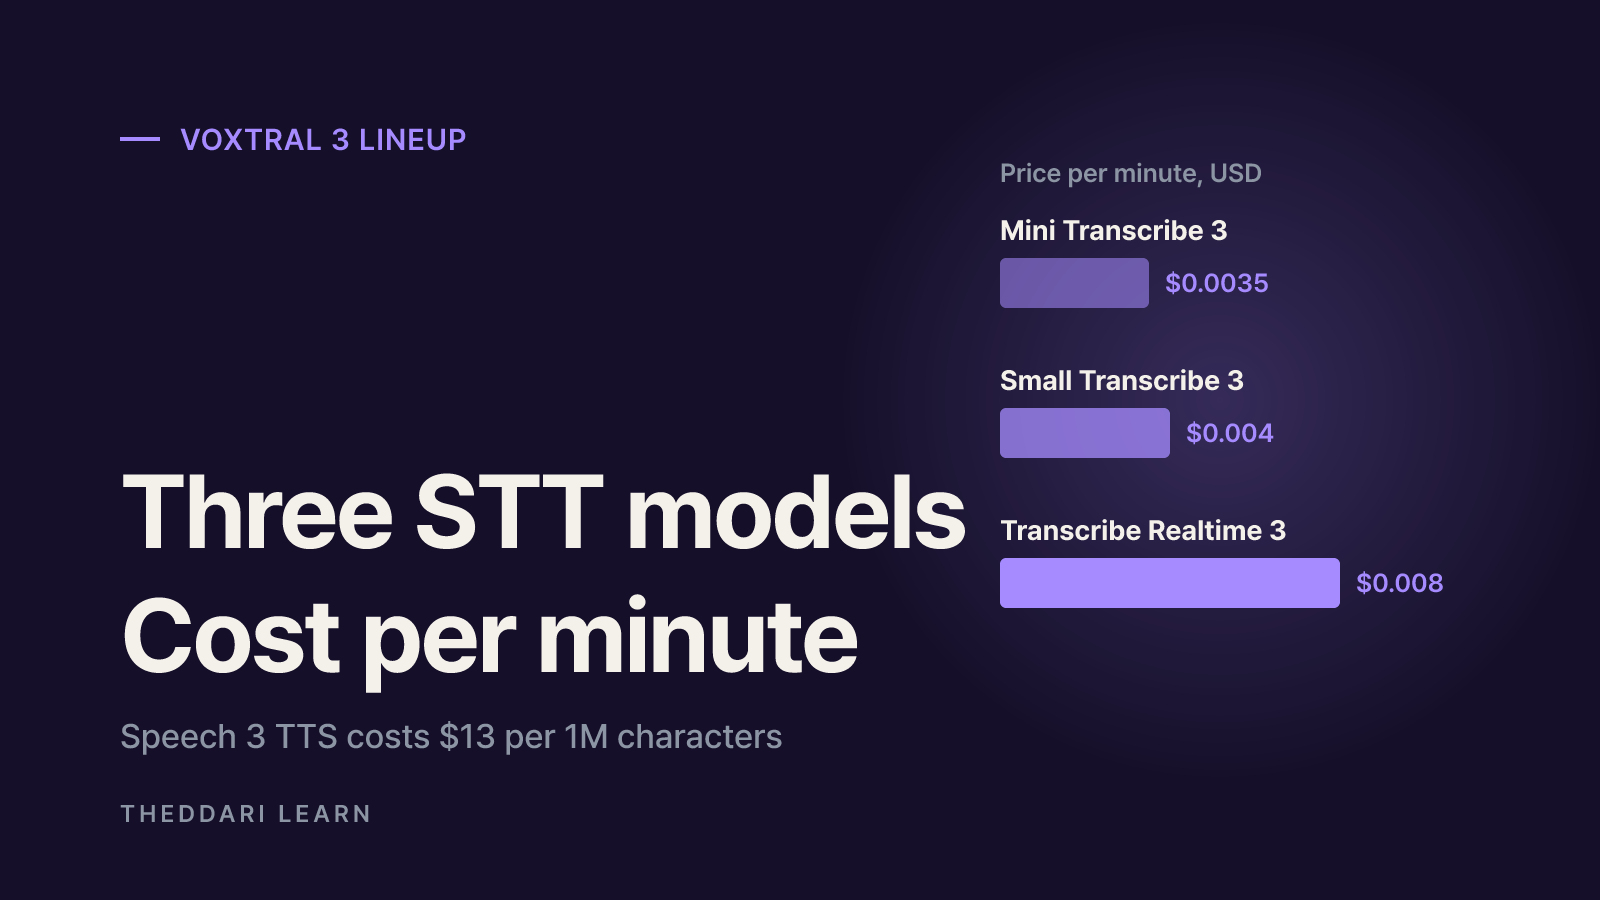
Mistral's Speech to Text overview splits the models by job: one realtime model, two batch models, plus a separate speech model.
Voxtral Mini Transcribe 3
- Use it for
- Recorded files; the default starting point (4B parameters)
- Languages (docs)
- 50 languages
- List price (USD)
- $0.0035 per minute
Voxtral Small Transcribe 3
- Use it for
- Recorded files when Mini still makes errors
- Languages (docs)
- 50 languages
- List price (USD)
- $0.004 per minute
Voxtral Mini Transcribe Realtime 3
- Use it for
- Live captions, turn detection, voice agents
- Languages (docs)
- 45 languages and dialects
- List price (USD)
- $0.008 per minute
Voxtral Speech 3 (Mini TTS 3)
- Use it for
- Speech generation, batch and realtime on one API
- Languages (docs)
- 35+ languages, 50+ dialects
- List price (USD)
- $13 per 1M characters
The voice agent API is priced separately at $0.04 per minute with Mistral Small 4 doing the reasoning, or $0.08 per minute with any other reasoning model. Mistral says the API is served from European, US and global endpoints.
What the transcription models do
- Speaker diarization labels who spoke when. You can pass up to 8 reference clips of 3 to 15 seconds each to put names on speakers.
- Context biasing lets you supply product names, jargon or speaker names so the model is more likely to spell them correctly, without fine-tuning.
- End-of-turn detection (realtime only) uses both acoustic and semantic cues to decide when a caller has finished, so an agent can reply without cutting people off.
- Latency control on the realtime model accepts a streaming delay from 80 to 1200 ms, or 2400 ms. Lower delay means faster text and, per Mistral's own chart, a higher error rate.
Speech generation and the voice agent SDK
Voxtral Speech 3 adapts emotion, pacing and emphasis to context, accepts phoneme hints for unusual names, and offers a Pro Voice adaptation that Mistral says can reproduce a speaker's style from about 30 minutes of audio. The voice agent SDK is built on LiveKit and runs listen, reason (with tool calls) and speak as one streaming pipeline; Mistral claims each turn completes in under one second. Because each stage is a separate model, you can swap the LLM or the voice without rewriting the agent.
How Voxtral 3 differs from earlier Voxtral releases
The original Voxtral Mini 3B and Small 24B (July 2025) were audio chat models released under Apache 2.0. In February 2026 Mistral added Voxtral-Mini-4B-Realtime-2602, a 13-language streaming transcriber, also Apache 2.0, and in March 2026 Voxtral-4B-TTS-2603, which inherits a non-commercial CC BY-NC 4.0 license from its reference voices (Hugging Face Voxtral collection).
Main jobs
- Earlier open Voxtral models
- Audio chat, realtime STT, TTS
- Voxtral 3 (Oct 2026)
- Batch and realtime STT, TTS, voice agents
STT languages
- Earlier open Voxtral models
- 13 (realtime model)
- Voxtral 3 (Oct 2026)
- 50 batch; 45 languages and dialects realtime
Weights
- Earlier open Voxtral models
- On Hugging Face, license varies by model
- Voxtral 3 (Oct 2026)
- None listed as of Oct 21, 2026; self-hosting via sales
Timestamps
- Earlier open Voxtral models
- Varies by model
- Voxtral 3 (Oct 2026)
- Segment-level only in batch; no word timestamps
Status
- Earlier open Voxtral models
- Released checkpoints
- Voxtral 3 (Oct 2026)
- Model page labeled Public Preview
Audio understanding is not a Voxtral 3 feature yet. Mistral's docs say that for summaries, translation or other answers about a recording you should use audio in chat completions with voxtral-small-latest (Voxtral 2) at launch. Decide whether you need a transcript or an answer before choosing a model.
Pricing, deployment and licensing: what to verify
You can try Voxtral 3 today in Mistral Studio playgrounds or through the API. The announcement leans on sovereign deployment, but the practical instruction is to contact Mistral to run the full stack on-premises or in a private cloud. When we checked Mistral's Hugging Face organization and Voxtral collection on October 21, 2026, there was no Voxtral 3 checkpoint. For now it is more accurate to think of Voxtral 3 as a commercial API model than as an open-weight download.
- Check the model page status (Public Preview) and its Legal link. Preview models can change names, behavior or prices.
- Expect small documentation mismatches. The realtime model's language count reads 35+ in the announcement text, 40+ on its card and 45 languages and dialects on the languages page. The batch model page shows a 32k context, while the limits page lists 65,536 tokens shared by audio and context bias. Confirm against current docs before you commit.
- Review the data processing addendum and your endpoint region if recordings contain personal data. EU, UK and US privacy obligations differ, and consent for call recording depends on where callers are.
- If weights ship later, read the license field on the model card; Mistral's previous open TTS model was non-commercial.
Model launches move fast. Watching reaction on theddari's AI Telegram trends and hands-on write-ups in blog trends helps you see whether real-world results match the launch charts.

Checklist before using Voxtral 3 for transcription
- 1
Pick the job first
Start batch files on Mini Transcribe 3 and move to Small Transcribe 3 only if context biasing does not fix recurring errors. Use Realtime 3 for live text, and the Voxtral 2 audio chat model for summaries or Q&A.
- 2
Measure on your own audio
Published numbers are averages over Mistral-selected benchmarks. Transcribe 10 to 20 of your own meetings or calls by hand and compute word error rate (or character error rate for Korean, Japanese and Chinese). Noise, accents and crosstalk widen the gap.
- 3
Decide on language pinning
Batch requests accept a two-letter ISO 639-1 code such as en or fr; anything else returns a 422 error. For code-switched calls, test both auto-detection and a pinned language.
- 4
Check feature combinations
A realtime session cannot enable diarization and turn detection together; it returns an error, so run them in separate sessions. Word timestamps are not available.
- 5
Translate pricing into a monthly figure
Two hours of meetings a day on Mini Transcribe 3 is 120 minutes × $0.0035 = $0.42 per day. Realtime costs more than twice as much per minute, so always-on recording is often cheaper as batch.
Risks and limits: benchmarks, voice cloning, privacy
On Mistral's charts, Voxtral Small Transcribe 3 posts a 4.1% average error rate across 45 FLEURS languages with the language specified, versus 16.0% for Whisper large-v3 under the same setup. It scores 18.4% cpWER on diarization benchmarks and 94.6% keyphrase recall with context biasing. These are vendor-run results with vendor-chosen baselines; wait for independent evaluations before treating them as settled.
- Voice cloning misuse: Pro Voice can mimic a speaker from about 30 minutes of audio, which creates impersonation and fraud risk. Get written consent from the voice owner and define allowed uses.
- Sensitive recordings: for healthcare or financial calls, confirm retention settings and processing region before sending audio to an API. Fully in-house processing currently needs a separate agreement.
- Agents that take actions: a misheard number or name can turn into a wrong booking or payment. Add a read-back confirmation step before any tool call that changes data.
- Preview churn: Public Preview models can be renamed, repriced or replaced. Build so that model IDs are configuration, not code.
Bottom line: Voxtral 3 packages multilingual transcription, diarization, context biasing and realtime turn detection at low per-minute prices, behind an API. Test it on your own recordings, decide separately whether you need audio understanding, and if you require open weights, compare it with Mistral's earlier Apache 2.0 Voxtral checkpoints or other open speech models.
よくある質問
Is Voxtral 3 open source or open weights?
Is Voxtral 3 better than Whisper?
Does Voxtral 3 return word-level timestamps?
Can I use Voxtral 3 to summarize or ask questions about a recording?
出典・参考資料
- 1Mistral AI — Voxtral 3 announcement (2026-10-20)(新しいタブで開きます)mistral.ai
- 2Mistral Docs — Voxtral Mini Transcribe 3 model page(新しいタブで開きます)docs.mistral.ai
- 3Mistral Docs — Speech to Text overview(新しいタブで開きます)docs.mistral.ai
- 4Mistral Docs — Audio languages(新しいタブで開きます)docs.mistral.ai
- 5Mistral Docs — Audio limits(新しいタブで開きます)docs.mistral.ai
- 6Hugging Face — mistralai Voxtral collection(新しいタブで開きます)huggingface.co
関連記事
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.