What Is Meta's Muse Spark Open? Specs, License and What You Need to Run It
Meta's Muse Spark Open is an 816B open-weight model with 42B active parameters and 1M context. What the Muse Model License allows and what it takes to run.
目次8セクション
要点
- Muse Spark Open is a coding and agent model from Meta Superintelligence Labs, released October 15, 2026: 816B total parameters, 42B active per token, a 1M-token context window.
- It takes text, image, video and audio input and outputs text. Weights are on Hugging Face and three cloud catalogs; seven providers serve it by API.
- It is open weights, not OSI open source: the license is free to use and modify but requires a 'Built with Muse Spark Open' notice and a deal for large MaaS providers.
- Self-hosting is heavy: Meta's model card lists 700GB+ of GPU memory for the NVFP4 build and 2TB for BF16.
- Benchmarks are Meta's own, and the model trails some rivals on several tests. Meta's top model, Muse Wonder, remains closed.
Muse Spark Open is an open-weight, natively multimodal model that Meta released on October 15, 2026 through its Meta AI Research blog. It is a mixture-of-experts (MoE) model with 816 billion total parameters, of which about 42 billion are active for each token, and it supports a context window of up to 1 million tokens. Meta built it for coding and agentic work. The weights are free to download, but 'open' here means open weights under a custom license with real conditions, not a permissive open-source license. This guide, current as of October 2026, covers what was released, what the license allows, how to read the benchmarks and what it takes to run.
Muse Spark Open at a glance
Meta calls it 'the most capable US open-weight model to date.' That is Meta's own claim, based on Meta's own evaluations. The model card credits Meta Superintelligence Labs as the authors.
| Spec | What Meta published |
|---|---|
| Release date | October 15, 2026 |
| Parameters | 816B total / 42B active per token |
| Architecture | MoE transformer plus a 1.8B Perception Encoder |
| Experts | 256, with 8 activated per token |
| Context window | Up to 1M tokens at inference |
| Input / output | Text, image, video, audio / text |
| Languages | Trained on data from 100+ languages |
| Weight formats | BF16 (about 1.6TB), NVFP4 (about 530GB) |
| License | Muse Model License |
According to the Hugging Face model card, target uses include long multi-step reasoning, end-to-end agent tasks with sequential tool calls and failure recovery, coding agents, multimodal reasoning over screenshots, charts, documents, audio and video, synthetic data generation and LLM-as-a-judge evaluation. A reasoning_effort setting accepts low, medium, high or xhigh, and defaults to xhigh.
Why '42B active' still needs a lot of memory
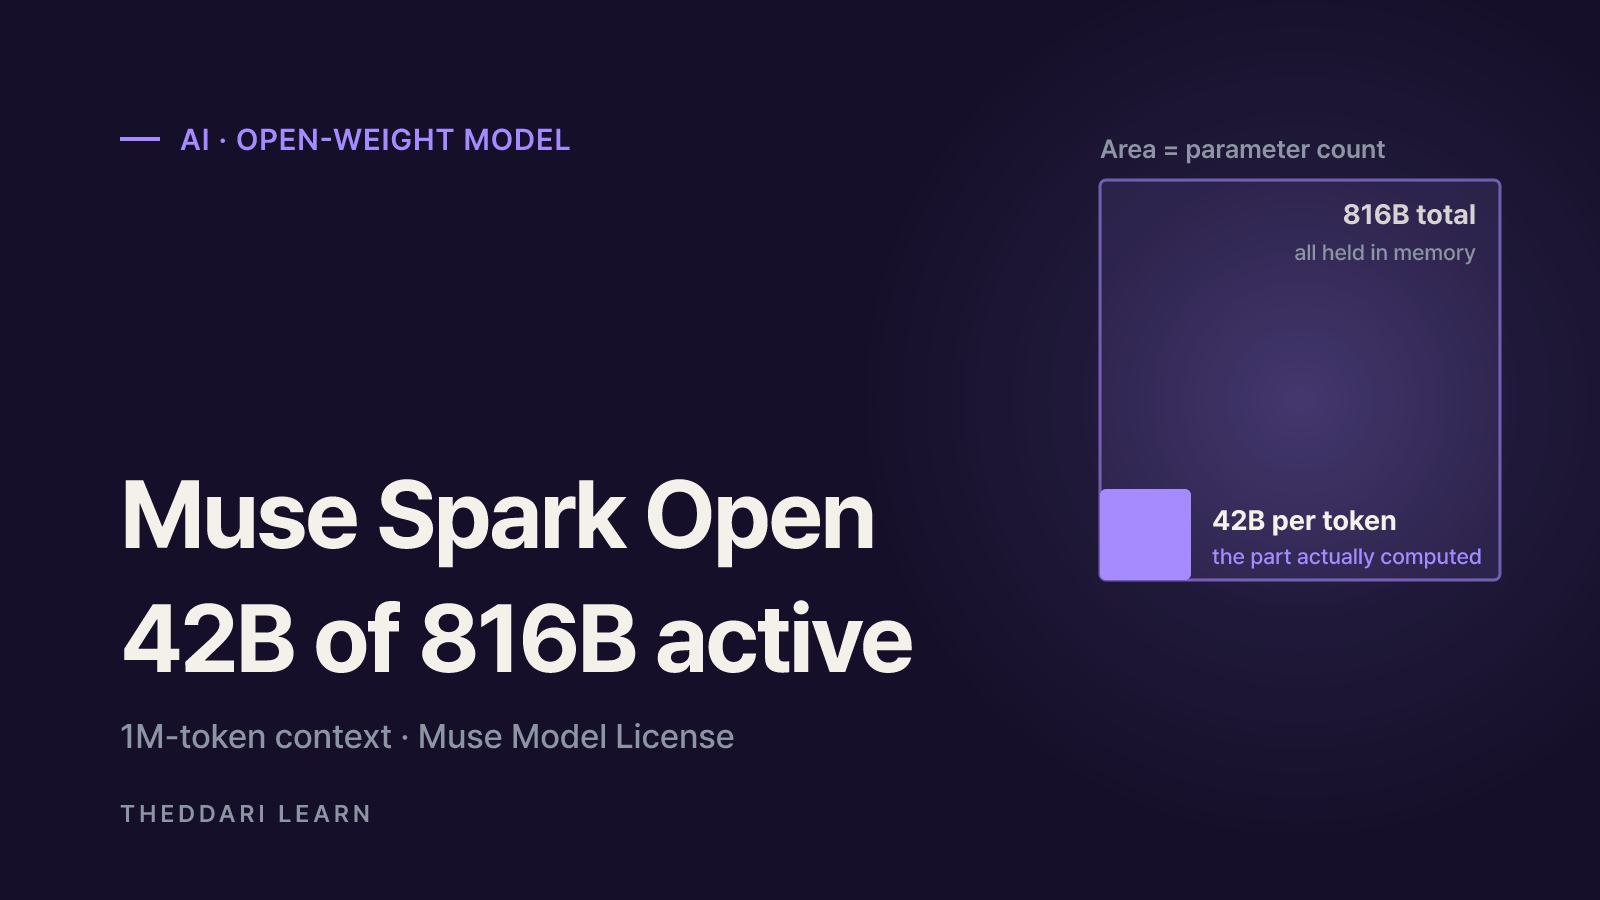
In an MoE model, a router picks a few experts for each token, so compute per token is closer to a 42B model. But all 816B parameters must sit in memory because any expert might be chosen next. That is why Meta's showcase hardware is about memory capacity and bandwidth rather than raw GPU count.
What the Muse Model License allows
Meta released the weights, code, configuration files and documentation. It did not release training data; the model card only says the data mixes public web crawls, third-party sources, data from Meta's products and synthetic data. The license text on Hugging Face grants free rights to use, copy, modify, fine-tune, distill, merge, publish, distribute, sublicense and sell, subject to these conditions:
- Include the copyright notice, the license and the Usage Policy in all copies and derivatives.
- Prominently display 'Built with Muse Spark Open' in the product UI, documentation, website or settings menu. 'Derivatives' includes any model trained or distilled using the software or its outputs.
- If you offer AI models to third parties as a service and you plus your affiliates exceed US$20 million in gross revenue over any 12 consecutive months, notify Meta and sign a separate written agreement before offering Muse Spark Open in that business.
- That revenue clause does not apply to internal use, research, non-MaaS commercial activity, or using the model to power features of your own product.
- Meta claims no ownership of outputs, and the software is provided as-is with no warranty.
The attached Usage Policy says the model is not intended for people under 18 and bans uses such as the unlicensed practice of financial, legal or medical professions, malware creation and circumventing safety measures. A fintech app built on it still needs whatever licensing your jurisdiction requires.
Hugging Face access is gated. You must submit your full legal name, date of birth and full organization name, and the form cannot be edited after submission.
How to access it: API, cloud catalog or self-hosting
Meta's developer post lists launch-day access through Baseten, Fireworks AI, Groq (limited preview), Modal, Nebius, OpenRouter and Together AI. This is the fastest way to evaluate quality before buying hardware. Check each provider for pricing and regional availability.
Amazon SageMaker AI, Google Cloud Model Garden and Microsoft Foundry Models let teams deploy into their own private instances, useful when data cannot leave your cloud account.
Supported runtimes include SGLang, vLLM, TensorRT-LLM, Hugging Face Transformers, Apple MLX, llama.cpp and Unsloth. Fine-tuning is supported through PyTorch TorchTitan, Hugging Face TRL, NVIDIA NeMo AutoModel and managed APIs from Fireworks AI and Together AI.
Hardware requirements
BF16 full precision
- Published requirement
- About 2TB of GPU memory
- Source
- Model card
NVFP4 (Meta)
- Published requirement
- 700GB+ GPU memory; four Blackwell Ultra GPUs or eight H200s
- Source
- Model card, developer post
Mac Studio with MLX
- Published requirement
- Two M5 Ultra with 512GB each, or four with 256GB (1TB total)
- Source
- Developer post
Unsloth GGUF (~2-bit)
- Published requirement
- About 300GB combined RAM and VRAM
- Source
- Developer post
Meta says two Mac Studios linked over Thunderbolt 5 split every layer with MLX tensor parallelism, so they behave like one machine with a terabyte of unified memory. The model card also warns that quantized inference may differ from full precision in edge cases, so do not treat a 2-bit build as equivalent to the original.
How to read the benchmarks and safety claims
All scores in the model card come from Meta's own runs at xhigh reasoning effort. Muse Spark Open led its comparison set on agentic tests such as JobBench (61.8) and MCP-Atlas (89.2). It did not lead everywhere: its Artificial Analysis Intelligence Index score of 39 sits below GLM 5.3 (45) and Kimi K3 (44), and on Terminal-Bench 2.1 it scored 76.4 against Kimi K3's 85.0. Pick the benchmarks that match your workload instead of relying on the headline claim.
- Safety: Meta added extra safety post-training for the open release and reports a 99.2% refusal rate on its internal cyber jailbreak benchmark.
- Caveat: these results apply to the released checkpoint under tested conditions. The model card says fine-tuning or other modifications can degrade safety.
- Verification: Meta said a full evaluation report would be 'available soon' without giving a date. Until independent results appear, treat the numbers as vendor-reported.
Where it fits in Meta's open model strategy
TNW reported that Meta launched its closed frontier model, Muse Wonder, earlier the same week and described Muse Spark Open as less capable. Alexandr Wang, Meta's chief AI officer, said that 'because of both safety and capabilities, we will generally not open-source our most powerful models.' TNW also noted this is the second open release in the Muse line, after the 30B Muse Glimmer under Apache 2.0 in August. The pattern is clear: Meta keeps its top model closed and opens the tier below it.
Model launches like this move fast. You can follow how AI channels are reacting on theddari's AI Telegram trends and track longer write-ups on the blog trends dashboard.

Checklist before you build on Muse Spark Open
- 1
Classify your use
Decide whether you are selling model access (Model-as-a-Service) or powering your own product's features. The US$20 million threshold counts affiliates and any 12 consecutive months.
- 2
Plan the attribution
Choose where 'Built with Muse Spark Open' appears, and ship the license and Usage Policy with any derivative model you distribute.
- 3
Test through an API first
Run your real prompts, languages and documents through a hosted provider to measure quality, latency and cost before committing to hardware.
- 4
Add guardrails
Meta recommends system-level safeguards and human confirmation before irreversible agent actions such as payments or deletions.
- 5
Check privacy and local law
The Usage Policy bans processing or inferring sensitive personal data without legal right. Map that against GDPR, CCPA or whichever regime applies to you.
In short, Muse Spark Open gives developers downloadable, modifiable weights for a large agentic model, but it comes with license conditions and hardware needs measured in hundreds of gigabytes. Read the model card and license text directly, test small through an API, then decide how far to adopt it.
よくある質問
Is Muse Spark Open open source?
Can I use Muse Spark Open commercially?
Can I run Muse Spark Open on a single GPU or a gaming PC?
How is Muse Spark Open different from Muse Wonder?
Is Muse Spark Open available in the EU?
出典・参考資料
- 1Meta AI Research — Introducing Muse Spark Open(新しいタブで開きます)research.meta.ai
- 2Hugging Face — Muse-Spark-Open-816B-A42B model card and Muse Model License(新しいタブで開きます)huggingface.co
- 3Meta AI Developers — Build with Muse Spark Open(新しいタブで開きます)dev.meta.ai
- 4TNW — Meta opens a weaker AI model while keeping the frontier closed(新しいタブで開きます)thenextweb.com
関連記事
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.