What Is the Intel D270 AI Accelerator? What 480GB of LPDDR5X Means for Inference
The Intel D270 puts up to 480GB of LPDDR5X and 1.5TB/s in a 350W PCIe card. What a memory-first design means for LLM inference, and what Intel hasn't said yet.
目次8セクション
要点
- The Intel D270 is a data center inference GPU announced on October 12, 2026: up to 480GB LPDDR5X, 1.5TB/s memory bandwidth, 1.3 PFLOPS FP8, 350W, air-cooled PCIe 5.0.
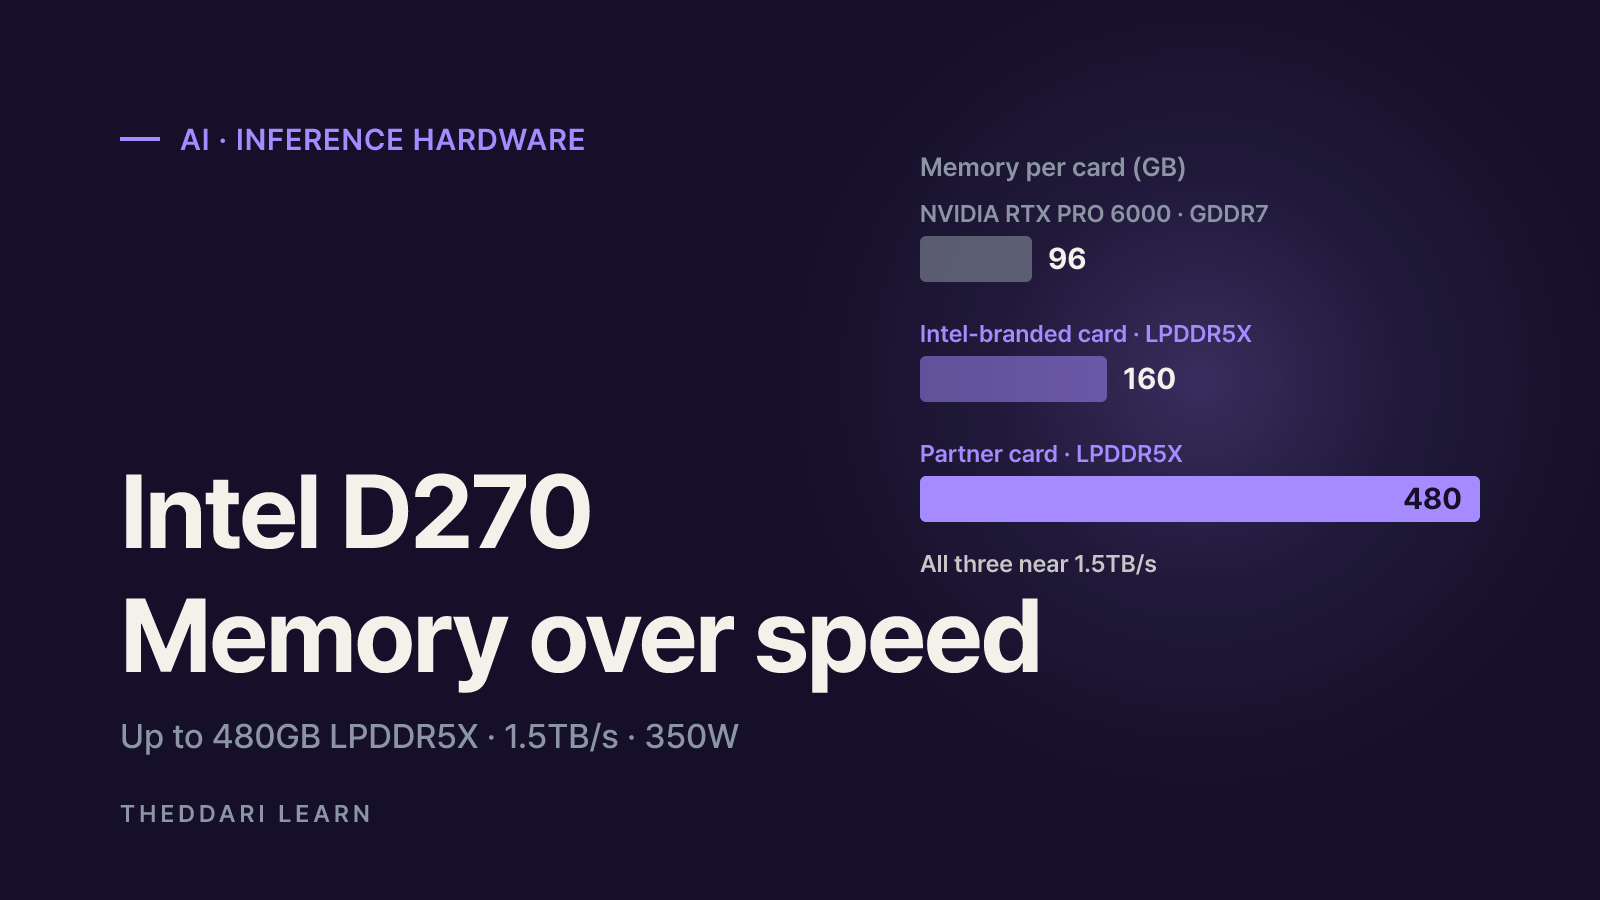
- The 480GB figure applies to partner (ODM) cards. Intel's own branded card ships with 160GB.
- As of October 13, 2026, Intel is sampling to customers but has announced no price and no general availability date.
- Single-user token speed is bandwidth-bound, so expect it near similar cards like the RTX PRO 6000. The payoff is capacity: more sessions, longer contexts, bigger models per card.
The Intel D270 is the first card in Intel's GPU D-series, the data center inference accelerator previously code-named Crescent Island. Intel detailed it at the Open Compute Project (OCP) Global Summit on October 12, 2026. The headline is memory: instead of expensive HBM, the D270 uses LPDDR5X, the same family of memory found in laptops and phones, and partners can fit up to 480GB of it on a single air-cooled PCIe card. Short version: this is not a chip built to answer one user faster. It is built to hold bigger models, longer contexts and more simultaneous sessions per card, at 350 watts.
Everything below is based on Intel's press release and product page as of October 13, 2026. All performance figures are Intel's theoretical peaks; there are no independent benchmarks yet.
Intel D270 specs at a glance
Architecture
- Intel GPU D270
- Xe3P
- Notes
- Intel's newest Xe generation
Compute
- Intel GPU D270
- 32 Xe3P cores, 256 XMX matrix engines
- Notes
- Graphics and ray-tracing area reallocated to matrix math
Memory
- Intel GPU D270
- Up to 480GB LPDDR5X
- Notes
- Intel-branded card: 160GB; 480GB on ODM partner cards
Memory bandwidth
- Intel GPU D270
- 1.5TB/s
- Notes
- No HBM
FP8 compute
- Intel GPU D270
- 1.3 PFLOPS
- Notes
- Theoretical peak
Power and cooling
- Intel GPU D270
- 350W, air-cooled
- Notes
- No liquid-cooling retrofit needed
Interface
- Intel GPU D270
- PCIe 5.0
- Notes
- Standard server slot
Model size (Intel claim)
- Intel GPU D270
- Up to 300B parameters per card; 1T+ in an 8-GPU system
- Notes
- Precision and memory config not stated
Status
- Intel GPU D270
- Customer sampling
- Notes
- No price or launch date
The detail most headlines skip: 480GB is a ceiling, not the default. A footnote in Intel's press release says the Intel-branded PCIe card has 160GB of LPDDR5X, and the design lets partners build ODM-branded cards with options up to 480GB. ServeTheHome reports Intel's card uses twenty 8GB chips, while 480GB versions rely on 24GB LPDDR5X chips. It estimates a clock speed around 2.5GHz, a 1,280-bit memory bus running near 9,375MT/s, 32MB of L2 cache and 10.2 TFLOPS of FP64 vector throughput.
Intel lists target workloads as agentic AI, long-context RAG, enterprise and coding assistants, document understanding, multimodal and diffusion models, and high-concurrency serving. On the software side it names vLLM and the PyTorch ecosystem, with SGLang and OpenAI Triton listed as supported where approved.
Why LPDDR5X instead of HBM?
HBM stacks memory right next to the GPU die and delivers very high bandwidth, but it is costly and capacity is hard to scale. Intel went the other way: accept lower bandwidth, gain a lot of capacity at lower cost and power. Whether that trade makes sense depends on which phase of LLM inference is your bottleneck.
Prefill vs decode in plain terms
- Prefill processes the whole prompt at once. It is dominated by matrix math, so compute matters. Intel pitches its 256 XMX engines as accelerating prefill, which is where long agentic prompts spend much of their time.
- Decode generates output one token at a time. Each step reads nearly all of the model weights from memory, so memory bandwidth sets the pace.
- KV cache stores attention state for the context so it is not recomputed. It grows with context length and with the number of concurrent users, and it is often what runs a card out of memory first.
Back-of-envelope: what 1.5TB/s means for tokens per second
A rough upper bound for single-stream decode speed is memory bandwidth divided by the bytes read per token. Take a 70B-parameter model at FP8, roughly 70GB of weights. Divide 1,500GB/s by 70GB and you get about 21 tokens per second as a theoretical ceiling for one user, before KV cache reads and real-world inefficiency pull it lower. This is an illustrative simplification, not an Intel benchmark.
The formula makes one thing clear: adding capacity does not make a single user's output faster. What capacity buys is batching headroom. During decode, a server can group many requests so that one pass over the weights produces a token for each of them. How many requests you can group depends on how much memory is left for their KV caches. More memory means more resident sessions, longer contexts per session, and higher aggregate tokens per second per card. That is exactly the case Intel makes on its product page when it talks about 100K-token contexts and dozens of concurrent agent sessions.
Fitting a model on one card also avoids splitting it across several GPUs, which cuts interconnect traffic and the number of cards you need.
Intel D270 vs NVIDIA RTX PRO 6000
Intel itself benchmarks its projections against the RTX PRO 6000, noting that its memory capacity comparison is made at comparable bandwidth. Here is how the published numbers line up, using NVIDIA's RTX PRO 6000 Blackwell Server Edition page.
Memory
- Intel D270
- 160GB (Intel card) / up to 480GB (ODM) LPDDR5X
- NVIDIA RTX PRO 6000 Server Edition
- 96GB GDDR7
Bandwidth
- Intel D270
- 1.5TB/s
- NVIDIA RTX PRO 6000 Server Edition
- 1,597GB/s
Listed FP8
- Intel D270
- 1.3 PFLOPS
- NVIDIA RTX PRO 6000 Server Edition
- 2 PFLOPS (NVIDIA's figure; counting methods may differ)
Power
- Intel D270
- 350W
- NVIDIA RTX PRO 6000 Server Edition
- Up to 600W, configurable
Form factor
- Intel D270
- PCIe 5.0, air-cooled
- NVIDIA RTX PRO 6000 Server Edition
- PCIe 5.0, dual-slot passive
Availability
- Intel D270
- Sampling; no price or date
- NVIDIA RTX PRO 6000 Server Edition
- Shipping product
With near-identical bandwidth, the single-user ceiling for that 70B FP8 example is about 21 tokens per second on the D270 versus about 23 on the RTX PRO 6000 (1,597 / 70). The gap is capacity: a 480GB card has five times the memory of a 96GB card, and even Intel's 160GB card has about 1.7 times as much. That leaves far more room for KV cache once the model is loaded. NVIDIA, in turn, has CUDA, higher listed compute and a product you can buy today.
Against HBM-class parts the picture is different. ServeTheHome says the D270 is not aimed at flagship chips like NVIDIA's Blackwell Ultra or AMD's MI455X, and that AMD's PCIe MI350P offers 2.3 PFLOPS of dense FP8, roughly 40% more than the D270. Its argument is that Intel is competing on performance per watt and deployability, not peak throughput.
What to check before planning around it
- Which memory config? Confirm whether a quote refers to the 160GB Intel card or a partner card up to 480GB. Every capacity and price comparison depends on it.
- Weights plus KV cache. Add model size (parameters times bytes per parameter) to the KV cache for your target context length and concurrency, and check it fits.
- Independent benchmarks. Wait for third-party results that report time to first token, per-user tokens per second, total throughput and power on the same model and settings.
- Cost per token. Divide card, server and power costs by measured throughput. The 350W air-cooled envelope matters most where rack power is the constraint.
- Software readiness. Verify that your serving stack and kernels are actually optimized for Xe3P, not just nominally supported.
- Real availability. Sampling means evaluation units exist. Watch for OEM server launches and a firm ship date.
Launch timing often surfaces on Intel's quarterly earnings calls, so it is worth keeping the next report date on your radar with theddari's earnings calendar.

Open questions and risks
- No price, no date. As of October 13, 2026, Intel only confirms customer sampling. ServeTheHome expects buyers will be looking at 2027.
- Track record. Per ServeTheHome, this is Intel's first commercial AI data center GPU since Ponte Vecchio in 2021; its planned successors Rialto Bridge (2023) and Falcon Shores (2025) were canceled.
- Vendor numbers only. Intel's footnote says its RTX PRO 6000 projections are based on public information and internal analysis as of February 2026.
- The 300B claim lacks conditions. Do not assume a 160GB card can do what a 480GB card can.
- Ecosystem depth. Intel promises portability across its Xe GPUs and day-zero support for new open models, but serving performance will hinge on kernel maturity.
AI hardware launches attract a wave of hot takes within hours. Following the AI channel feed on theddari's Telegram trends page, along with the blog trends view, is a quick way to see which claims are spreading and which are actually sourced.
Bottom line
The Intel D270 is a bet that inference economics will be decided by memory capacity, power and drop-in server compatibility rather than peak speed. For long-context, high-concurrency workloads like agent fleets, that bet is reasonable on paper. As of October 2026, though, price, ship date and independent results are all missing, so treat it as a clearly specified design direction rather than a proven alternative. Separate the 160GB and 480GB configurations in any analysis, and judge it on measured prefill, decode and cost-per-token numbers once they arrive.
よくある質問
Is the Intel D270 a gaming graphics card?
How big a model fits on one Intel D270?
When can you buy the Intel D270, and how much does it cost?
Is LPDDR5X slower than HBM for AI inference?
出典・参考資料
- 1Intel Accelerates Open Infrastructure for the Agentic AI Era (Intel press release, Oct 12, 2026)(新しいタブで開きます)www.intc.com
- 2Intel GPU D270 | Inference-Optimized Data Center GPU (Intel product page)(新しいタブで開きます)www.intel.com
- 3Intel's Crescent Island AI Server GPU Gets a Name and Specs: Meet the Intel GPU D-Series (ServeTheHome)(新しいタブで開きます)www.servethehome.com
- 4NVIDIA RTX PRO 6000 Blackwell Server Edition (NVIDIA product page)(新しいタブで開きます)www.nvidia.com
関連記事
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.