DeepSeek V4.1 Flash 1017: Specs, API Pricing, Local Setup
DeepSeek V4.1 Flash 1017 explained: MIT open weights, 1M context, what changed from V4.1 Flash, official API and OpenRouter pricing, and local hardware limits.
目次7セクション
要点
- DeepSeek V4.1 Flash 1017 is a minor update to V4.1 Flash (released September 10, 2026). It went live on DeepSeek's web app, mobile app and API on October 17, 2026, with MIT-licensed weights.
- On the official API, the model name deepseek-flash now points to this checkpoint: 1M-token context, up to 384K output tokens, vision, tool calls and JSON output.
- Official off-peak pricing is $0.15 per million input tokens (cache miss) and $0.60 per million output tokens; peak hours cost twice as much.
- Hugging Face lists 763B parameters, mostly stored in 8-bit formats, so running the full model locally means a multi-GPU server, not a laptop.
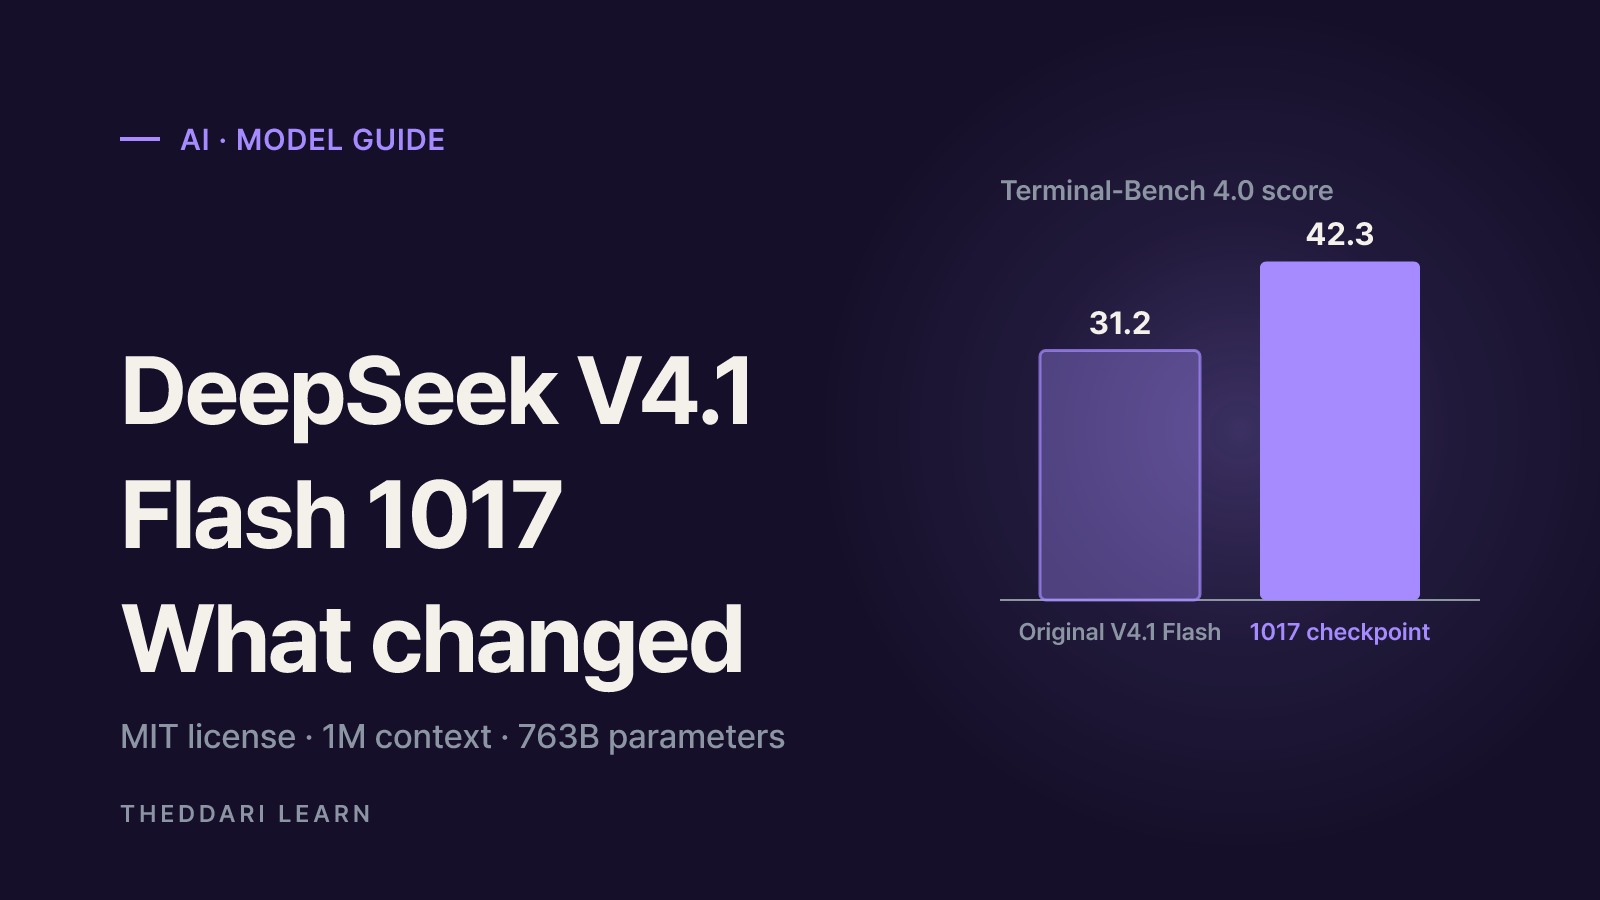
- The benchmark jumps, such as Terminal-Bench 4.0 rising from 31.2 to 42.3, are DeepSeek's own numbers. Test on your own workload before switching.
DeepSeek V4.1 Flash got a dated refresh on October 17, 2026: DeepSeek-V4.1-Flash-1017. DeepSeek calls it a minor update, yet its own benchmark table shows double-digit gains on some agentic coding tests, and the same day it became the default model behind DeepSeek's website, app and API. The weights are on Hugging Face under the MIT License. This guide sticks to what the official model card and API docs say as of October 2026, then walks through what to check before you call it via API or try to run it locally.
Short answer: for most developers, the practical path is the official API or OpenRouter. The full checkpoint is listed at 763B parameters, which puts local inference in multi-GPU server territory, and every benchmark gain is self-reported until independent tests catch up.
What is DeepSeek V4.1 Flash 1017?
The "1017" suffix is simply the release date, October 17. The original V4.1 Flash shipped on September 10, 2026, and 1017 is a newer checkpoint of the same model line. According to the model card, it improves reasoning, coding, agentic and visual benchmarks while cutting task execution time and output length, which DeepSeek frames as finishing tasks faster at lower cost.
| Item | What the model card and docs say |
|---|---|
| Release | October 17, 2026 (web, app and API at once) |
| License | MIT, covering repository and weights |
| Size | 763B parameters in the Hugging Face Safetensors metadata |
| Tensor types | Mixed BF16, F32, F8_E4M3 and I8 |
| Modalities | Image and text in, text out |
| Context | 1M tokens; recommended max_tokens of at least 256K |
| Sampling | temperature 1.0, top_p 1.0 |
| Chat template | None in Jinja format; use the Python reference encoder |
Why you see both 552B and 763B
The original V4.1 Flash model card describes a Mixture-of-Experts model with 552B backbone parameters plus a separate 196B-parameter Engram conditional memory. Only 8B parameters are active per token during prefill (reading your prompt) and 16B during decode (writing the answer). The 763B figure in the Hugging Face metadata appears to count the stored files, including those extra components. The 1017 card does not restate active parameters or say whether the architecture changed. For hardware planning, go by the actual download size, not the headline parameter count.
The architecture in one paragraph
The V4.1 line is built around KV cache compression. The original card describes a 40-layer causal encoder-decoder (20 encoder layers, 20 decoder layers), Compressed Sparse Attention 2 and an FP4 KV cache, bringing the global KV cache down to about 890 bytes per token, roughly a quarter of DeepSeek V4 Flash. That is what makes a 1M-token window cheap enough to serve. It also exposes a reasoning-effort setting from 1 to 100 so you can trade cost for accuracy.
What changed from the original V4.1 Flash
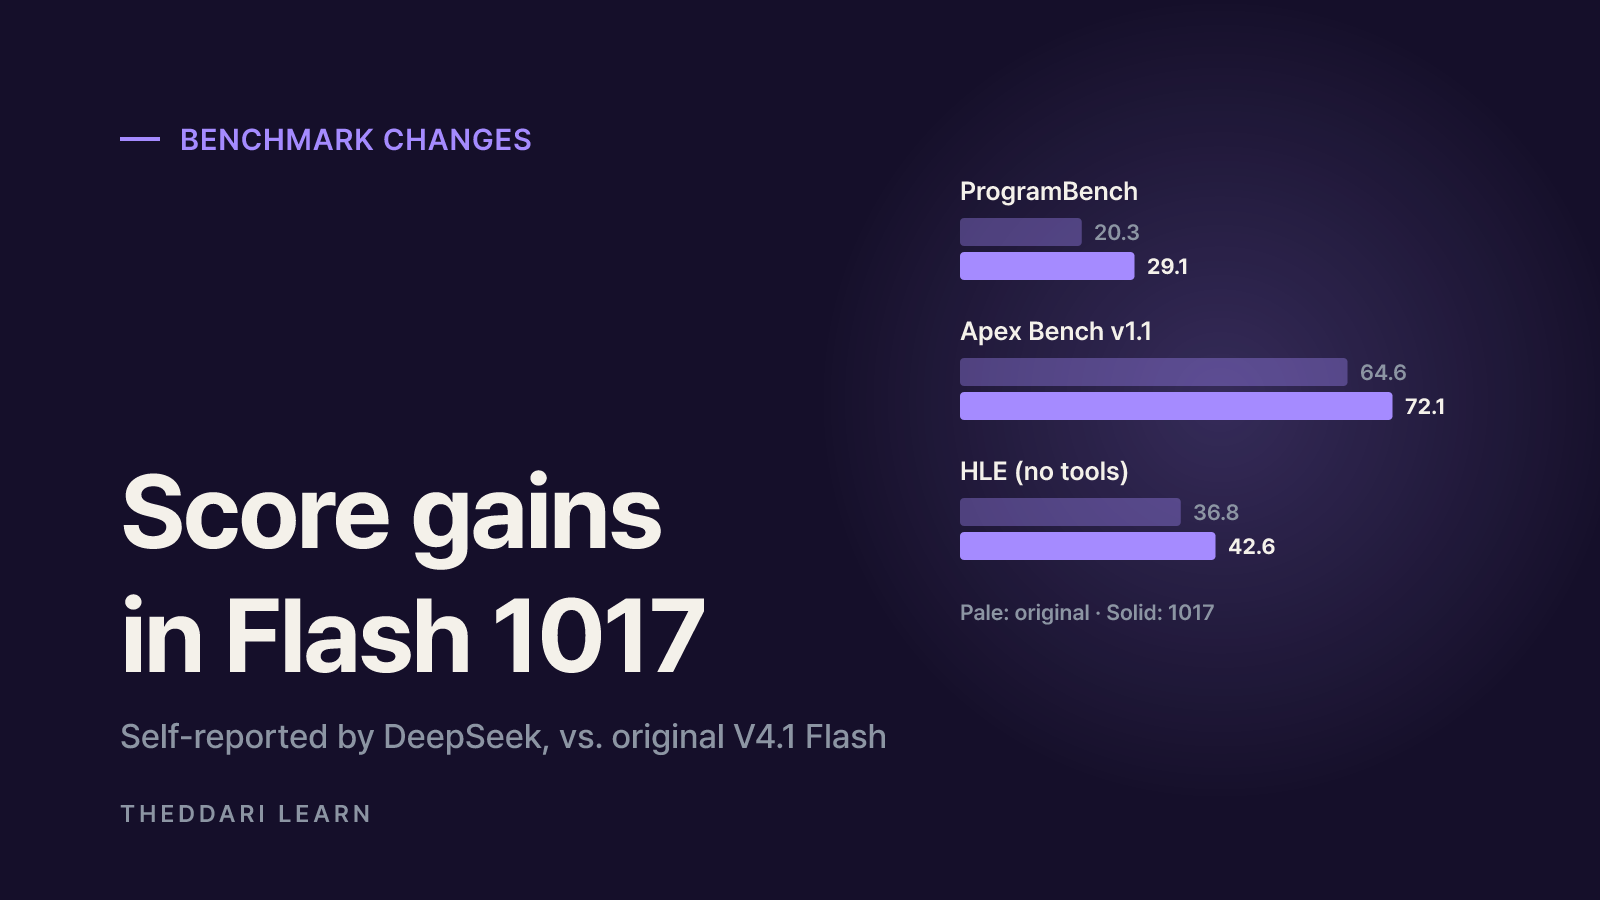
The 1017 card compares the new checkpoint with the previous one on the same benchmarks. The biggest moves are in terminal tasks and program generation.
Terminal-Bench 4.0
- V4.1 Flash
- 31.2
- V4.1 Flash 1017
- 42.3
- Change
- +11.1
HLE (no tools)
- V4.1 Flash
- 36.8
- V4.1 Flash 1017
- 42.6
- Change
- +5.8
DeepSWE v1.1
- V4.1 Flash
- 74.2
- V4.1 Flash 1017
- 77.0
- Change
- +2.8
ProgramBench
- V4.1 Flash
- 20.3
- V4.1 Flash 1017
- 29.1
- Change
- +8.8
Apex Bench v1.1
- V4.1 Flash
- 64.6
- V4.1 Flash 1017
- 72.1
- Change
- +7.5
Automation-Bench
- V4.1 Flash
- 54.8
- V4.1 Flash 1017
- 60.5
- Change
- +5.7
Agents' Last Exam
- V4.1 Flash
- 31.8
- V4.1 Flash 1017
- 35.4
- Change
- +3.6
Keep two caveats in mind. First, these are DeepSeek's own measurements. Second, the harness matters: Terminal-Bench 4.0 was run with the Claude Code harness and DeepSWE v1.1 with Mini-SWE-V2. On the original V4.1 Flash card, DeepSWE scores ranged from 65.5 to 74.2 depending on which agent scaffold was used. Your editor plugin or coding agent may not see the same lift.
DeepSeek's release note says the model is optimized for DeepSeek Harness, Tencent CodeBuddy and WorkBuddy, and recommends DeepSeek Harness v0.2.1-rc.1 or later.
Using it via the DeepSeek API or OpenRouter
Official DeepSeek API
On the Models & Pricing page, the model name deepseek-flash maps to DeepSeek-V4.1-Flash-1017. The OpenAI-format base URL is https://api.deepseek.com and the Anthropic-format base URL is https://api.deepseek.com/anthropic. Thinking mode is on by default and can be switched off. The model supports JSON output, tool calls, the Responses API, the Anthropic API and vision input; FIM completion works in non-thinking mode only. Context length is 1M tokens and maximum output is 384K.
One thing to watch: the legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp still work, but those models are retired and requests now run on the 1017 checkpoint. If you have production prompts, rerun your regression tests even though nothing in your code changed.
Input, cache hit
- Off-peak
- $0.003
- Peak
- $0.006
Input, cache miss
- Off-peak
- $0.15
- Peak
- $0.3
Output
- Off-peak
- $0.6
- Peak
- $1.2
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. Everything else, including weekends, is off-peak at half price. For US users that peak window falls in the late evening and early morning Eastern time, so daytime batch jobs in the Americas often land in off-peak hours anyway; in Europe the 06:00 to 10:00 UTC block overlaps the start of the workday. The concurrency limit is listed as 2,500. The new Search and Fetch APIs cost $0.75 per 1,000 successful requests each, and server-side search calls from DeepSeek Harness, Claude Code and Codex become billable at 16:00 UTC on October 31, 2026.
OpenRouter
OpenRouter exposes the model as deepseek/deepseek-v4.1-flash-1017 on its OpenAI-compatible endpoint, https://openrouter.ai/api/v1/chat/completions. The dated ID pins this exact checkpoint, and the page lists support for parameters such as reasoning, tools and response_format. As of October 2026 the model is not available through EU in-region routing, and the serving provider can vary, so check the model page for current pricing and latency before you commit.
- 1
Create a key and cap spending
Set a low credit balance or spend limit first. A long prompt near the 1M context limit plus a long thinking-mode answer can make a single call far more expensive than you expect.
- 2
Decide whether to pin the version
Use deepseek-flash if you want automatic upgrades; use a dated ID such as the OpenRouter one if you need reproducible behavior.
- 3
Run a small comparison
Send 20 to 30 of your real prompts to the old and new models and compare accuracy, output length and tool-call formatting.
- 4
Review data handling
Before sending source code or personal data, read the provider's retention and training-use terms and your organization's AI policy.
Before you run DeepSeek V4.1 Flash locally
Open weights do not mean laptop-friendly. Here is what to check before downloading.
- Memory: 763B parameters at one byte each is already hundreds of gigabytes, before KV cache and runtime overhead. Plan on a multi-GPU data-center server; a single consumer GPU or a MacBook will not run the full checkpoint.
- Runtime support: Hugging Face shows vLLM and SGLang serving snippets, but DeepSeek points to the inference folder in the repository for weight conversion and local inference. This is a new architecture, so confirm your runtime version supports it.
- No Jinja chat template: The usual apply_chat_template flow may not work. Use the repository's encoding.py or DeepSeek's deepseek-recipe library so that thinking mode and tool calls are encoded correctly.
- Long outputs: The recommended max_tokens is at least 256K. Short limits can cut thinking-mode answers off midway, and long ones need generous memory and timeouts.
- Quantized builds: Community quantizations are already listed on Hugging Face, but they are not official. Check the publisher, measured quality loss and whether llama.cpp, Ollama or LM Studio actually supports the architecture.
- Hosted inference: When checked in October 2026, the Hugging Face page said no Inference Provider was serving this model yet.
Risks and limits to weigh
- Self-reported results: All benchmark numbers come from DeepSeek, and competitor scores in the same table may not use identical settings.
- Silent model swaps: Aliases like deepseek-flash can change under you. If outputs shift suddenly, check the model version first.
- Cost creep: Shorter outputs help, but 1M-token prompts and thinking mode still add up quickly, and peak pricing is double.
- Data and compliance: Calls to the official API are processed on DeepSeek's infrastructure. Some employers and public bodies restrict specific AI vendors, so check your policy and your legal basis for any personal data. Self-hosting the open weights avoids that transfer but raises operating costs.
- Price changes: DeepSeek's docs state that prices may change. Figures here were checked in October 2026.
Model news moves fast, and first-week user reports often matter more than launch charts. To follow what AI builders are saying about new releases, the Telegram AI channel tracker and the blog dashboard below are good starting points.

Bottom line: DeepSeek V4.1 Flash 1017 pairs MIT-licensed weights and a 1M-token context with low API prices. Test it through the API during off-peak hours, compare it against the version you use today, and only then decide whether self-hosting is worth the hardware.
よくある質問
Is DeepSeek V4.1 Flash 1017 open source?
Do I need to change my code if I already use deepseek-v4-flash?
What hardware do I need to run DeepSeek V4.1 Flash 1017 locally?
Should I use the DeepSeek API or OpenRouter?
出典・参考資料
- 1deepseek-ai/DeepSeek-V4.1-Flash-1017 model card (Hugging Face)(新しいタブで開きます)huggingface.co
- 2deepseek-ai/DeepSeek-V4.1-Flash model card (Hugging Face)(新しいタブで開きます)huggingface.co
- 3DeepSeek API Docs: Models & Pricing(新しいタブで開きます)api-docs.deepseek.com
- 4DeepSeek API Docs: DeepSeek-V4.1-Flash-1017 Release (2026/10/17)(新しいタブで開きます)api-docs.deepseek.com
- 5OpenRouter: DeepSeek V4.1 Flash 1017(新しいタブで開きます)openrouter.ai
関連記事
 AI
Anthropic's Riemann Hypothesis Proof: Is It Verified?
On November 20, 2026, Anthropic researcher Levent Alpöge said he had proved the Riemann Hypothesis with Claude. A day later the Lean and Mathlib communities certified the formal proof. What that means, what is still missing, and a checklist for judging big proof claims.
 AI
AgentRoboCritic: Can Frontier AI Agents Control Robots?
A November 2026 arXiv study from Carnegie Mellon, UIUC and Bosch scores every action a frontier AI agent sends to a robot. Here is what it found about recovery, grasping, alignment, zero-shot success and latency, and how far to trust it.
 AI
Inkling 2 Mini vs Inkling 2 Small: Specs, Local Use, Limits
Thinking Machines released Inkling 2 Mini on November 20, 2026: a 26.4B-parameter open-weights model with a ~20GB checkpoint that runs on 32GB Macs. Here is how it compares with Inkling 2 Small and what to check before you deploy it.